
surrey-nlp/diallm-llama-gspo-aus
024
DiaLLM — Llama 3.1-8B — AUS — GSPO
Built with Llama.
Part of DiaLLM: An Investigation into the Robustness-Generation Gap in English Dialect Adaptation (EMNLP 2026 Main).
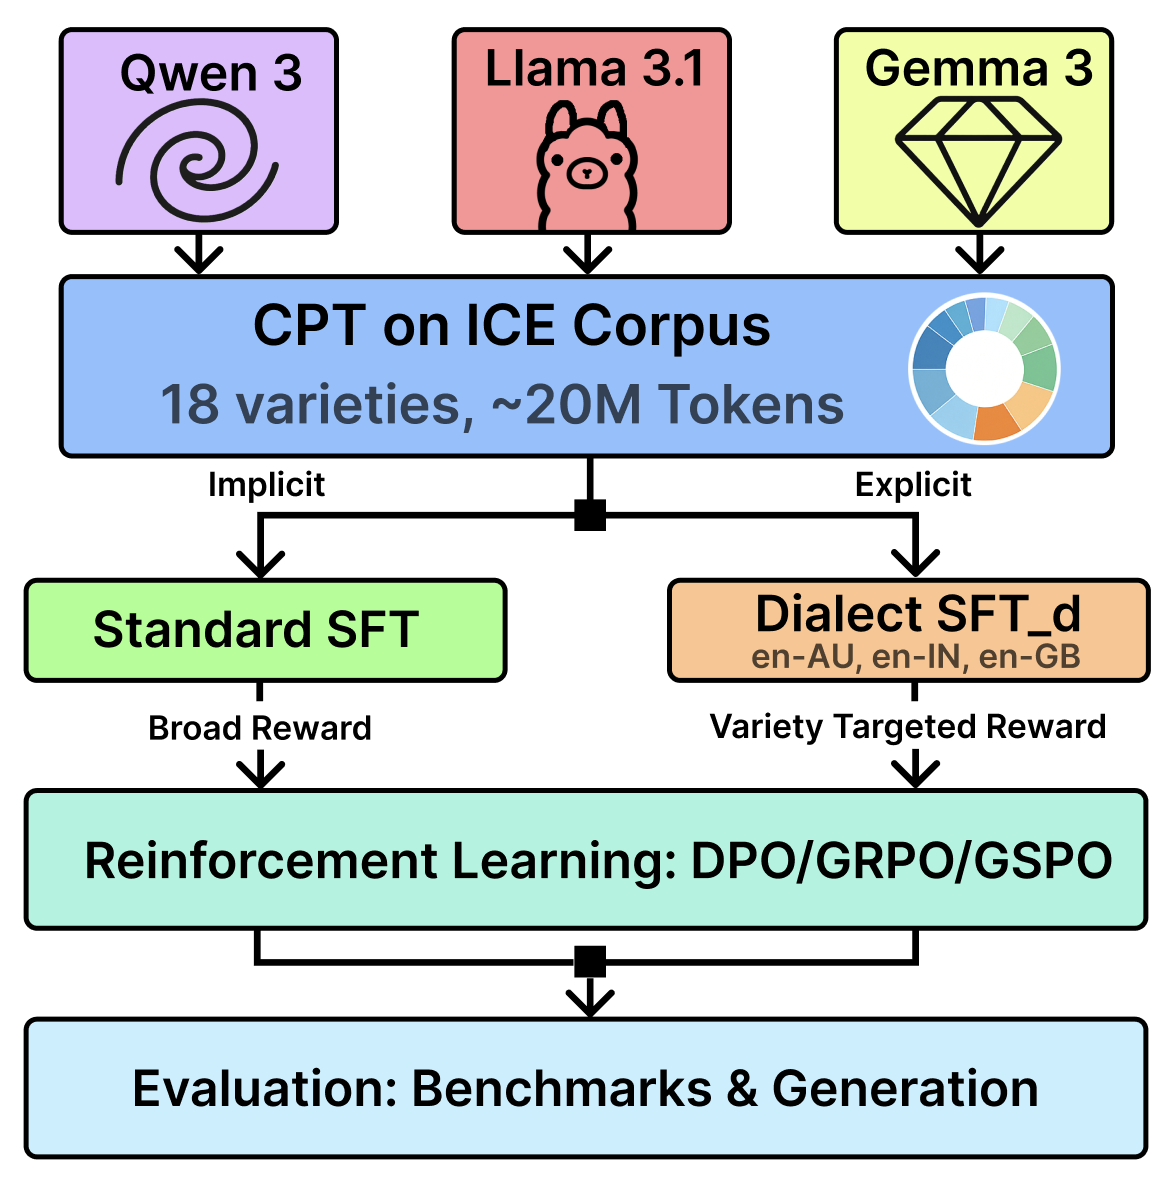
- Base model: Llama 3.1-8B
- Target variety: en-AU (Australian English)
- Adaptation thread: explicit (variety-targeted)
- Alignment method: GSPO
Continually pretrained on the International Corpus of English (18 varieties, ~20M tokens), then adapted via the explicit thread: dialect-specific SFT on Multi-VALUE-transformed en-AU preference data, followed by GSPO with the target-variety preference pairs.
Code, checkpoints, preference datasets, linguistic-analysis toolkit: https://github.com/surrey-nlp/diallm
Paper: https://arxiv.org/abs/2607.07669
This model is a fine-tuned version of jordanpainter/diallm-llama-sft-aus, trained using TRL.
Quick start
from transformers import pipeline

question = "If you had a time machine, but could only go to the past or the future once and never return, which would you choose and why?"
generator = pipeline("text-generation", model="surrey-nlp/diallm-llama-gspo-aus", device="cuda")
output = generator([{"role": "user", "content": question}], max_new_tokens=128, return_full_text=False)[0]
print(output["generated_text"])
Training procedure
This model was trained with GSPO.
Framework versions
- TRL: 0.28.0
- Transformers: 4.57.6
- Pytorch: 2.5.1+cu121
- Datasets: 4.5.0
- Tokenizers: 0.22.2
Citation
@article{painter2026diallm,
  title     = {DiaLLM: An Investigation into the Robustness-Generation Gap in English Dialect Adaptation},
  author    = {Painter, Jordan and Srirag, Dipankar and Kappiyath, Adarsh and Kanojia, Diptesh and Joshi, Aditya and Yin, Lu},
  year      = {2026},
  eprint    = {2607.07669},
  archivePrefix = {arXiv}
}@article{zheng2025groupsequencepolicyoptimization,
title = {{Group Sequence Policy Optimization}},
author = {Chujie Zheng and Shixuan Liu and Mingze Li and Xiong-Hui Chen and Bowen Yu and Chang Gao and Kai Dang and Yuqiong Liu and Rui Men and An Yang and Jingren Zhou and Junyang Lin},
year = 2025,
eprint = {arXiv:2507.18071}
}@software{vonwerra2020trl,
title = {{TRL: Transformers Reinforcement Learning}},
author = {von Werra, Leandro and Belkada, Younes and Tunstall, Lewis and Beeching, Edward and Thrush, Tristan and Lambert, Nathan and Huang, Shengyi and Rasul, Kashif and Gallouédec, Quentin},
license = {Apache-2.0},
url = {https://github.com/huggingface/trl},
year = {2020}
}