
sd-community/sdxl-flash-lora
1361
[SDXL Flash](https://huggingface.co/sd-community/sdxl-flash) with LoRA in collaboration with [Project Fluently](https://hf.co/fluently)

Introducing the new fast model SDXL Flash, we learned that all fast XL models work fast, but the quality decreases, and we also made a fast model, but it is not as fast as LCM, Turbo, Lightning and Hyper, but the quality is higher. Below you will see the study with steps and cfg.
--> Work with LoRA <--
- Trigger word:
<lora:sdxl-flash-lora:0.55>- Optimal LoRA multiplier: 0.45-0.6 (the best - 0.55)
- Optimal base model: fluently/Fluently-XL-v4
Steps and CFG (Guidance)
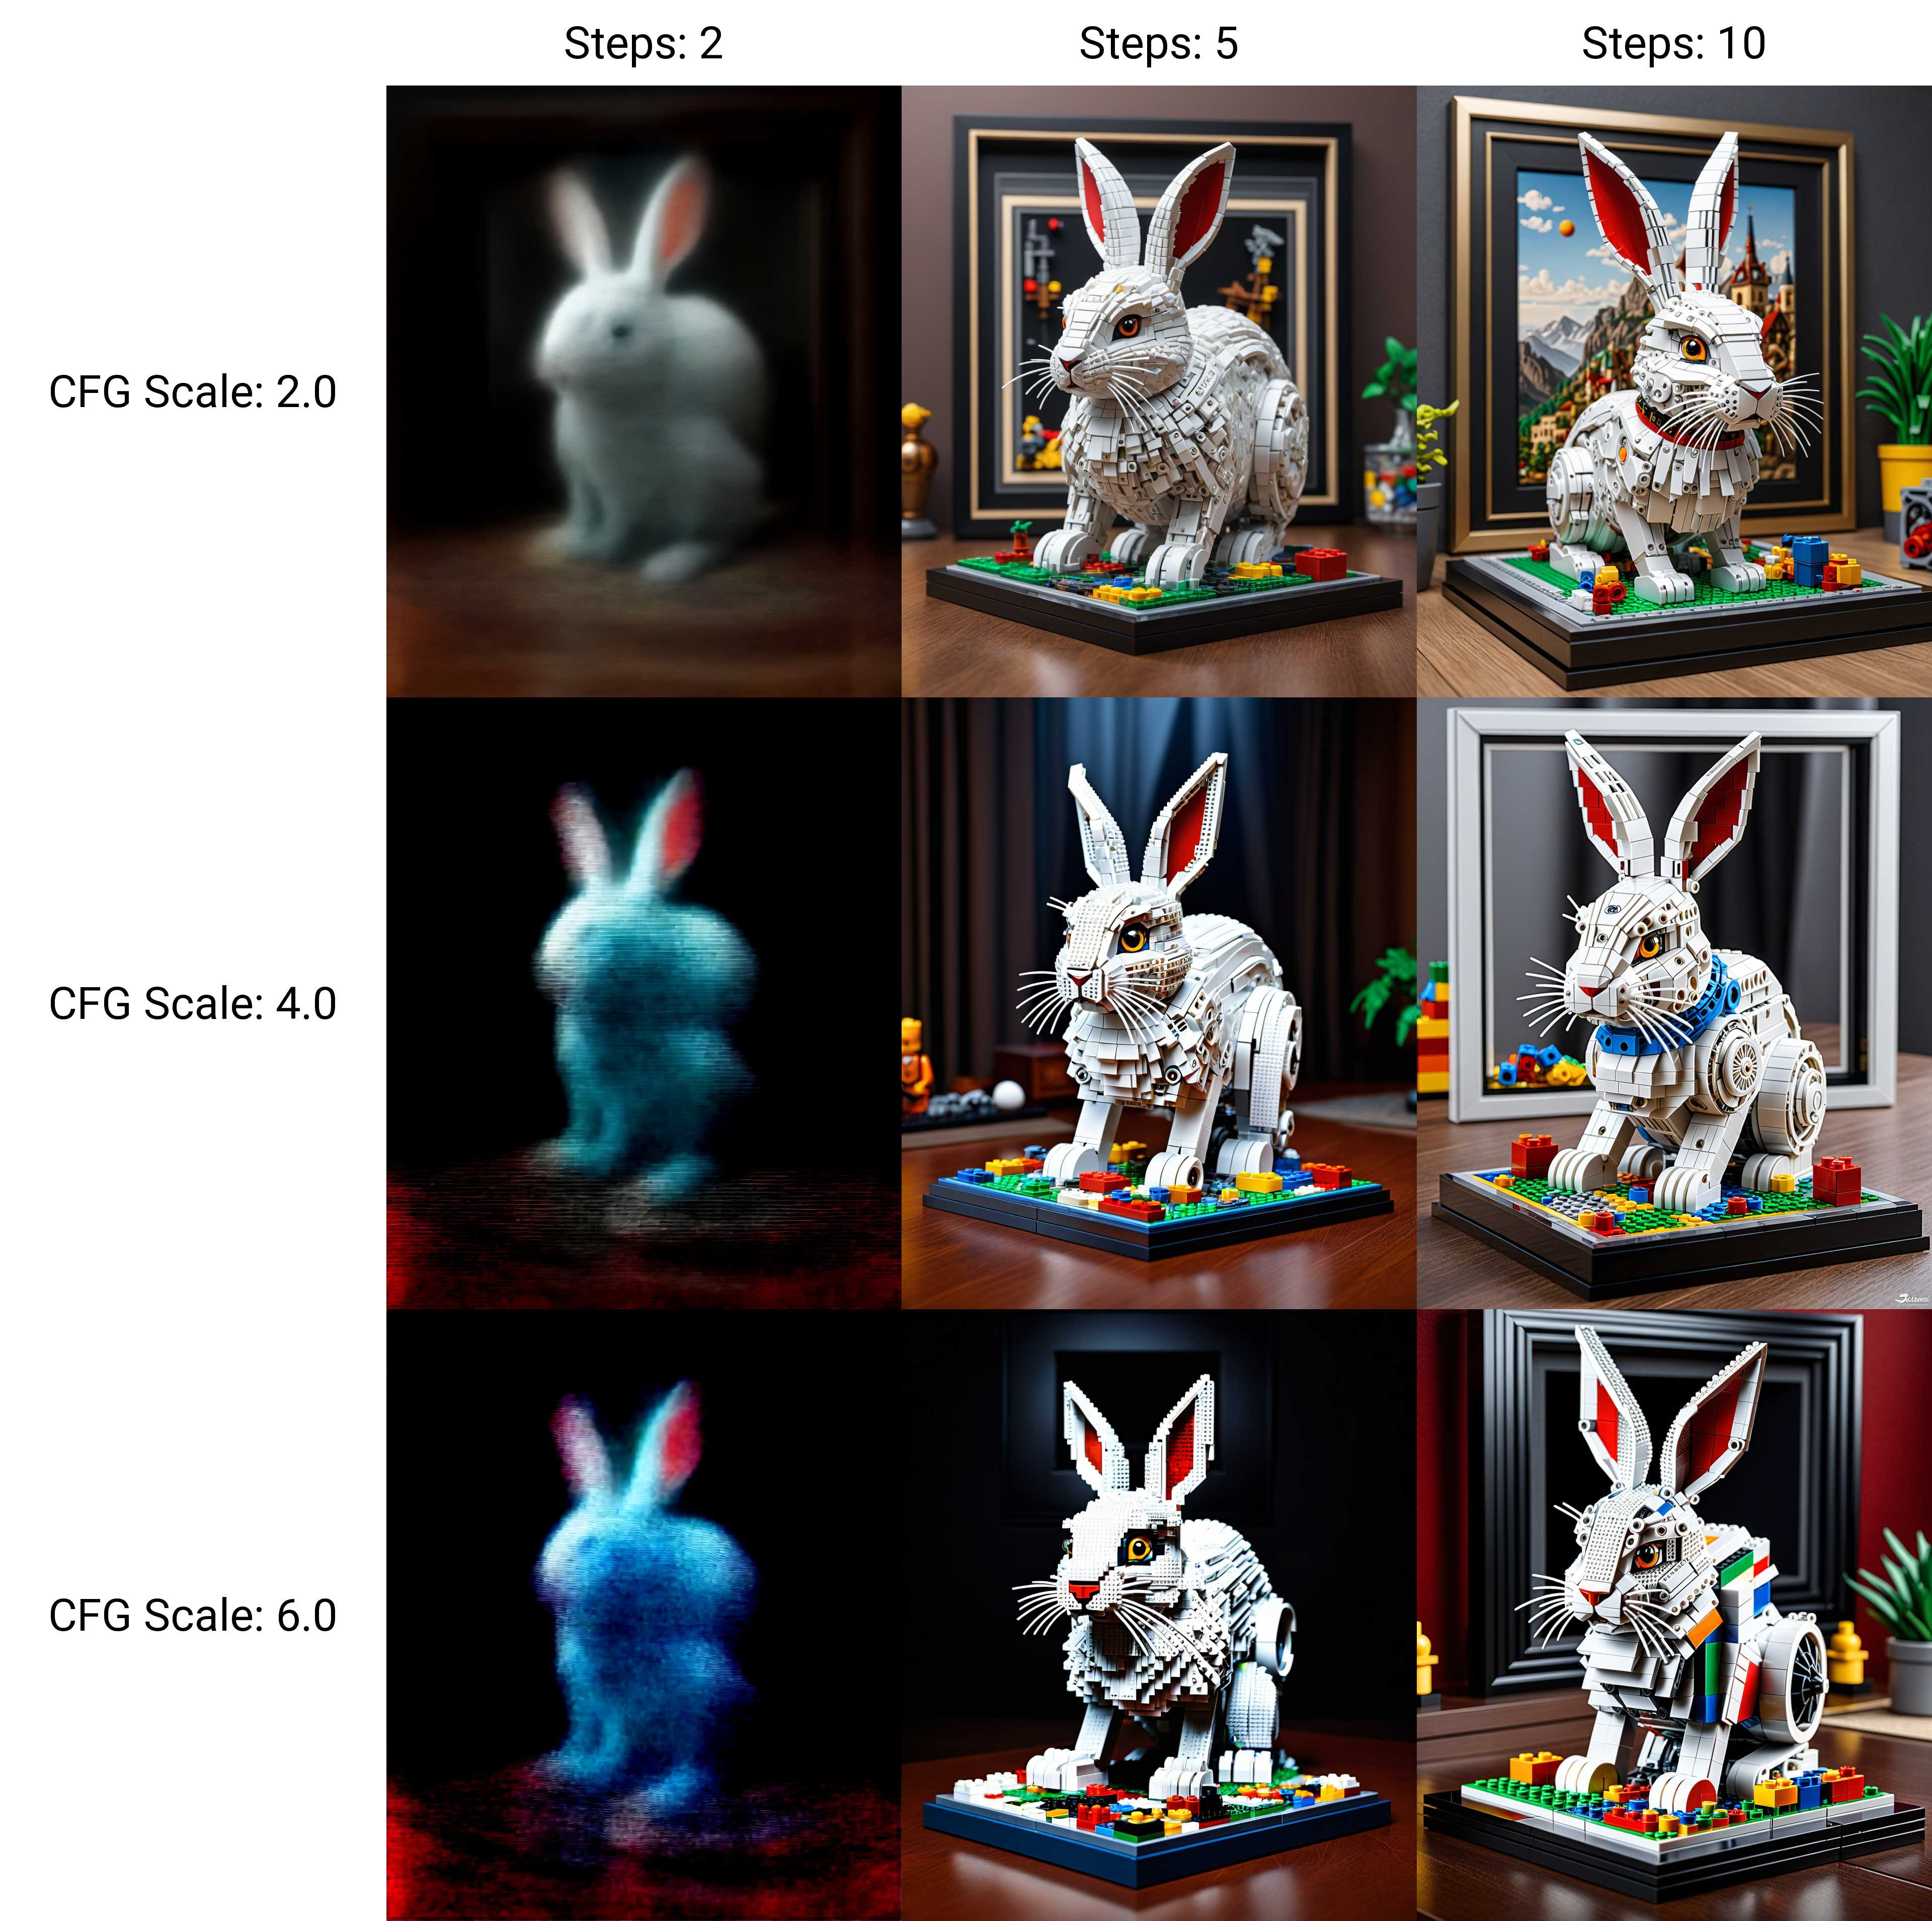
Optimal settings
- Steps: 6-9
- CFG Scale: 2.5-3.5
- Sampler: DPM++ SDE
Diffusers usage
pip install torch diffusersimport torch
from diffusers import StableDiffusionXLPipeline, DPMSolverSinglestepScheduler
# Load model.
pipe = StableDiffusionXLPipeline.from_pretrained("sd-community/sdxl-flash", torch_dtype=torch.float16).to("cuda")
# Ensure sampler uses "trailing" timesteps.
pipe.scheduler = DPMSolverSinglestepScheduler.from_config(pipe.scheduler.config, timestep_spacing="trailing")
# Image generation.
pipe("a happy dog, sunny day, realism", num_inference_steps=7, guidance_scale=3).images[0].save("output.png")