
pierreguillou/whisper-medium-french
<!-- This model card has been generated automatically according to the information the Trainer had access to. You should probably proofread and complete it, then remove this comment. -->
French Medium Whisper
This model is a fine-tuned version of openai/whisper-medium on the commonvoice11_0 dataset. It achieves the following results on the evaluation set:
- Loss: 0.2664
- Wer (without normalization): 15.8969
- Wer (with normalization): 11.1406
Blog post
All information about this model in this blog post: Speech-to-Text & IA | Transcreva qualquer áudio para o português com o Whisper (OpenAI)... sem nenhum custo!.
New SOTA
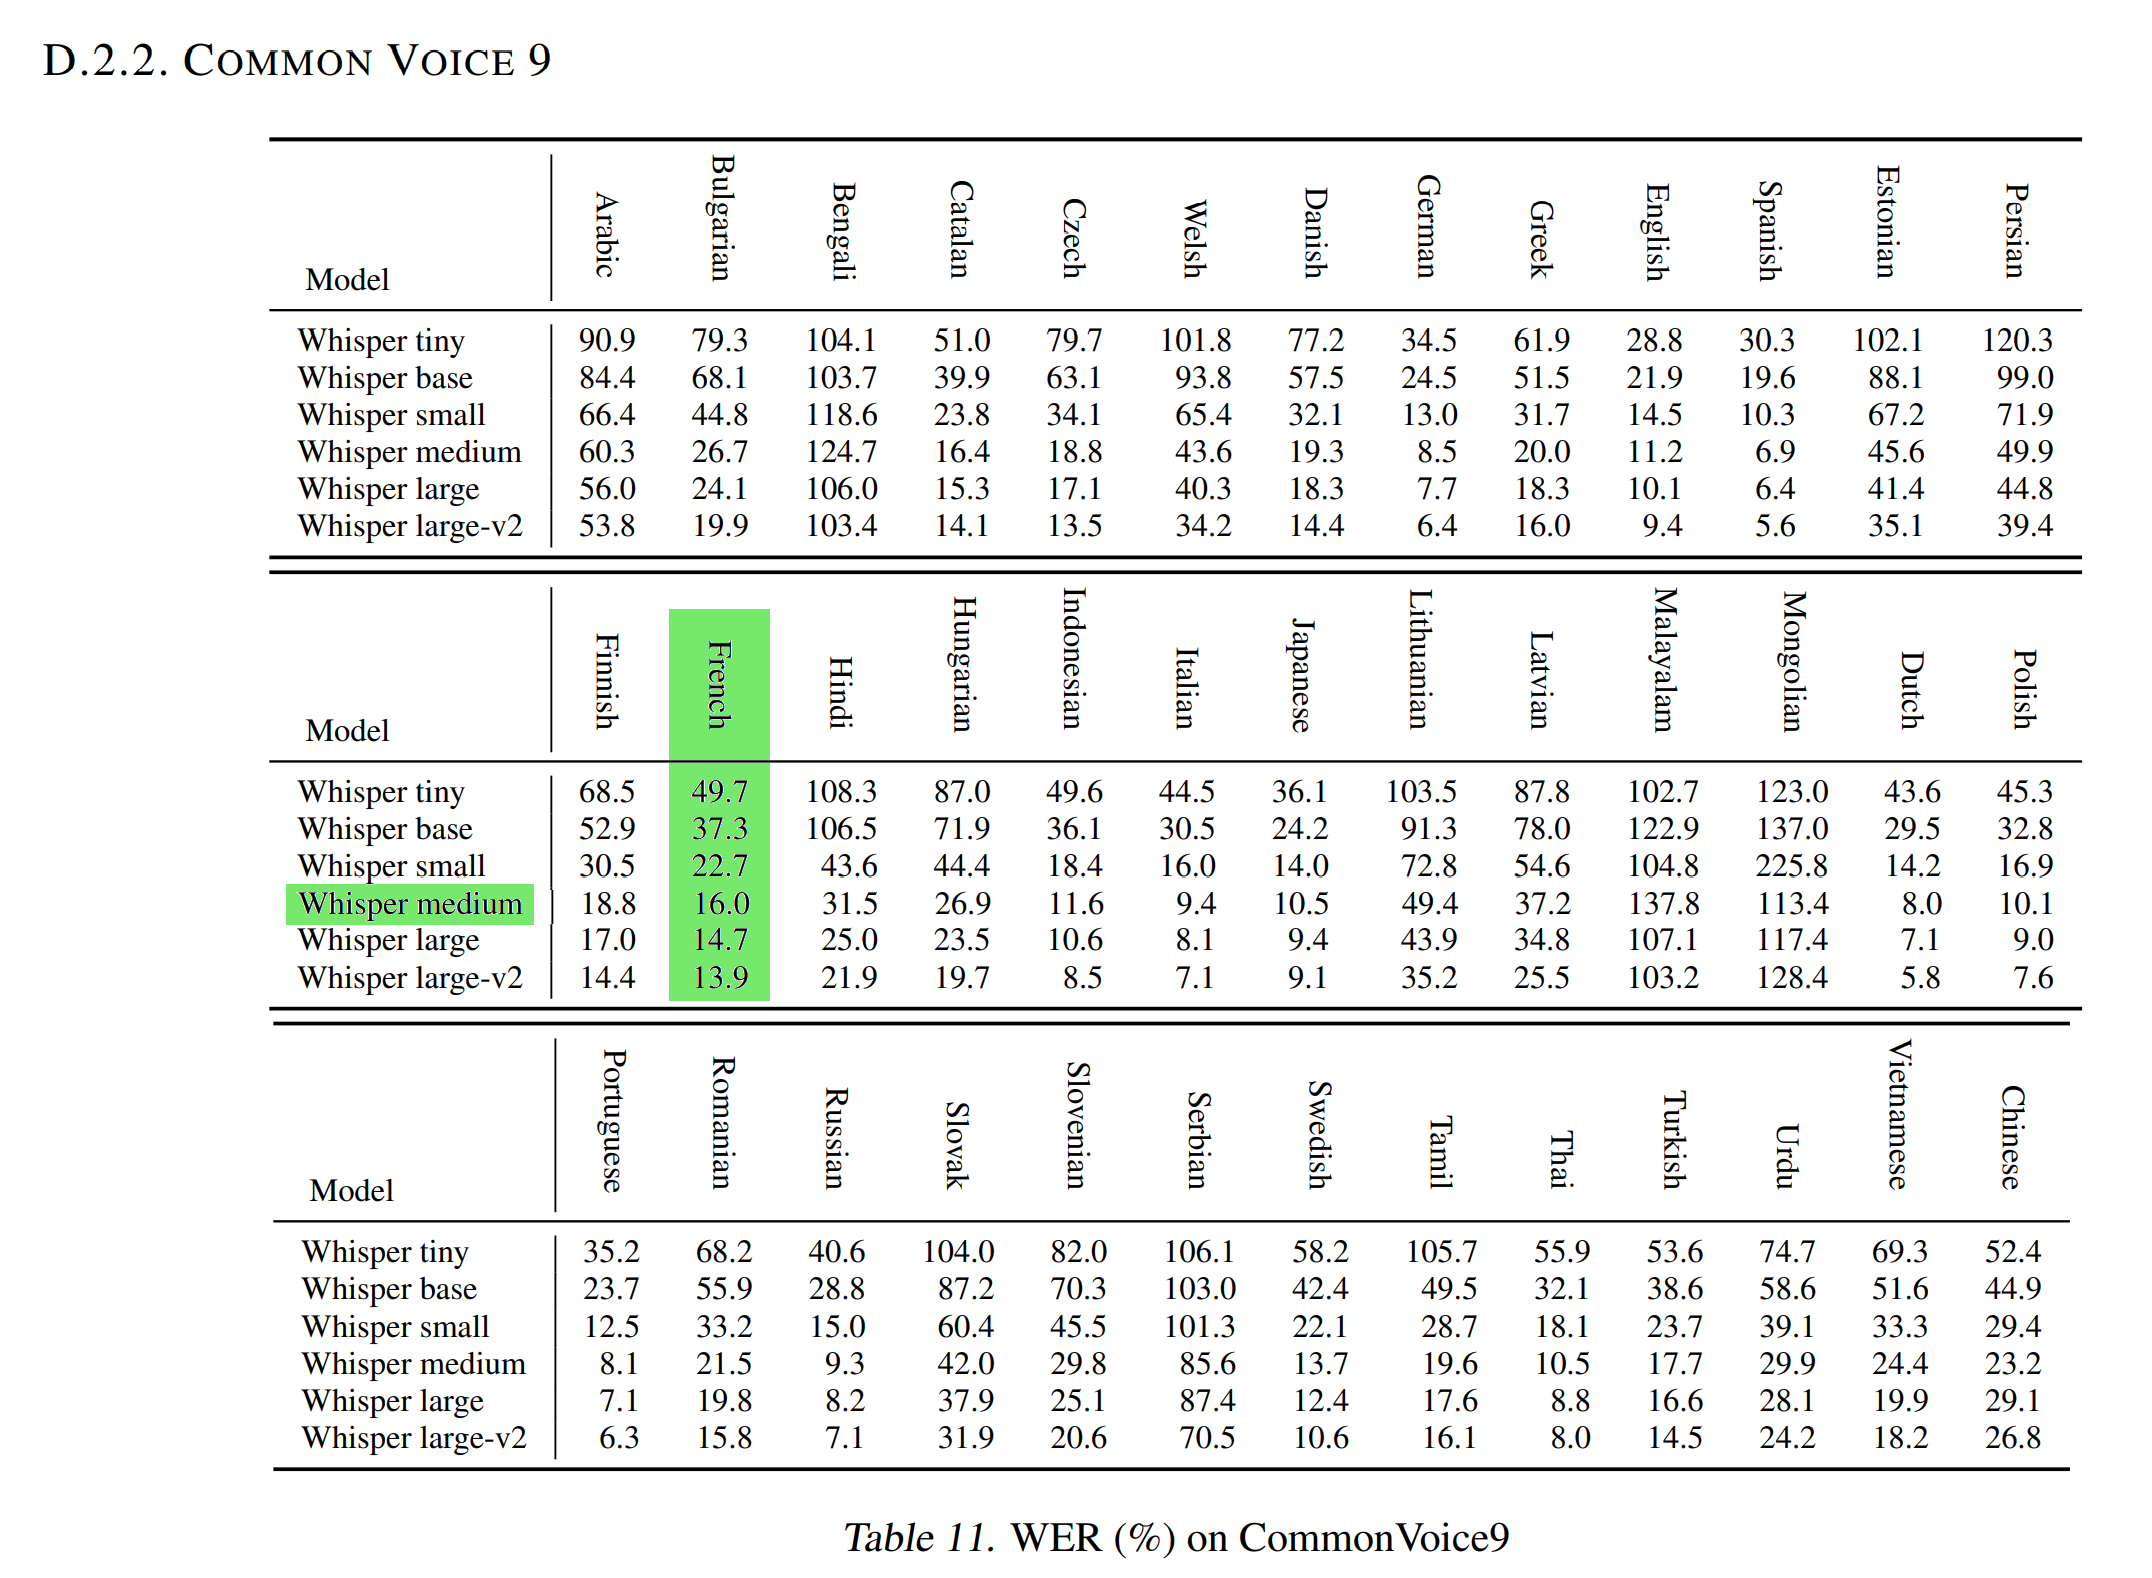
The Normalized WER in the OpenAI Whisper article with the Common Voice 9.0 test dataset is 16.0.
As this test dataset is similar to the Common Voice 11.0 test dataset used to evaluate our model (WER and WER Norm), it means that our French Medium Whisper is better than the [Medium Whisper](https://huggingface.co/openai/whisper-medium) model at transcribing audios French in text.
Training procedure
Training hyperparameters
The following hyperparameters were used during training:
- learning_rate: 1e-05
- trainbatchsize: 32
- evalbatchsize: 16
- seed: 42
- optimizer: Adam with betas=(0.9,0.999) and epsilon=1e-08
- lrschedulertype: linear
- lrschedulerwarmup_steps: 500
- training_steps: 5000
- mixedprecisiontraining: Native AMP
Training results
Framework versions
- Transformers 4.26.0.dev0
- Pytorch 1.13.0+cu117
- Datasets 2.7.1.dev0
- Tokenizers 0.13.2