
osunlp/WebJudge-7B
<style> img { display: inline; } </style>
 |  | 
WebJudge
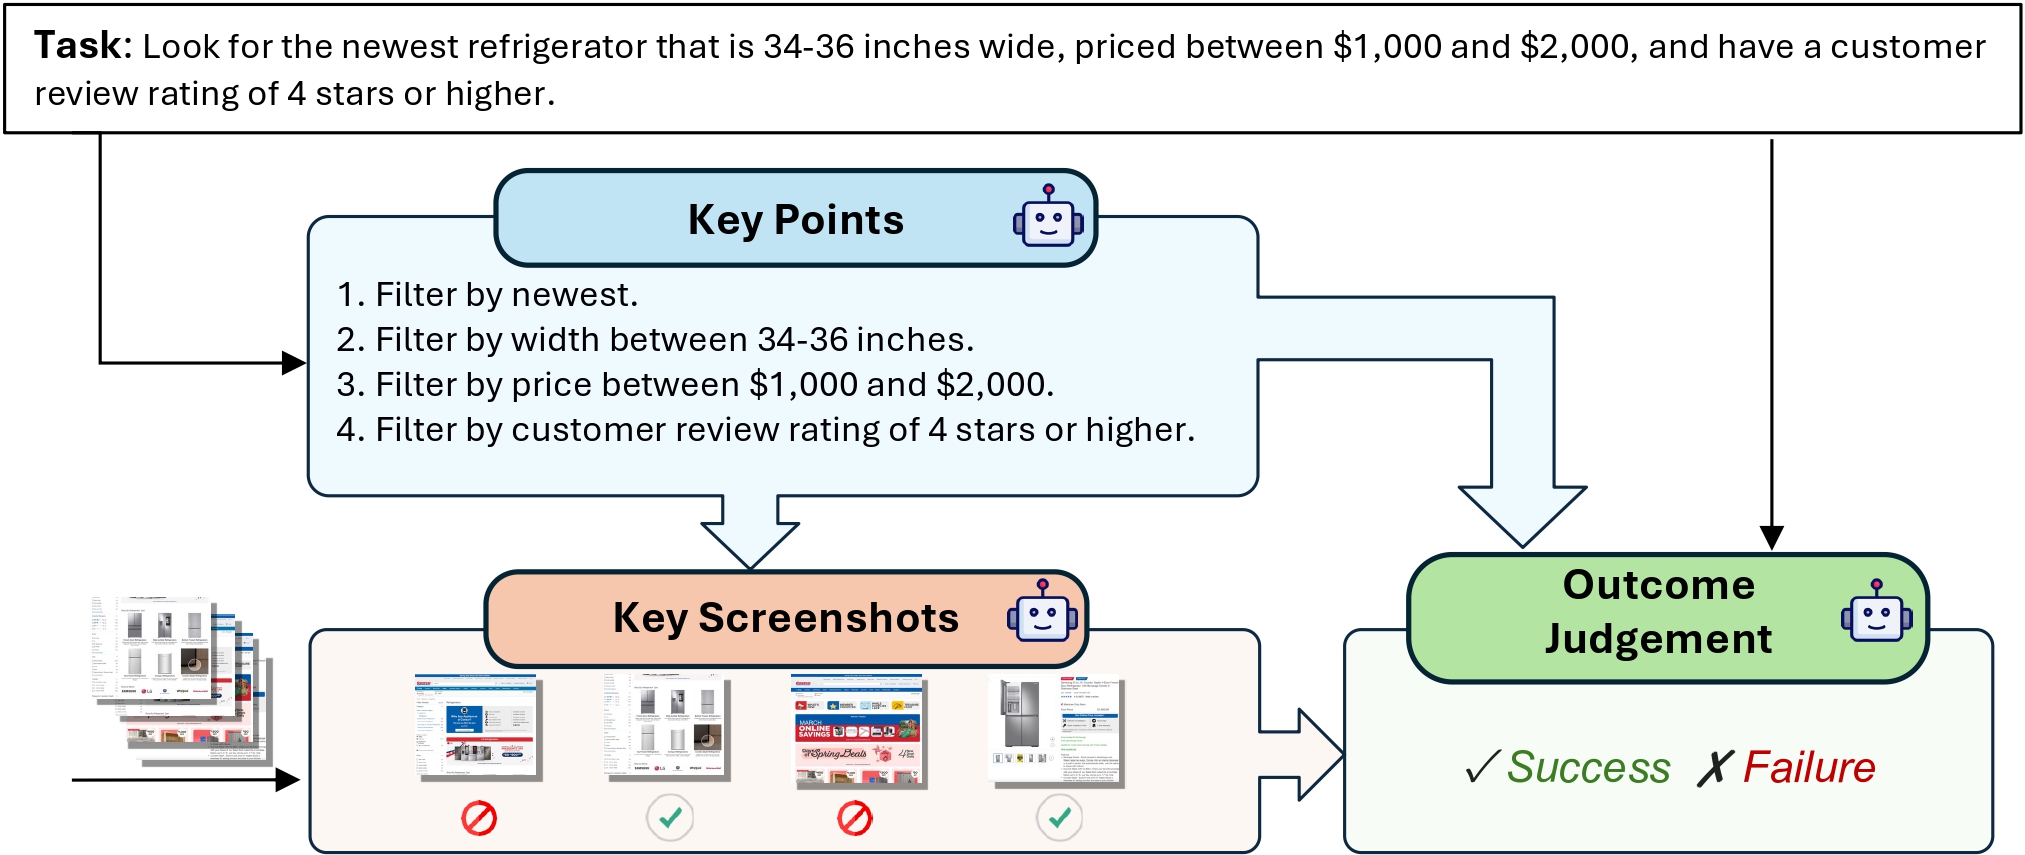
WebJudge preserves critical intermediate screenshots while mitigating the token overload issue, resulting in more accurate and reliable evaluations. Please check our paper for more details.
- [Repository](https://github.com/OSU-NLP-Group/Online-Mind2Web)
- 📃 [Paper](https://arxiv.org/abs/2504.01382)
- 🏆 [Leaderboard](https://huggingface.co/spaces/osunlp/Online_Mind2Web_Leaderboard)
- 🤗 [Data](https://huggingface.co/datasets/osunlp/Online-Mind2Web)
- [Model](https://huggingface.co/osunlp/WebJudge-7B)
Results
Comparison against Existing Evaluation Methods on Online-Mind2Web
<table> <tr> <th>Model</th> <th>Auto-Eval</th> <td>SeeAct</td> <td>Agent-E</td> <td>Browser Use</td> <td>Claude 3.5 </td> <td>Claude 3.7</td> <td>Operator</td> <th>Avg AR</th> </tr> <tr> <th rowspan="4">GPT-4o</th> <td>Autonomous Eval</td> <td>84.7</td> <td>85.0</td> <td>76.0</td> <td>83.7</td> <td>75.5</td> <td>71.7</td> <td>79.4</td> </tr> <tr> <td>AgentTrek Eval</td> <td>73.0</td> <td>64.3</td> <td>63.3</td> <td>--</td> <td>--</td> <td>--</td> <td>66.9</td> </tr> <tr> <td>WebVoyager</td> <td>--</td> <td>75.3</td> <td>71.3</td> <td>74.0</td> <td>72.0</td> <td>76.7</td> <td>73.9</td> </tr> <tr> <td>WebJudge</td> <td>86.7</td> <td>86.0</td> <td>81.4</td> <td>86.3</td> <td>79.1</td> <td>81.8</td> <td><b>83.6</b></td> </tr>
<tr> <th rowspan="3">o4-mini</th> <td>Autonomous Eval</td> <td>79.7</td> <td>85.7</td> <td>86.0</td> <td>84.3</td> <td>68.0</td> <td>73.3</td> <td>79.5</td> </tr> <tr> <td>WebVoyager</td> <td>--</td> <td>80.3</td> <td>79.0</td> <td>81.7</td> <td>74.3</td> <td>78.3</td> <td>78.7</td> </tr> <tr> <td>WebJudge</td> <td>85.3</td> <td>86.3</td> <td>89.3</td> <td>87.0</td> <td>82.3</td> <td>83.7</td> <td><b>85.7</b></td> </tr>
<tr> <th></th> <td>WebJudge-7B</td> <td>86.0</td> <td>87.3</td> <td>88.3</td> <td>89.7</td> <td>84.3</td> <td>86.3</td> <td><b>87.0</b></td> </tr> </table> WebJudge powered by GPT-4o and o4-mini consistently achieves the highest agreement, with averages of 83.6% and 85.7%, respectively. Meanwhile, WebJudge-7B even outperforms o4-mini, reaching a high agreement with human judgment of 87%.
Excellent generalization capabilities on AgentRewardBench (5 OOD benchmarks)
WebJudge significantly outperforms existing methods, achieving impressive overall precision of 73.7% 75.7% and 82.0% on WebArena (WA), VisualWebArena (VWA), AssistantBench (AB), WorkArena (Work) and WorkArena++ (Wk++) across 1302 trajectories.
The high precision suggests that WebJudge holds potential as a robust and scalable reward model for downstream applications such as Rejection Sampling Fine-Tuning, Reflection, and Reinforcement Learning.
Inference
vLLM server
vllm serve osunlp/WebJudge-7B --port PORT --api-key API_KEYor
LLaMA-Factory API
API_PORT=PORT llamafactory-cli api examples/inference/qwen2_vl.yamlPrompt
Please check our Repository and Paper for more details about prompt.
text = """**Task**: {task}

**Key Points for Task Completion**: {key_points}

The snapshot of the web page is shown in the image."""

messages = [
                {"role": "system", "content": system_msg},
                {
                    "role": "user",
                    "content": [
                        {"type": "text", "text": text},
                        {
                            "type": "image_url",
                            "image_url": {"url": f"data:image/jpeg;base64,{jpg_base64_image}", "detail": "high"},
                        },
                    ],
                }
            ]
completion = client.chat.completions.create(
    model=model_path,
    messages=messages,
    temperature=0
)
Citation Information
Note: Online-Mind2Web is derived from the original Mind2Web dataset. We kindly ask that you cite both the original and this work when using or referencing the data.
@article{xue2025illusionprogressassessingcurrent,
      title={An Illusion of Progress? Assessing the Current State of Web Agents},
      author={Tianci Xue and Weijian Qi and Tianneng Shi and Chan Hee Song and Boyu Gou and Dawn Song and Huan Sun and Yu Su},
      year={2025},
      eprint={2504.01382},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2504.01382},
}

@inproceedings{deng2023mind2web,
 author = {Deng, Xiang and Gu, Yu and Zheng, Boyuan and Chen, Shijie and Stevens, Sam and Wang, Boshi and Sun, Huan and Su, Yu},
 booktitle = {Advances in Neural Information Processing Systems},
 editor = {A. Oh and T. Naumann and A. Globerson and K. Saenko and M. Hardt and S. Levine},
 pages = {28091--28114},
 publisher = {Curran Associates, Inc.},
 title = {Mind2Web: Towards a Generalist Agent for the Web},
 url = {https://proceedings.neurips.cc/paper_files/paper/2023/file/5950bf290a1570ea401bf98882128160-Paper-Datasets_and_Benchmarks.pdf},
 volume = {36},
 year = {2023}
}