
omarelshehy/Arabic-STS-Matryoshka
SentenceTransformer based on FacebookAI/xlm-roberta-large
This is an Arabic only sentence-transformers model finetuned from FacebookAI/xlm-roberta-large. It maps sentences & paragraphs to a 1024-dimensional dense vector space and can be used for semantic textual similarity, semantic search, paraphrase mining, text classification, clustering, and more.
The model is trained using the MatryoshkaLoss for embeddings of size 1024, 786, 512, 128, and 64 for storage optimization (See Evaluation).
Model Details
Model Description
- Model Type: Sentence Transformer
- Base model: FacebookAI/xlm-roberta-large <!-- at revision c23d21b0620b635a76227c604d44e43a9f0ee389 -->
- Maximum Sequence Length: 512 tokens
- Output Dimensionality: 1024 tokens
- Similarity Function: Cosine Similarity
Usage
Direct Usage (Sentence Transformers)
First install the Sentence Transformers library:
pip install -U sentence-transformersThen you can load this model and run inference.
from sentence_transformers import SentenceTransformer

# Download from the 🤗 Hub
matryoshka_dim = 786
model = SentenceTransformer("omarelshehy/Arabic-STS-Matryoshka", truncate_dim=matryoshka_dim)
# Run inference
sentences = [
    'أحب قراءة الكتب في أوقات فراغي.',
    'أستمتع بقراءة القصص في المساء قبل النوم.',
    'القراءة تعزز معرفتي وتفتح أمامي آفاق جديدة.',
]
embeddings = model.encode(sentences)
print(embeddings.shape)
# [3, 1024]

# Get the similarity scores for the embeddings
similarities = model.similarity(embeddings, embeddings)
print(similarities.shape)
# [3, 3]
Evaluation
Metrics
Semantic Similarity
- Dataset:
sts-dev - Evaluated with <code>EmbeddingSimilarityEvaluator</code>
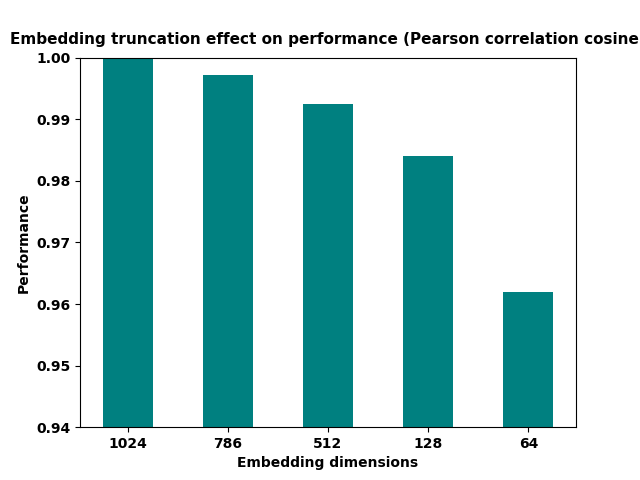
Embedding Size and Performance
This plot shows the slight degradation of performance qith smaller embedding sizes (worth investigating for your case since the benefits are huge compared to the slight loss in performance)
Citation
BibTeX
Sentence Transformers
@inproceedings{reimers-2019-sentence-bert,
    title = "Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks",
    author = "Reimers, Nils and Gurevych, Iryna",
    booktitle = "Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing",
    month = "11",
    year = "2019",
    publisher = "Association for Computational Linguistics",
    url = "https://arxiv.org/abs/1908.10084",
}
MatryoshkaLoss
@misc{kusupati2024matryoshka,
    title={Matryoshka Representation Learning},
    author={Aditya Kusupati and Gantavya Bhatt and Aniket Rege and Matthew Wallingford and Aditya Sinha and Vivek Ramanujan and William Howard-Snyder and Kaifeng Chen and Sham Kakade and Prateek Jain and Ali Farhadi},
    year={2024},
    eprint={2205.13147},
    archivePrefix={arXiv},
    primaryClass={cs.LG}
}
MultipleNegativesRankingLoss
@misc{henderson2017efficient,
    title={Efficient Natural Language Response Suggestion for Smart Reply},
    author={Matthew Henderson and Rami Al-Rfou and Brian Strope and Yun-hsuan Sung and Laszlo Lukacs and Ruiqi Guo and Sanjiv Kumar and Balint Miklos and Ray Kurzweil},
    year={2017},
    eprint={1705.00652},
    archivePrefix={arXiv},
    primaryClass={cs.CL}
}
<!--
Glossary
Clearly define terms in order to be accessible across audiences. -->
<!--
Model Card Authors
Lists the people who create the model card, providing recognition and accountability for the detailed work that goes into its construction. -->
<!--
Model Card Contact
Provides a way for people who have updates to the Model Card, suggestions, or questions, to contact the Model Card authors. -->