
mhhmm/typescript-instruct-20k-v2
26
Architecture
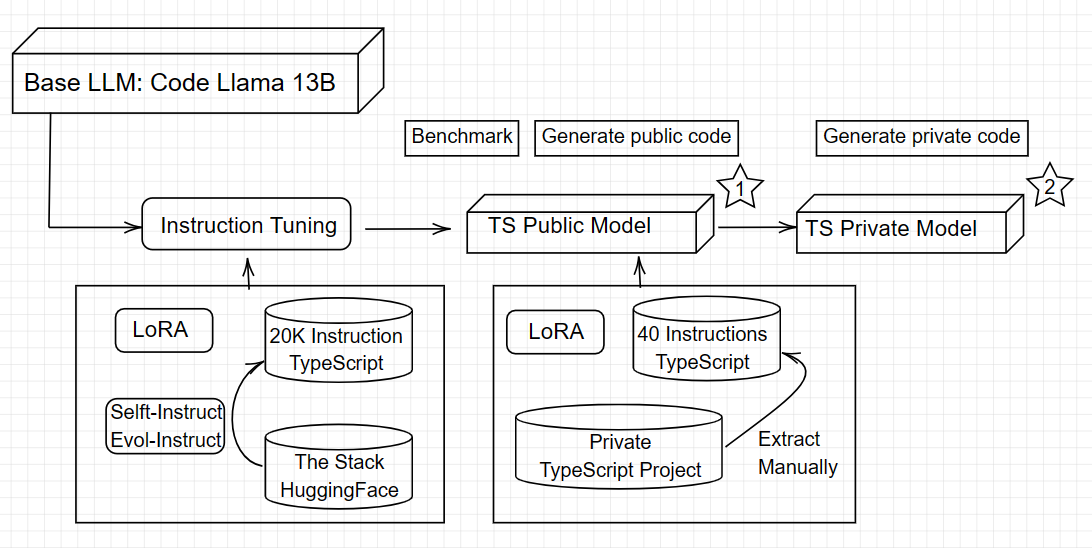
About
This model is a fine-tuned version of codellama/CodeLlama-13b-hf. It achieves the following results on the evaluation set:
- Loss: 0.4268
Training hyperparameters
The following hyperparameters were used during training:
- learning_rate: 0.0002
- trainbatchsize: 8
- evalbatchsize: 8
- seed: 42
- distributed_type: multi-GPU
- num_devices: 2
- totaltrainbatch_size: 16
- totalevalbatch_size: 16
- optimizer: Adam with betas=(0.9,0.999) and epsilon=1e-08
- lrschedulertype: cosine
- lrschedulerwarmup_steps: 10
- num_epochs: 1
Training results
Framework versions
- Transformers 4.36.0.dev0
- Pytorch 2.0.1+cu118
- Datasets 2.15.0
- Tokenizers 0.15.0
- PEFT 0.6.0
Evaluation
I'm using MultiPL-E benchmark, the same as Code Llmama using in their paper
How to reproduce my evaluation? Just run like the offical document of MultiPL-E: https://nuprl.github.io/MultiPL-E/tutorial.html, change the modal name by my model here: mhhmm/typescript-instruct-20k-v2
This is the code that I ran with Google Colab (using A100 40GB, yes, it requires that much GPU RAM)
If you even have a stronger GPU, increase the --batch-size, or --completion-limit
!pip install --upgrade pip
!pip install aiohttp numpy tqdm pytest datasets torch transformers sentencepiece
!git clone https://github.com/nuprl/MultiPL-E
%cd MultiPL-E
!mkdir typescript
!python3 automodel.py --name mhhmm/typescript-instruct-20k-v2 --root-dataset humaneval --lang ts --temperature 0.2 --batch-size 10 --completion-limit 20 --output-dir-prefix typescript
%cd evaluation/src
!python3 main.py --dir ../../typescript --output-dir ../../typescript --recursive
!python3 pass_k.py ./typescript/*