
mgoin/GLM-4.6-FP8-BLOCK
GLM-4.6-FP8-Block
Creation
Made using LLM Compressor modelfreeptq:
from llmcompressor import model_free_ptq

MODEL_ID = "zai-org/GLM-4.6"
SAVE_DIR = MODEL_ID.rstrip("/").split("/")[-1] + "-FP8-BLOCK"

# Apply FP8-Block to the model
# Once quantized, the model is saved
# using compressed-tensors to the SAVE_DIR.
model_free_ptq(
    model_stub=MODEL_ID,
    save_directory=SAVE_DIR,
    scheme="FP8_BLOCK",
    ignore=[
        "re:.*gate$",
        "lm_head",
        "model.embed_tokens",
    ],
    max_workers=15,
    device="cuda:0",
)
Eval
GSM8k running with vLLM TP=4 on GB300
vllm serve GLM-4.6-FP8-BLOCK -tp=4

python tests/evals/gsm8k/gsm8k_eval.py
Running GSM8K evaluation: 1319 questions, 5-shot
Evaluating: 100%|█████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 1319/1319 [00:52<00:00, 25.15it/s]

Results:
Accuracy: 0.929
Invalid responses: 0.001
Total latency: 52.449 s
Questions per second: 25.148
Total output tokens: 131828
Output tokens per second: 2513.428
GLM-4.6
<div align="center"> <img src=https://raw.githubusercontent.com/zai-org/GLM-4.5/refs/heads/main/resources/logo.svg width="15%"/> </div> <p align="center"> 👋 Join our <a href="https://discord.gg/QR7SARHRxK" target="blank">Discord</a> community. <br> 📖 Check out the GLM-4.6 <a href="https://z.ai/blog/glm-4.6" target="blank">technical blog</a>, <a href="https://arxiv.org/abs/2508.06471" target="blank">technical report(GLM-4.5)</a>, and <a href="https://zhipu-ai.feishu.cn/wiki/Gv3swM0Yci7w7Zke9E0crhU7n7D" target="blank">Zhipu AI technical documentation</a>. <br> 📍 Use GLM-4.6 API services on <a href="https://docs.z.ai/guides/llm/glm-4.6">Z.ai API Platform. </a> <br> 👉 One click to <a href="https://chat.z.ai">GLM-4.6</a>. </p>
Model Introduction
Compared with GLM-4.5, GLM-4.6 brings several key improvements:
- Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks.
- Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages.
- Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability.
- More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks.
- Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
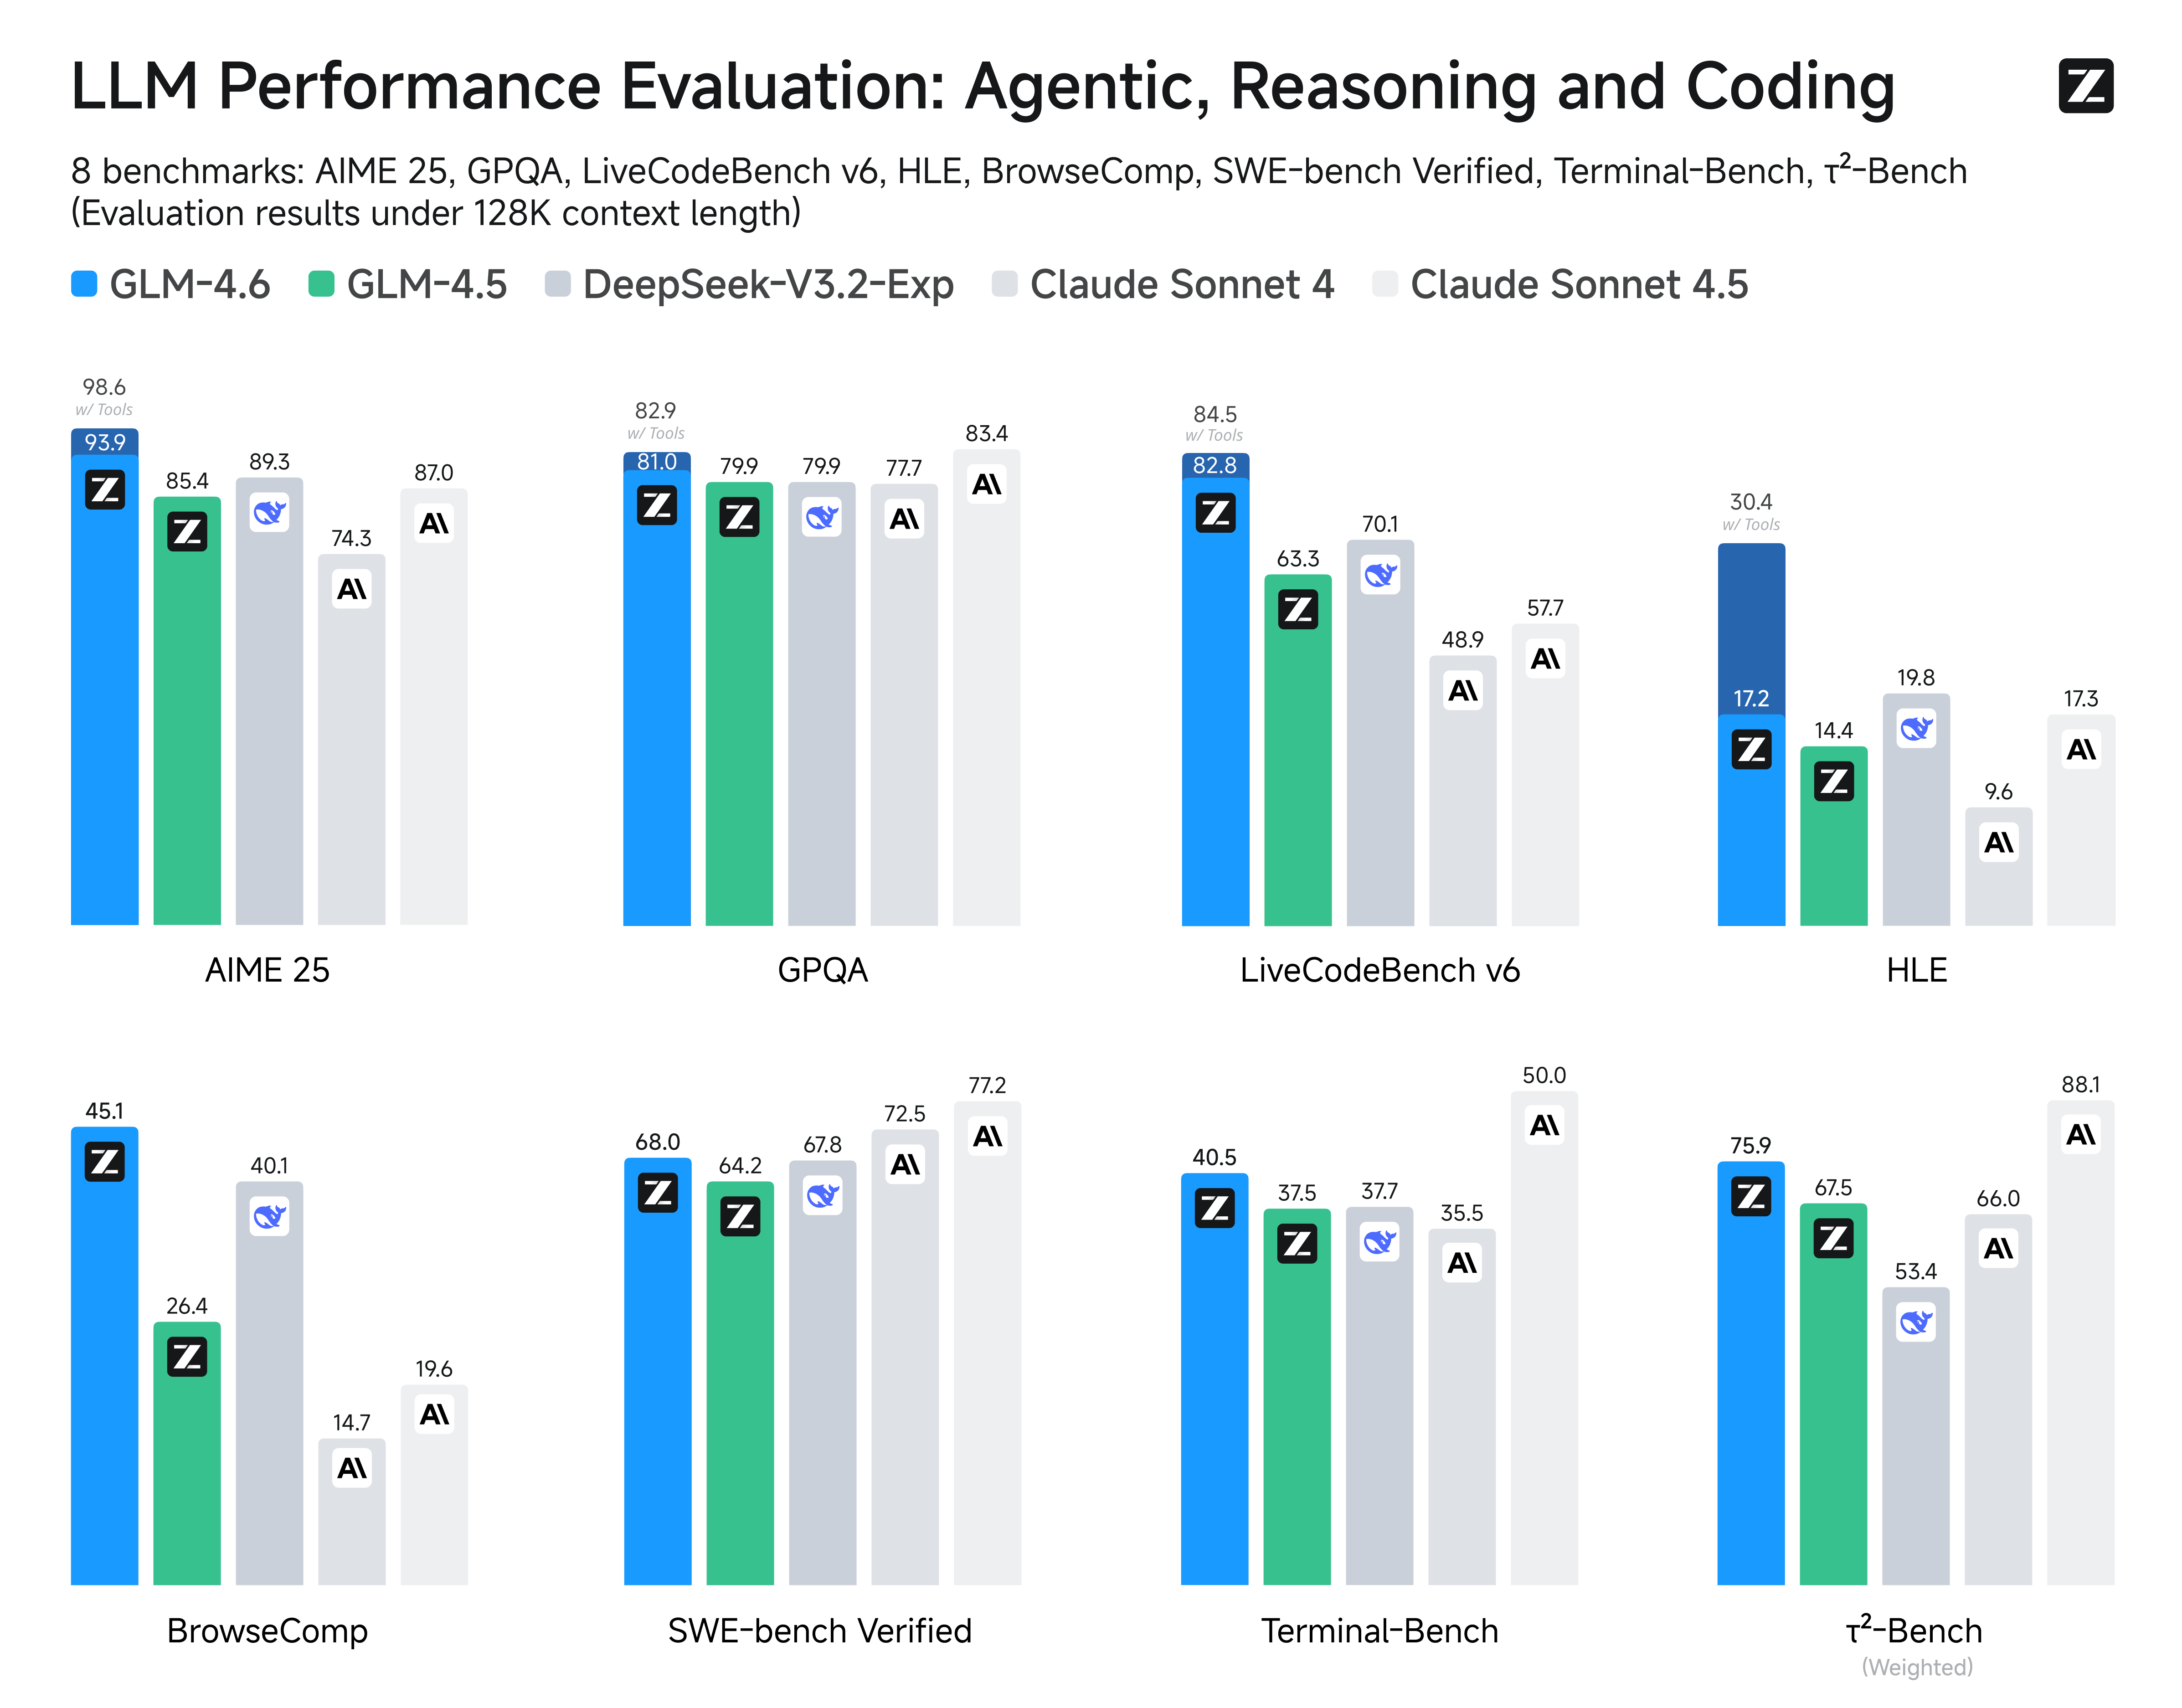
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as DeepSeek-V3.1-Terminus and Claude Sonnet 4.
Inference
Both GLM-4.5 and GLM-4.6 use the same inference method.
you can check our github for more detail.
Recommended Evaluation Parameters
For general evaluations, we recommend using a sampling temperature of 1.0.
For code-related evaluation tasks (such as LCB), it is further recommended to set:
top_p = 0.95top_k = 40