
kushalc1/sarashina-embedding-v2-1b-jsts-matryoshka
SentenceTransformer based on sbintuitions/sarashina-embedding-v2-1b
This is a sentence-transformers model finetuned from sbintuitions/sarashina-embedding-v2-1b on the jsts dataset. It maps sentences & paragraphs to a 1792-dimensional dense vector space and can be used for semantic textual similarity, semantic search, paraphrase mining, text classification, clustering, and more.
Model Details
Model Description
- Model Type: Sentence Transformer
- Base model: sbintuitions/sarashina-embedding-v2-1b <!-- at revision 1f3408afaa7b617e3445d891310a9c26dd0c68a5 -->
- Maximum Sequence Length: 8192 tokens
- Output Dimensionality: 1792 dimensions
- Similarity Function: Cosine Similarity
- Training Dataset:
- jsts
- Language: jpn <!-- - License: Unknown -->
Model Sources
- Documentation: Sentence Transformers Documentation
- Repository: Sentence Transformers on GitHub
- Hugging Face: Sentence Transformers on Hugging Face
Full Model Architecture
SentenceTransformer(
  (0): Transformer({'max_seq_length': 8192, 'do_lower_case': False, 'architecture': 'LlamaModel'})
  (1): Pooling({'word_embedding_dimension': 1792, 'pooling_mode_cls_token': False, 'pooling_mode_mean_tokens': False, 'pooling_mode_max_tokens': False, 'pooling_mode_mean_sqrt_len_tokens': False, 'pooling_mode_weightedmean_tokens': False, 'pooling_mode_lasttoken': True, 'include_prompt': False})
)
Usage
Direct Usage (Sentence Transformers)
First install the Sentence Transformers library:
pip install -U sentence-transformersThen you can load this model and run inference.
from sentence_transformers import SentenceTransformer

# Download from the 🤗 Hub
model = SentenceTransformer("kushalc1/sarashina-embedding-v2-1b-jsts-matryoshka")
# Run inference
sentences = [
    '樹木に囲まれた芝生の上に三頭のキリンが立っています。',
    '芝生の上に数頭のキリンが歩いています。',
    '茶色のテーブルの上にピザと飲み物が置かれています。',
]
embeddings = model.encode(sentences)
print(embeddings.shape)
# [3, 1792]

# Get the similarity scores for the embeddings
similarities = model.similarity(embeddings, embeddings)
print(similarities)
# tensor([[1.0000, 0.9453, 0.4754],
#         [0.9453, 1.0000, 0.5004],
#         [0.4754, 0.5004, 1.0000]])
<!--
Direct Usage (Transformers)
<details><summary>Click to see the direct usage in Transformers</summary>
</details> -->
<!--
Downstream Usage (Sentence Transformers)
You can finetune this model on your own dataset.
<details><summary>Click to expand</summary>
</details> -->
<!--
Out-of-Scope Use
List how the model may foreseeably be misused and address what users ought not to do with the model. -->
Evaluation
Metrics
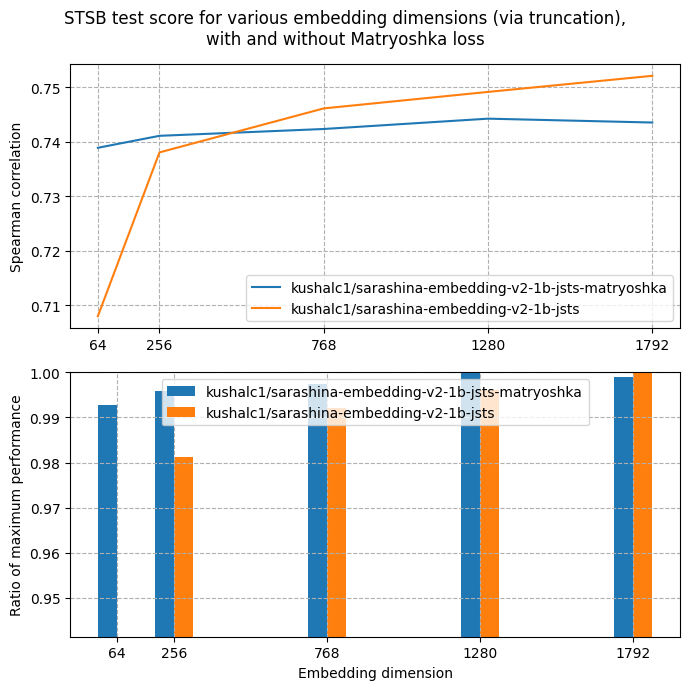
Semantic Similarity
- Datasets:
sts-dev-1792,sts-test-1792andsts-test-1792 - Evaluated with <code>EmbeddingSimilarityEvaluator</code> with these parameters:
  {
      "truncate_dim": 1792
}Semantic Similarity
- Datasets:
sts-dev-1280,sts-test-1280andsts-test-1280 - Evaluated with <code>EmbeddingSimilarityEvaluator</code> with these parameters:
  {
      "truncate_dim": 1280
}Semantic Similarity
- Datasets:
sts-dev-768,sts-test-768andsts-test-768 - Evaluated with <code>EmbeddingSimilarityEvaluator</code> with these parameters:
  {
      "truncate_dim": 768
}Semantic Similarity
- Datasets:
sts-dev-256,sts-test-256andsts-test-256 - Evaluated with <code>EmbeddingSimilarityEvaluator</code> with these parameters:
  {
      "truncate_dim": 256
}Semantic Similarity
- Datasets:
sts-dev-64,sts-test-64andsts-test-64 - Evaluated with <code>EmbeddingSimilarityEvaluator</code> with these parameters:
  {
      "truncate_dim": 64
}<!--
Bias, Risks and Limitations
What are the known or foreseeable issues stemming from this model? You could also flag here known failure cases or weaknesses of the model. -->
<!--
Recommendations
What are recommendations with respect to the foreseeable issues? For example, filtering explicit content. -->
Training Details
Training Dataset
jsts
- Dataset: jsts at b3d3097
- Size: 12,451 training samples
- Columns: <code>sentence1</code>, <code>sentence2</code>, and <code>score</code>
- Approximate statistics based on the first 1000 samples: | | sentence1 | sentence2 | score | |:--------|:----------------------------------------------------------------------------------|:----------------------------------------------------------------------------------|:---------------------------------------------------------------| | type | string | string | float | | details | <ul><li>min: 5 tokens</li><li>mean: 10.64 tokens</li><li>max: 35 tokens</li></ul> | <ul><li>min: 3 tokens</li><li>mean: 10.53 tokens</li><li>max: 30 tokens</li></ul> | <ul><li>min: 0.0</li><li>mean: 2.32</li><li>max: 5.0</li></ul> |
- Samples: | sentence1 | sentence2 | score | |:------------------------------------|:-----------------------------------|:-------------------------------| | <code>川べりでサーフボードを持った人たちがいます。</code> | <code>トイレの壁に黒いタオルがかけられています。</code> | <code>0.0</code> | | <code>二人の男性がジャンボジェット機を見ています。</code> | <code>2人の男性が、白い飛行機を眺めています。</code> | <code>3.799999952316284</code> | | <code>男性が子供を抱き上げて立っています。</code> | <code>坊主頭の男性が子供を抱いて立っています。</code> | <code>4.0</code> |
- Loss: <code>MatryoshkaLoss</code> with these parameters:
  {
      "loss": "MultipleNegativesRankingLoss",
      "matryoshka_dims": [
          1792,
          1280,
          768,
          256,
          64
      ],
      "matryoshka_weights": [
          1,
          1,
          1,
          1,
          1
      ],
      "n_dims_per_step": -1
  }
Evaluation Dataset
jsts
- Dataset: jsts at b3d3097
- Size: 1,457 evaluation samples
- Columns: <code>sentence1</code>, <code>sentence2</code>, and <code>score</code>
- Approximate statistics based on the first 1000 samples: | | sentence1 | sentence2 | score | |:--------|:----------------------------------------------------------------------------------|:----------------------------------------------------------------------------------|:---------------------------------------------------------------| | type | string | string | float | | details | <ul><li>min: 5 tokens</li><li>mean: 10.78 tokens</li><li>max: 34 tokens</li></ul> | <ul><li>min: 3 tokens</li><li>mean: 10.63 tokens</li><li>max: 37 tokens</li></ul> | <ul><li>min: 0.0</li><li>mean: 2.22</li><li>max: 5.0</li></ul> |
- Samples: | sentence1 | sentence2 | score | |:-----------------------------------------|:------------------------------------|:--------------------------------| | <code>レンガの建物の前を、乳母車を押した女性が歩いています。</code> | <code>厩舎で馬と女性とが寄り添っています。</code> | <code>0.0</code> | | <code>山の上に顔の白い牛が2頭います。</code> | <code>曇り空の山肌で、牛が2匹草を食んでいます。</code> | <code>2.4000000953674316</code> | | <code>バナナを持った人が道路を通行しています。</code> | <code>道の上をバナナを背負った男性が歩いています。</code> | <code>3.5999999046325684</code> |
- Loss: <code>MatryoshkaLoss</code> with these parameters:
  {
      "loss": "MultipleNegativesRankingLoss",
      "matryoshka_dims": [
          1792,
          1280,
          768,
          256,
          64
      ],
      "matryoshka_weights": [
          1,
          1,
          1,
          1,
          1
      ],
      "n_dims_per_step": -1
  }
Training Hyperparameters
Non-Default Hyperparameters
eval_strategy: stepsper_device_train_batch_size: 16per_device_eval_batch_size: 16num_train_epochs: 4warmup_ratio: 0.1fp16: True
All Hyperparameters
<details><summary>Click to expand</summary>
overwrite_output_dir: Falsedo_predict: Falseeval_strategy: stepsprediction_loss_only: Trueper_device_train_batch_size: 16per_device_eval_batch_size: 16per_gpu_train_batch_size: Noneper_gpu_eval_batch_size: Nonegradient_accumulation_steps: 1eval_accumulation_steps: Nonetorch_empty_cache_steps: Nonelearning_rate: 5e-05weight_decay: 0.0adam_beta1: 0.9adam_beta2: 0.999adam_epsilon: 1e-08max_grad_norm: 1.0num_train_epochs: 4max_steps: -1lr_scheduler_type: linearlr_scheduler_kwargs: {}warmup_ratio: 0.1warmup_steps: 0log_level: passivelog_level_replica: warninglog_on_each_node: Truelogging_nan_inf_filter: Truesave_safetensors: Truesave_on_each_node: Falsesave_only_model: Falserestore_callback_states_from_checkpoint: Falseno_cuda: Falseuse_cpu: Falseuse_mps_device: Falseseed: 42data_seed: Nonejit_mode_eval: Falseuse_ipex: Falsebf16: Falsefp16: Truefp16_opt_level: O1half_precision_backend: autobf16_full_eval: Falsefp16_full_eval: Falsetf32: Nonelocal_rank: 0ddp_backend: Nonetpu_num_cores: Nonetpu_metrics_debug: Falsedebug: []dataloader_drop_last: Falsedataloader_num_workers: 0dataloader_prefetch_factor: Nonepast_index: -1disable_tqdm: Falseremove_unused_columns: Truelabel_names: Noneload_best_model_at_end: Falseignore_data_skip: Falsefsdp: []fsdp_min_num_params: 0fsdp_config: {'minnumparams': 0, 'xla': False, 'xlafsdpv2': False, 'xlafsdpgrad_ckpt': False}fsdp_transformer_layer_cls_to_wrap: Noneaccelerator_config: {'splitbatches': False, 'dispatchbatches': None, 'evenbatches': True, 'useseedablesampler': True, 'nonblocking': False, 'gradientaccumulationkwargs': None}parallelism_config: Nonedeepspeed: Nonelabel_smoothing_factor: 0.0optim: adamwtorchfusedoptim_args: Noneadafactor: Falsegroup_by_length: Falselength_column_name: lengthddp_find_unused_parameters: Noneddp_bucket_cap_mb: Noneddp_broadcast_buffers: Falsedataloader_pin_memory: Truedataloader_persistent_workers: Falseskip_memory_metrics: Trueuse_legacy_prediction_loop: Falsepush_to_hub: Falseresume_from_checkpoint: Nonehub_model_id: Nonehub_strategy: every_savehub_private_repo: Nonehub_always_push: Falsehub_revision: Nonegradient_checkpointing: Falsegradient_checkpointing_kwargs: Noneinclude_inputs_for_metrics: Falseinclude_for_metrics: []eval_do_concat_batches: Truefp16_backend: autopush_to_hub_model_id: Nonepush_to_hub_organization: Nonemp_parameters:auto_find_batch_size: Falsefull_determinism: Falsetorchdynamo: Noneray_scope: lastddp_timeout: 1800torch_compile: Falsetorch_compile_backend: Nonetorch_compile_mode: Noneinclude_tokens_per_second: Falseinclude_num_input_tokens_seen: Falseneftune_noise_alpha: Noneoptim_target_modules: Nonebatch_eval_metrics: Falseeval_on_start: Falseuse_liger_kernel: Falseliger_kernel_config: Noneeval_use_gather_object: Falseaverage_tokens_across_devices: Falseprompts: Nonebatch_sampler: batch_samplermulti_dataset_batch_sampler: proportionalrouter_mapping: {}learning_rate_mapping: {}
</details>
Training Logs
Framework Versions
- Python: 3.12.6
- Sentence Transformers: 5.2.0
- Transformers: 4.56.0
- PyTorch: 2.8.0+cu129
- Accelerate: 1.10.1
- Datasets: 4.4.2
- Tokenizers: 0.22.0
Citation
BibTeX
Sentence Transformers
@inproceedings{reimers-2019-sentence-bert,
    title = "Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks",
    author = "Reimers, Nils and Gurevych, Iryna",
    booktitle = "Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing",
    month = "11",
    year = "2019",
    publisher = "Association for Computational Linguistics",
    url = "https://arxiv.org/abs/1908.10084",
}
MatryoshkaLoss
@misc{kusupati2024matryoshka,
    title={Matryoshka Representation Learning},
    author={Aditya Kusupati and Gantavya Bhatt and Aniket Rege and Matthew Wallingford and Aditya Sinha and Vivek Ramanujan and William Howard-Snyder and Kaifeng Chen and Sham Kakade and Prateek Jain and Ali Farhadi},
    year={2024},
    eprint={2205.13147},
    archivePrefix={arXiv},
    primaryClass={cs.LG}
}
MultipleNegativesRankingLoss
@misc{henderson2017efficient,
    title={Efficient Natural Language Response Suggestion for Smart Reply},
    author={Matthew Henderson and Rami Al-Rfou and Brian Strope and Yun-hsuan Sung and Laszlo Lukacs and Ruiqi Guo and Sanjiv Kumar and Balint Miklos and Ray Kurzweil},
    year={2017},
    eprint={1705.00652},
    archivePrefix={arXiv},
    primaryClass={cs.CL}
}
<!--
Glossary
Clearly define terms in order to be accessible across audiences. -->
<!--
Model Card Authors
Lists the people who create the model card, providing recognition and accountability for the detailed work that goes into its construction. -->
<!--
Model Card Contact
Provides a way for people who have updates to the Model Card, suggestions, or questions, to contact the Model Card authors. -->