
kamaludeen/multilingual_go_emotions-ONNX
multilingualgoemotions (ONNX)
This is an ONNX version of AnasAlokla/multilingual_go_emotions. It was automatically converted and uploaded using this Hugging Face Space.
Usage with Transformers.js
See the pipeline documentation for text-classification: https://huggingface.co/docs/transformers.js/api/pipelines#module_pipelines.TextClassificationPipeline
🌍 Multilingual GoEmotions Classifier 💬
   
Table of Contents
- 📖 Overview
- ✨ Key Features
- 💫 Supported Emotions
- 🔗 Links
- ⚙️ Installation
- 🚀 Quickstart: Emotion Detection
- 📊 Evaluation
- 💡 Use Cases
- 📚 Trained On
- 🔧 Fine-Tuning Guide
- 🏷️ Tags
- 💬 Support & Contact
Overview
This repository contains a powerful multilingual, multi-label emotion classification model. It is fine-tuned from the robust bert-base-multilingual-cased model on the comprehensive multilingual_go_emotions dataset. The model is designed to analyze text and identify a wide spectrum of 27 different emotions, plus a neutral category. Its ability to detect multiple emotions simultaneously makes it highly effective for understanding nuanced text from diverse sources.
- Model Name: AnasAlokla/multilingualgoemotions
- Architecture: BERT (bert-base-multilingual-cased)
- Task: Multi-Label Text Classification
- Languages: Arabic, English, French, Spanish, Dutch, Turkish
Key Features
- 🌍 Truly Multilingual: Natively supports 6 major languages, making it ideal for global applications.
- 🏷️ Multi-Label Classification: Capable of detecting multiple emotions in a single piece of text, capturing complex emotional expressions.
- 💪 High Performance: Built on
bert-base-multilingual-cased, delivering strong results across all supported languages and emotions. See the detailed evaluation metrics. - 🔗 Open & Accessible: Comes with a live demo, the full dataset, and the complete training code for full transparency and reproducibility.
- V1.1 Improved Version: An updated model is available that specifically improves performance on low-frequency emotion samples.
Supported Emotions
The model is trained to classify text into 27 distinct emotion categories as well as a neutral class:
Links
- Live Demo: **Hugging Face Space**
- Dataset (Supports 6 Languages): **multilingual_go_emotions**
- Model Used: **AnasAlokla/multilingual_go_emotions**
- GitHub Code: **emotion_chatbot**
- Improved Version (V1.1): **multilingual_go_emotions_V1.1**
- Improved Version (V1.2): **multilingual_go_emotions_V1.2**
Installation
Install the required libraries using pip:
pip install transformers torchQuickstart: Emotion Detection
You can easily use this model for multi-label emotion classification with the transformers pipeline. Set top_k=None to see all predicted emotions above the model's default threshold.
from transformers import pipeline

# Load the multilingual, multi-label emotion classification pipeline
emotion_classifier = pipeline(
    "text-classification",
    model="AnasAlokla/multilingual_go_emotions",
    top_k=None # To return all scores for each label
)

# --- Example 1: English ---
text_en = "I'm so happy for you, but I'm also a little bit sad to see you go."
results_en = emotion_classifier(text_en)
print(f"Text (EN): {text_en}")
print(f"Predictions: {results_en}\n")

# --- Example 2: Spanish ---
text_es = "¡Qué sorpresa! No me lo esperaba para nada."
results_es = emotion_classifier(text_es)
print(f"Text (ES): {text_es}")
print(f"Predictions: {results_es}\n")

# --- Example 3: Arabic ---
text_ar = "أشعر بخيبة أمل وغضب بسبب ما حدث"
results_ar = emotion_classifier(text_ar)
print(f"Text (AR): {text_ar}")
print(f"Predictions: {results_ar}")
Expected Output (structure):
Text (EN): I'm so happy for you, but I'm also a little bit sad to see you go. Predictions: [[{'label': 'joy', 'score': 0.9...}, {'label': 'sadness', 'score': 0.8...}, {'label': 'caring', 'score': 0.5...}, ...]]
Text (ES): ¡Qué sorpresa! No me lo esperaba para nada. Predictions: [[{'label': 'surprise', 'score': 0.9...}, {'label': 'excitement', 'score': 0.4...}, ...]]
Text (AR): أشعر بخيبة أمل وغضب بسبب ما حدث Predictions: [[{'label': 'disappointment', 'score': 0.9...}, {'label': 'anger', 'score': 0.9...}, ...]]
Evaluation
The model's performance was rigorously evaluated on the test set.
Test Set Performance
The following table shows the performance metrics of the fine-tuned model on the test set, broken down by emotion category.
Use Cases
This model is ideal for applications requiring nuanced emotional understanding across different languages:
Global Customer Feedback Analysis: Analyze customer reviews, support tickets, and survey responses from around the world to gauge sentiment.
Multilingual Social Media Monitoring: Track brand perception and public mood across different regions and languages.
Advanced Chatbot Development: Build more empathetic and responsive chatbots that can understand user emotions in their native language.
Content Moderation: Automatically flag toxic, aggressive, or sensitive content on international platforms.
Market Research: Gain insights into how different cultures express emotions in text.
Trained On
Base Model: **google-bert/bert-base-multilingual-cased** - A powerful pretrained model supporting 104 languages.
Dataset: **multilingual_go_emotions** - A carefully translated and curated dataset for multilingual emotion analysis, based on the original Google GoEmotions dataset.
Fine-Tuning Guide
To adapt this model for your own dataset or to replicate the training process, you can follow the methodology outlined in the official code repository. The repository provides a complete, end-to-end example, including data preprocessing, training scripts, and evaluation logic.
For full details, please refer to the GitHub repository: **emotion_chatbot**
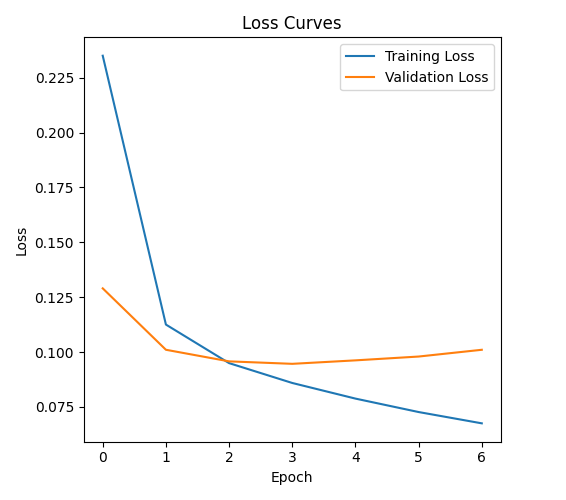
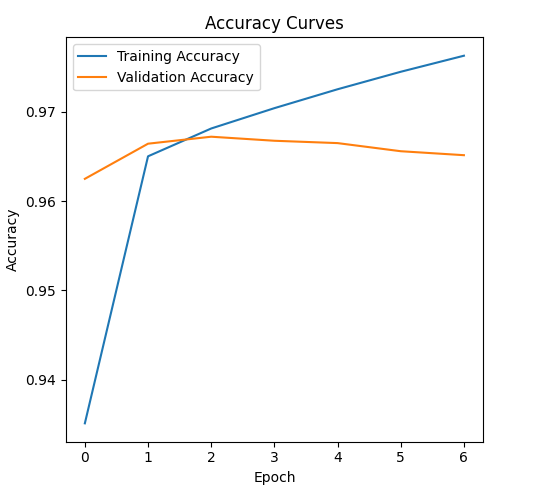
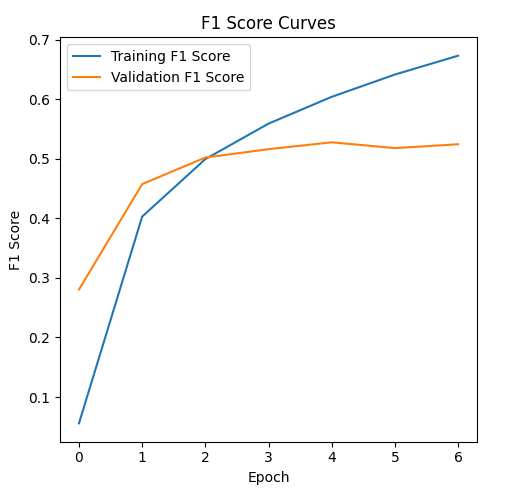
The following plots visualize the model's performance during the fine-tuning process across epochs.
Loss Curves (Training vs. Validation)
Accuracy Curves (Training vs. Validation)
F1 Score Curves (Training vs. Validation)
Tags
#multilingual-nlp #emotion-classification #text-classification #multi-label #bert #transformer #natural-language-processing #sentiment-analysis #deep-learning #arabic-nlp #french-nlp #spanish-nlp #goemotions #BERT-Emotion #edge-nlp #emotion-detection #offline-nlp #sentiment-analysis #emojis #emotions #embedded-nlp #ai-for-iot #efficient-bert #nlp2025 #context-aware #edge-ml #smart-home-ai #emotion-aware #voice-ai #eco-ai #chatbot #social-media #mental-health #short-text #smart-replies #tone-analysis
Support & Contact
For questions, bug reports, or collaboration inquiries, please open an issue on the Hugging Face Hub repository or contact the author directly.
Author: Anas Hamid Alokla
📬 Email: anasaloklahaaa@gmail.com