
eulogik/polywhisper


🎙️ PolyWhisper v9 — Efficient Multilingual Indic ASR
by Eulogik — Frontier Edge AI · Vernacular Intelligence · eulogik.com
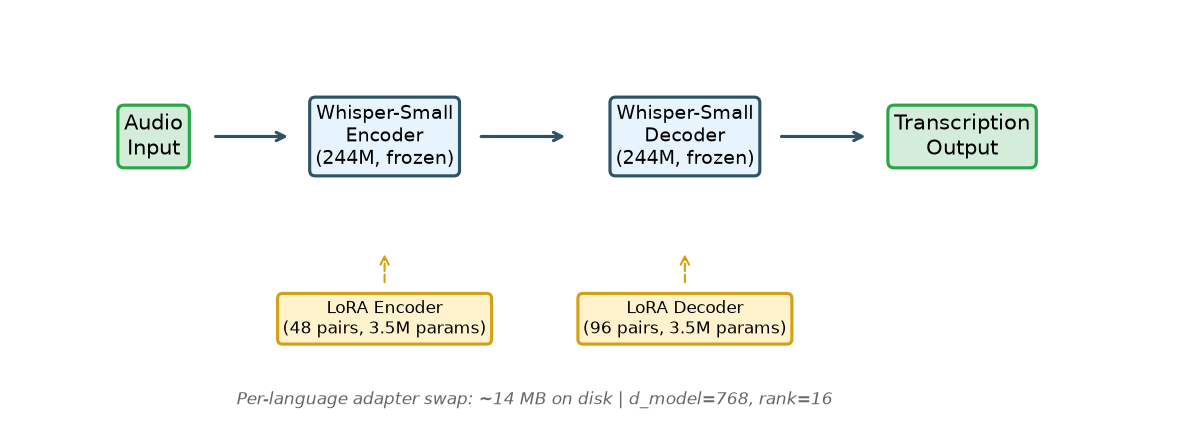
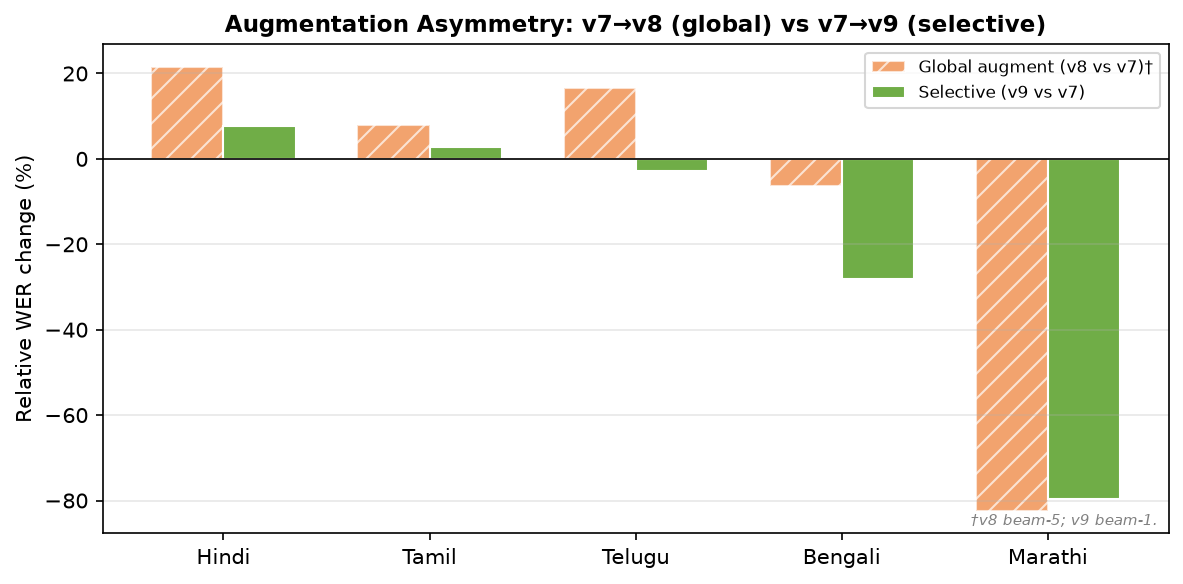
TL;DR: PolyWhisper v9 is a research-ready automatic speech recognition (ASR) system for Hindi, Tamil, Telugu, Bengali, and Marathi. It pairs a frozen OpenAI Whisper-Small backbone (244M params) with tiny per-language LoRA adapters (~14MB each). Bengali WER drops −28.2% and Marathi −79.6% versus the no-augmentation baseline — at roughly 1% of the storage cost of full fine-tuning.
✨ Why PolyWhisper?
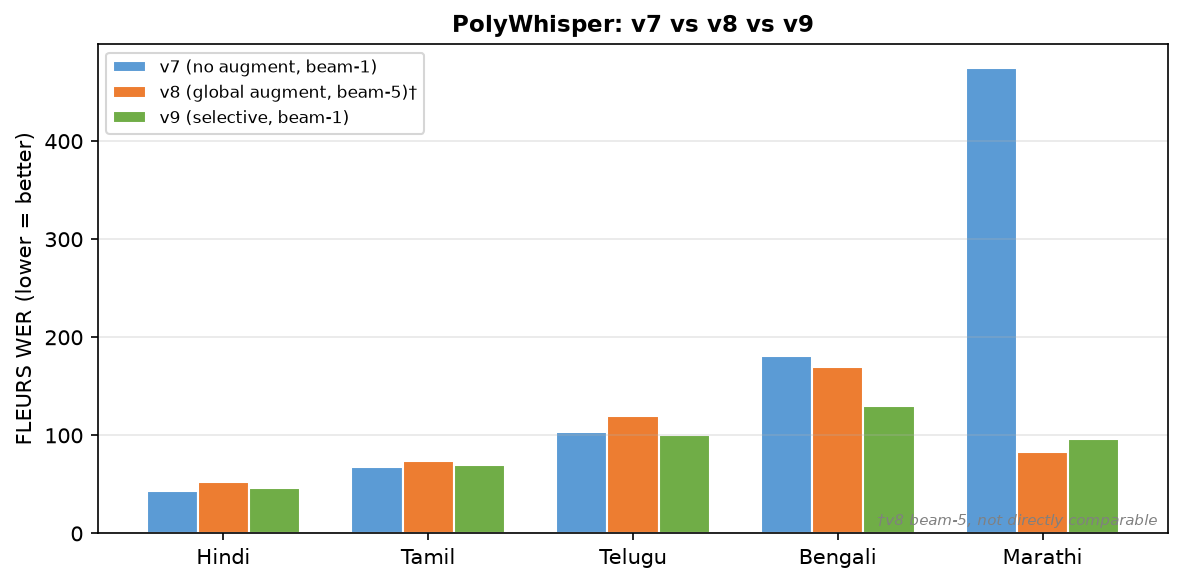
WER = word error rate (lower is better). FLEURS test set, beam=1, punctuation-normalized scoring.
📊 Benchmarks (FLEURS, beam=1, normalized WER)
🧪 The v9 finding: augment per language, not globally
Training with SpecAugment + speed perturbation on all languages damaged Hindi/Tamil (token-loop degeneration) while massively helping Bengali/Marathi. The v9 recipe augments only `bn`/`mr` and trains hi/ta/te clean:
🎯 Decoding: per-language beam widths (measured, full FLEURS test)
Beam-5 + repetition penalty 1.3 helps every language except Telugu, where beam search collapses into repeated-token loops (0/472 perfect samples, 326/472 over 100% WER). The library/CLI defaults encode this (num_beams=None → per-language optimal):
📦 Which adapter should I use?
All adapters are rank-16 LoRA (decoder + encoder attention), ~14MB each. Backbone weights are not included — they load from openai/whisper-small at runtime. The _prod suffix is the v9 production-run tag, not an augmentation marker: Telugu was trained clean in the selective v9 recipe.
🚀 Quickstart
pip install -e .# Hindi speech to text
polywhisper transcribe audio.wav --lang hi
# Tamil with JSON output
polywhisper transcribe audio.wav --lang ta --format json
# Auto-detect language, SRT subtitles
polywhisper transcribe audio.wav --format srt > subs.srt
# Batch a folder
polywhisper batch ./audio_folder/ --lang bn --output results.jsonfrom polywhisper import transcribe
result = transcribe("audio.wav", lang="mr")
print(result.text)
print(result.segments) # timestamped segments🖥️ CPU-only inference (ONNX Runtime)
Export INT8-quantized ONNX graphs (no PyTorch, no GPU needed at inference):
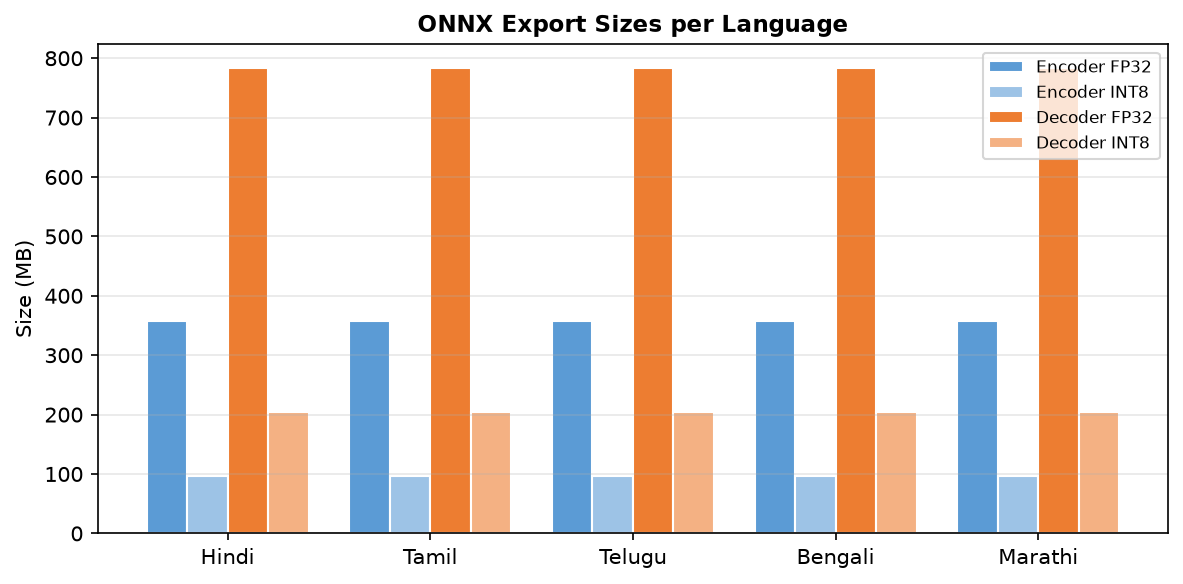
polywhisper export --lang hi --variant prod --int8Pre-exported v9 graphs live under export/onnx/ on the Hub — per language, fp32 + INT8:
Files are named {lang}_{lang}_best_prod_{encoder,decoder}{,_int8}.onnx. INT8 is ~4× smaller.
Verification: fp32 ONNX vs PyTorch max diff < 1e-3 on all five languages (encoder + decoder). End-to-end greedy spot-checks (FLEURS audio, beam=1):
Spot-checks are tiny (5–10 utterances) so single-sentence flips move the numbers; fp32 ONNX is at parity with torch. INT8 trades a few points for 4× smaller files.
🏋️ Training recipe (reproducible)
- Data: IndicVoices-ST (~19–20k clips/language) · Eval: FLEURS
- Backbone:
openai/whisper-small, frozen · Adapters: LoRA rank-16, encoder + decoder attention - Schedule: 3–5 epochs/language, batch 4, AdamW, cosine LR (peak 1e-4), 2× NVIDIA T4
- Augmentation (v9): SpecAugment + speed perturb for
bn/mronly;hi/ta/teclean - Selection: WER-gated checkpoints (
*_best_*.pt) on FLEURS dev slices - Code: `train_v3.py` · orchestrator `kaggle_train_resumable.py` · scoring `normalize_ortho.py`
❓ FAQ
What is PolyWhisper? PolyWhisper is an open-source Indic ASR toolkit: one frozen Whisper-Small backbone plus five small per-language LoRA adapters covering Hindi, Tamil, Telugu, Bengali, and Marathi.
How is it different from fine-tuning Whisper? Full fine-tuning rewrites ~244M–1.5B weights per language. PolyWhisper freezes the backbone and trains ~3.5M LoRA parameters per language (~14MB), so five languages ship for the storage cost of a rounding error.
Which languages are usable? All five ship working adapters. Hindi (46.3 WER) and Tamil (70.1) are strongest; Telugu, Bengali, and Marathi remain high-WER research adapters, useful for assistive/search/subtitle-draft workflows rather than verbatim transcription.
Can I run it on CPU? Yes — export to ONNX INT8 and run with ONNX Runtime, no GPU required.
Can I run it on a Mac? Yes — PyTorch MPS is supported (Device: mps), plus CPU via ONNX.
What data was it trained/evaluated on? Trained on IndicVoices-ST conversational speech, evaluated on FLEURS read speech with punctuation-normalized, script-aware scoring.
⚠️ Limitations
- Absolute WER on Telugu/Bengali/Marathi is still high — usable for assistive/search/subtitle-draft workflows, not verbatim legal/medical transcription.
- Evaluated on read speech (FLEURS); spontaneous conversational accuracy will differ.
- Beam=1 numbers in the benchmark table above (paper parity); shipped defaults use beam-5 + repetition penalty 1.3 except Telugu (beam-1), see decoding table.
📄 License & citation
MIT. Whisper weights © OpenAI. Training data: IndicVoices-ST (CC-BY) · Eval: FLEURS (CC-BY).
@misc{polywhisper2026,
  title  = {PolyWhisper: Efficient Multilingual Indic ASR via Frozen Backbone and Per-Language LoRA Adapters},
  author = {Kishore, Gautam},
  year   = {2026},
  publisher = {HuggingFace},
  url    = {https://huggingface.co/eulogik/polywhisper}
}
🔗 Links
- 🌍 Eulogik: eulogik.com
- 🤗 Model: huggingface.co/eulogik/polywhisper
- 💻 Code: github.com/eulogik/PolyWhisper
- 🗣️ Train data: ai4bharat/indicvoices-st
- 🧪 Eval data: google/fleurs