
cmarkea/detr-layout-detection
DETR-layout-detection
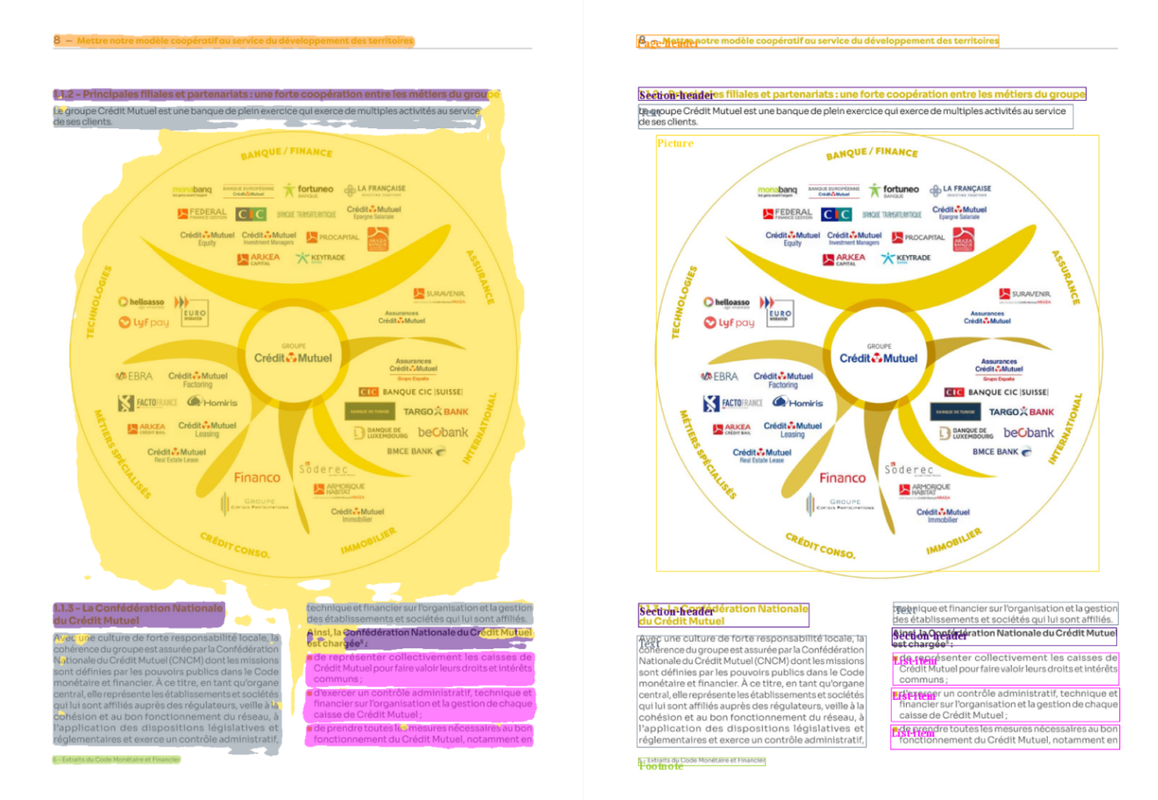
We present the model cmarkea/detr-layout-detection, which allows extracting different layouts (Text, Picture, Caption, Footnote, etc.) from an image of a document. This is a fine-tuning of the model detr-resnet-50 on the DocLayNet dataset. This model can jointly predict masks and bounding boxes for documentary objects. It is ideal for processing documentary corpora to be ingested into an ODQA system.
This model allows extracting 11 entities, which are: Caption, Footnote, Formula, List-item, Page-footer, Page-header, Picture, Section-header, Table, Text, and Title.
Performance
In this section, we will assess the model's performance by separately considering semantic segmentation and object detection. In both cases, no post-processing was applied after estimation.
For semantic segmentation, we will use the F1-score to evaluate the classification of each pixel. For object detection, we will assess performance based on the Generalized Intersection over Union (GIoU) and the accuracy of the predicted bounding box class. The evaluation is conducted on 500 pages from the PDF evaluation dataset of DocLayNet.
Benchmark
Now, let's compare the performance of this model with other models.
Direct Use
from transformers import AutoImageProcessor
from transformers.models.detr import DetrForSegmentation

img_proc = AutoImageProcessor.from_pretrained(
    "cmarkea/detr-layout-detection"
)
model = DetrForSegmentation.from_pretrained(
    "cmarkea/detr-layout-detection"
)

img: PIL.Image

with torch.inference_mode():
    input_ids = img_proc(img, return_tensors='pt')
    output = model(**input_ids)

threshold=0.4

segmentation_mask = img_proc.post_process_segmentation(
    output,
    threshold=threshold,
    target_sizes=[img.size[::-1]]
)

bbox_pred = img_proc.post_process_object_detection(
    output,
    threshold=threshold,
    target_sizes=[img.size[::-1]]
)
Example
Citation
@online{DeDetrLay,
  AUTHOR = {Cyrile Delestre},
  URL = {https://huggingface.co/cmarkea/detr-layout-detection},
  YEAR = {2024},
  KEYWORDS = {Image Processing ; Transformers ; Layout},
}