
calcuis/qwen-image-gguf
232.1k
gguf quantized version of qwen-image
- run it straight with
gguf-connector
ggc q5GGUF file(s) available. Select which one to use: 1. qwen-image-iq2s.gguf 2. qwen-image-iq4nl.gguf 3. qwen-image-q40.gguf 4. qwen-image-q80.gguf Enter your choice (1 to 4): _
run it with gguf-node via comfyui
- drag qwen-image to >
./ComfyUI/models/diffusion_models - drag qwen2.5-vl-7b [4.43GB] to >
./ComfyUI/models/text_encoders - drag pig [254MB] to >
./ComfyUI/models/vae
<Gallery />
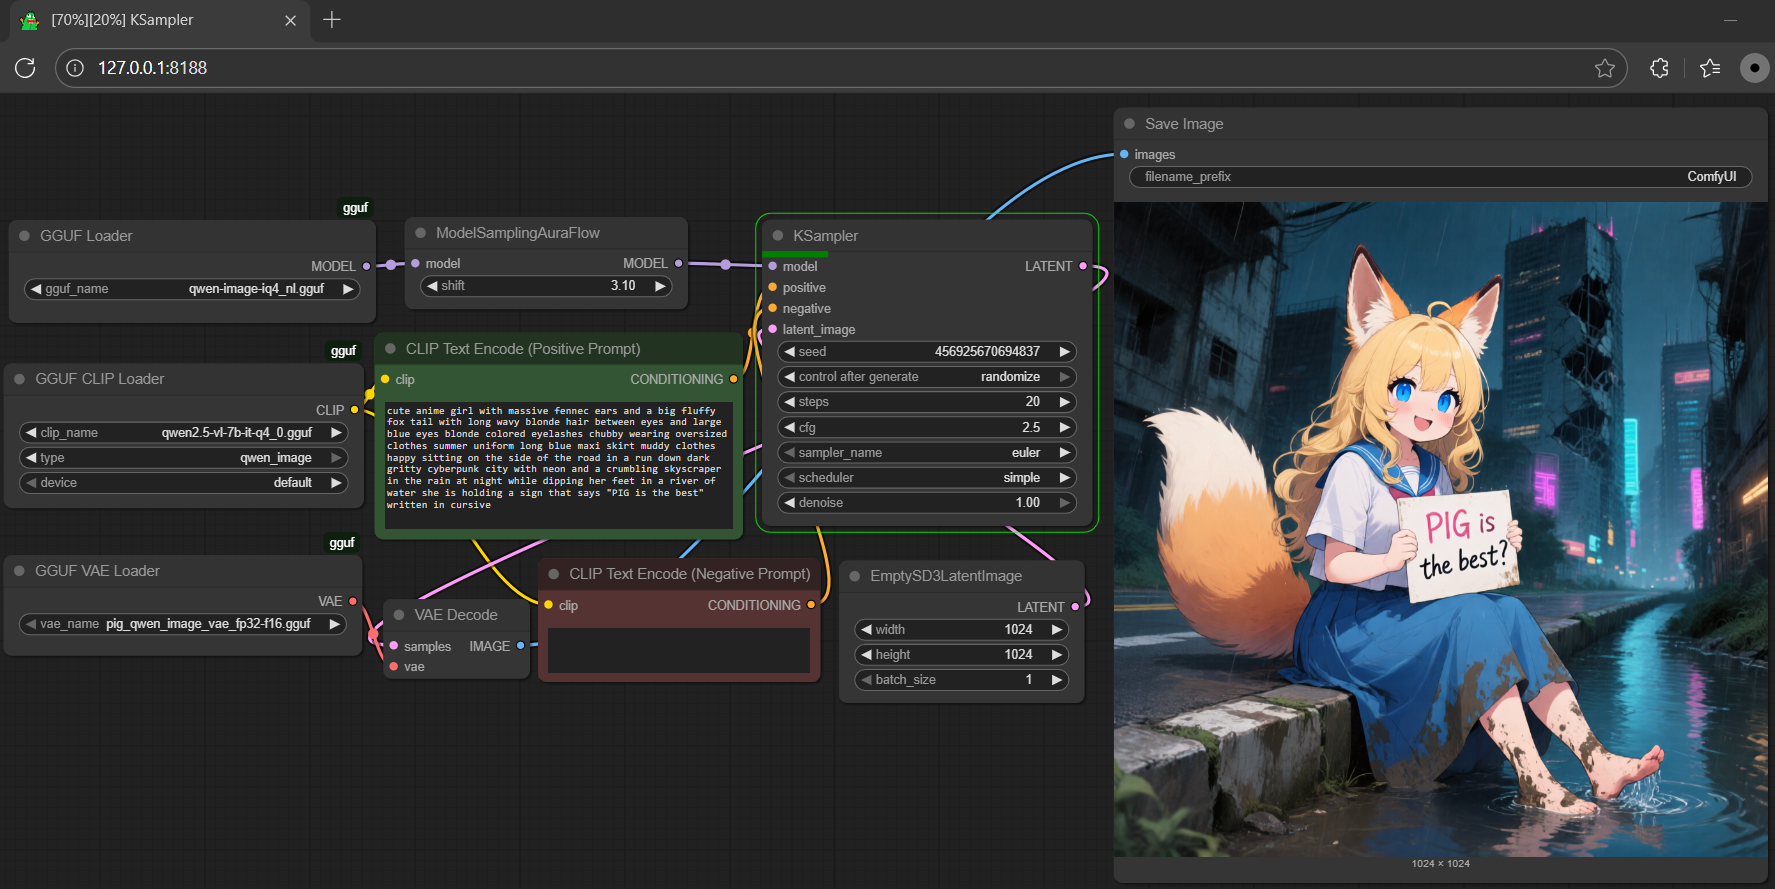
tip: the text encoder used for this model is qwen2.5-vl-7b; get more encoder either here (pig quant) or here (llama.cpp quant); the size is different from the one (qwen2.5-vl-3b) used in omnigen2
run it with diffusers
import torch
from diffusers import DiffusionPipeline, GGUFQuantizationConfig, QwenImageTransformer2DModel

model_path = "https://huggingface.co/calcuis/qwen-image-gguf/blob/main/qwen-image-q2_k.gguf"
transformer = QwenImageTransformer2DModel.from_single_file(
    model_path,
    quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16),
    torch_dtype=torch.bfloat16,
    config="callgg/qi-decoder",
    subfolder="transformer"
)
pipe = DiffusionPipeline.from_pretrained(
    "callgg/qi-decoder",
    transformer=transformer,
    torch_dtype=torch.bfloat16,
)
pipe.enable_model_cpu_offload()

prompt = "a pig holding a sign that says hello world"
positive_magic = {"en": "Ultra HD, 4K, cinematic composition."}
negative_prompt = " "
image = pipe(
    prompt=prompt + positive_magic["en"],
    negative_prompt=negative_prompt,
    height=1024,
    width=1024,
    num_inference_steps=24,
    true_cfg_scale=2.5,
    generator=torch.Generator()
).images[0]
image.save("output.png")
note: diffusers not yet supported t and i quants; opt gguf-node via comfyui or run it straight with gguf-connector
reference
- base model from qwen
- distilled model from modelscope
- lite model is a lora merge from lightx2v
- comfyui from comfyanonymous
- diffusers from huggingface
- gguf-node (pypi|repo|pack)
- gguf-connector (pypi)