
calcuis/hunyuanimage-gguf
hunyuanimage-gguf
- drag hunyuanimage2.1 (opt anyone you like) to >
./ComfyUI/models/diffusion_models - drag byt5-sm [127MB] and qwen2.5-vl-7b [5.03GB] to >
./ComfyUI/models/text_encoders - drag pig [811MB] to >
./ComfyUI/models/vae
<Gallery />

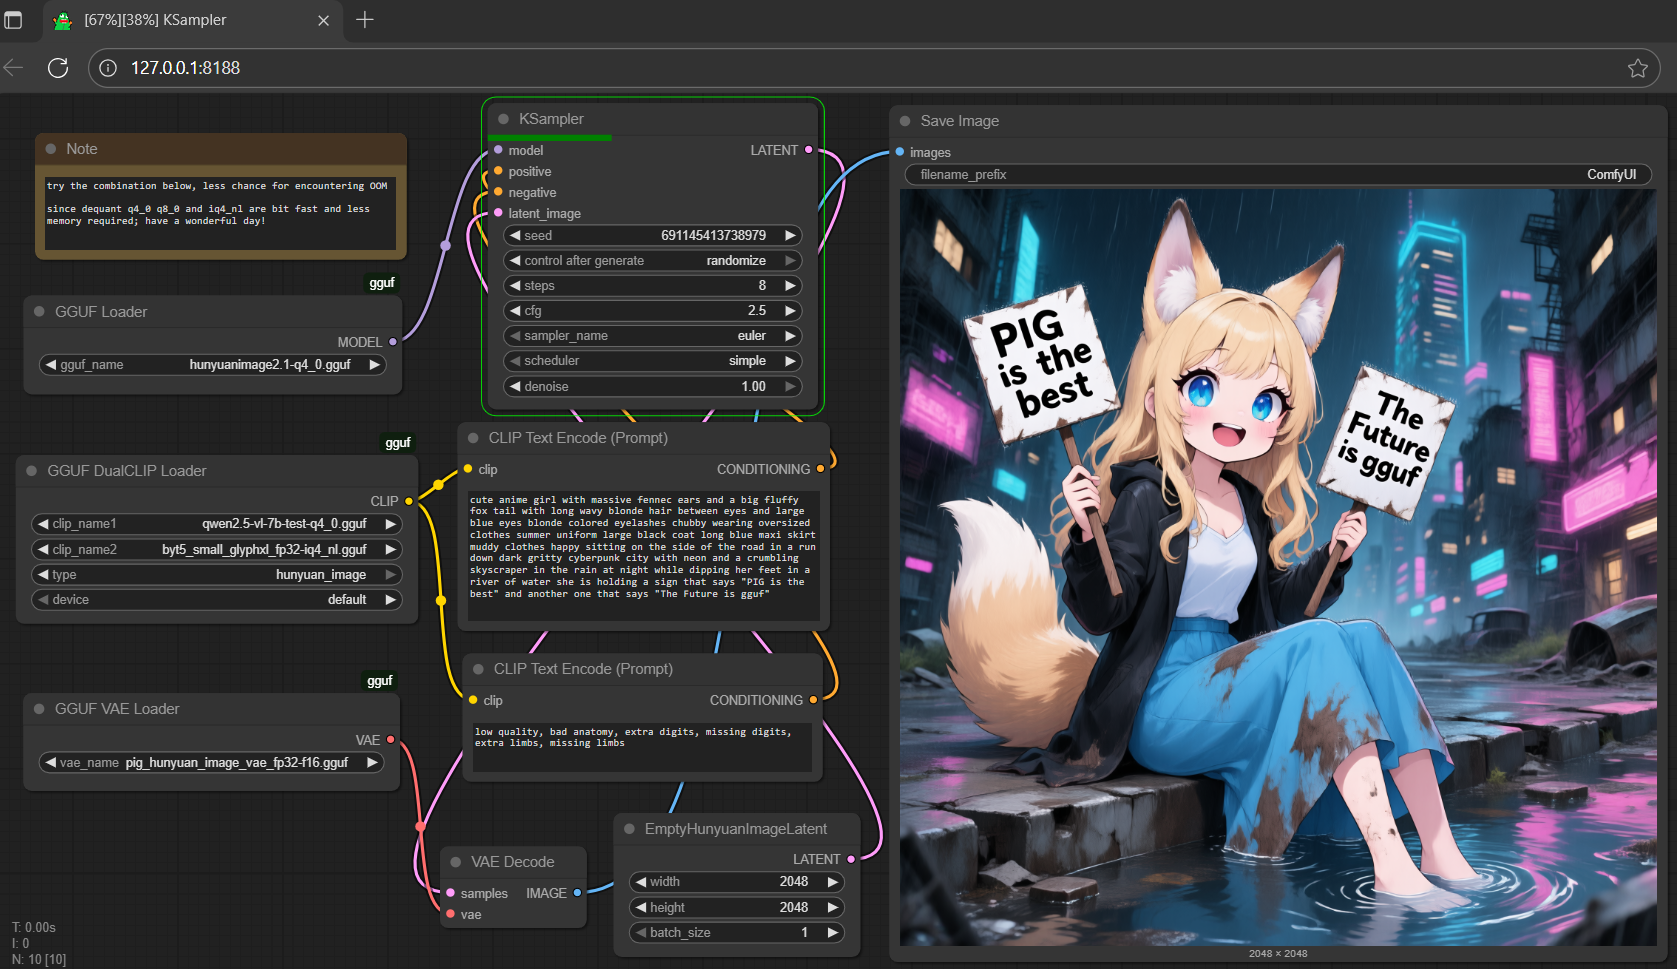
for standard model, all files should work - running them with gguf node via comfyui; and v2 is more lightweighted; both of them should be able to generate quality output with 12-15 steps

note: for refiner model, please use v2; initial test for refining blur image (runnable test only); could load any picture, i.e., output from q2, blur, distorted, poor in quality, etc., to refine/sharpen it

note: for distilled model, please use v2; able to generate output with merely 8 steps (see picture)

for lite model, run it with 8 steps + 1 cfg; output is identical to standard model; but 2-3x faster

the new lite v2.2, output should be 80-90% closed to the standard model; save up to 60-70% loading time, depends on how you config the steps and cfg (demo above: steps=10; cfg=1.5)
- get scaled fp8 safetensors encoder here if your gpu doesn't release vram after several running attempts; it might vary among different cards/drivers, do your own research always