
anakin87/LFM2-2.6B-mr-tictactoe
LFM2-2.6B-mr-tictactoe
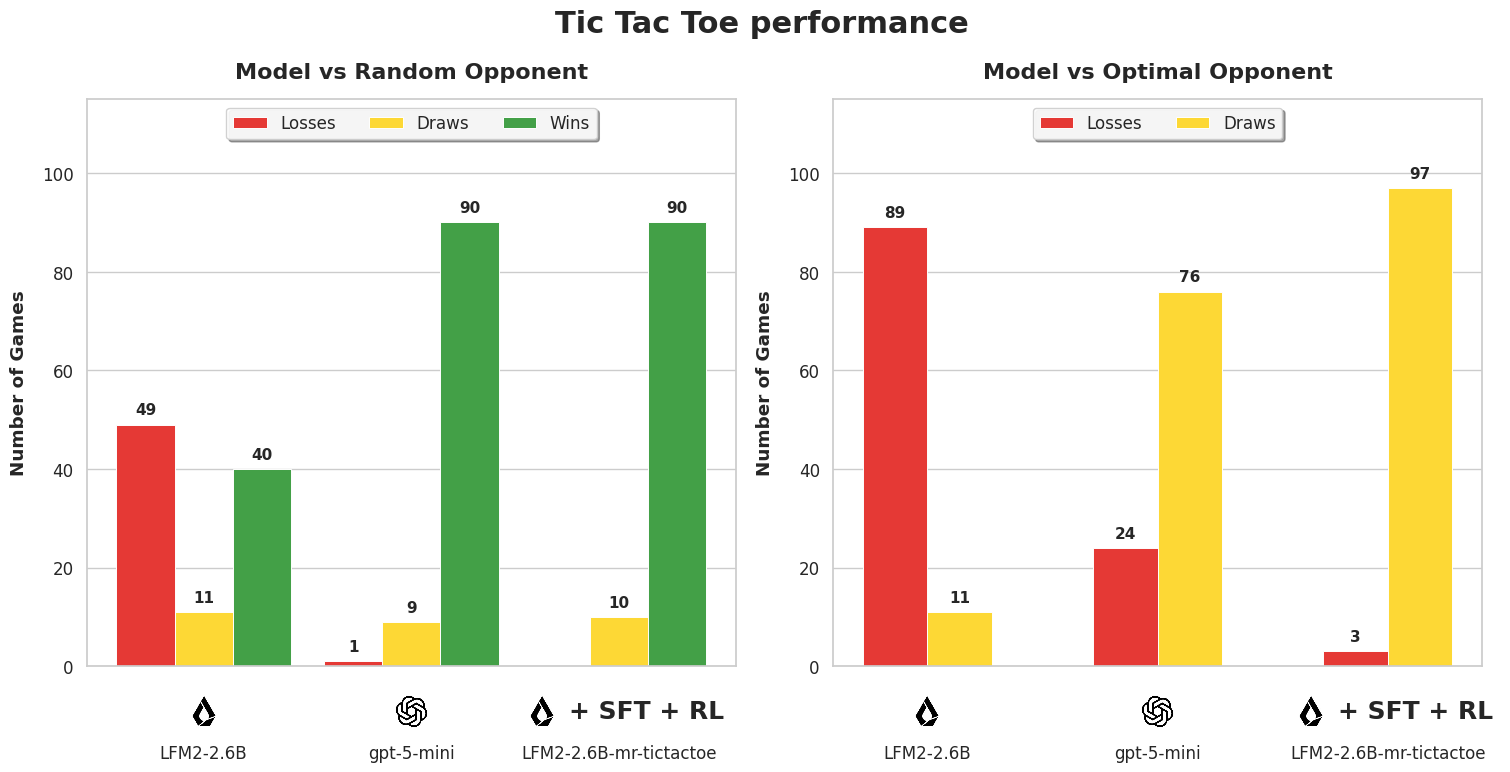
A 2.6B parameter model that plays near-perfect Tic Tac Toe, outperforming openai/gpt-5-mini on this task.
Built from LiquidAI/LFM2-2.6B through a full training pipeline: Supervised Fine-Tuning on synthetic data, followed by two rounds of Reinforcement Learning (CISPO) in a verifiable Tic Tac Toe environment.
This model was developed as part of 🎓 [LLM RL Environments Lil Course](https://github.com/anakin87/llm-rl-environments-lil-course), a hands-on course on building RL environments for Language Models, where models learn from rewards, not examples. It walks through the full process of turning a small open model into a specialist that outperforms a large proprietary one on a specific task (Tic Tac Toe).
🤗🕹️ [Play against Mr. Tic Tac Toe](https://huggingface.co/spaces/anakin87/LFM2-2.6B-mr-tictactoe)
Training pipeline
Evaluation
100 games per setting. The model plays as X (first mover) against a Minimax-based opponent.
Training details
- Algorithm: CISPO (two rounds), using Verifiers RLTrainer
- Environment: anakin87/tictactoe (Verifiers environment)
- LoRA rank: 8
- Hardware: 2x NVIDIA RTX Pro 6000 (round 1), 2x NVIDIA H200 (round 2)
- Training time: ~8 hours per round
- W&B project: LFM2-2.6B Tic Tac Toe