
ZeyuLing/motius-condmdi-humanml3d
<h1 align="center">CondMDI Model Card</h1>
<p align="center"> <strong>Text-guided motion synthesis with flexible frame and joint controls.</strong> </p>
<p align="center"> <a href="https://arxiv.org/abs/2405.11126">Paper</a> | <a href="https://setarehc.github.io/CondMDI/">Project Page</a> | <a href="https://github.com/setarehc/diffusion-motion-inbetweening">Original GitHub</a> | <a href="https://huggingface.co/ZeyuLing/motius-condmdi-humanml3d">Motius Checkpoint</a> </p>
CondMDI is the unified diffusion model from Flexible Motion In-betweening with Diffusion Models (Cohan et al., SIGGRAPH 2024). It accepts text together with arbitrary observed frames or joint subsets. The Motius release packages the official randomly sampled frames-and-joints checkpoint behind one pipeline for text-to-motion, keyframe in-betweening, trajectory control, and partial-body control.
Preview
014457 | the person swings a golf club. | 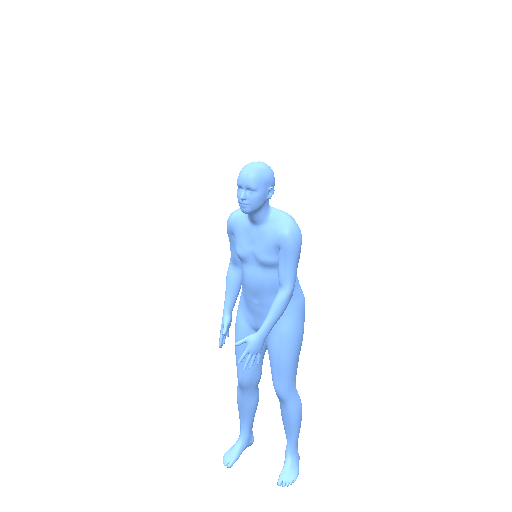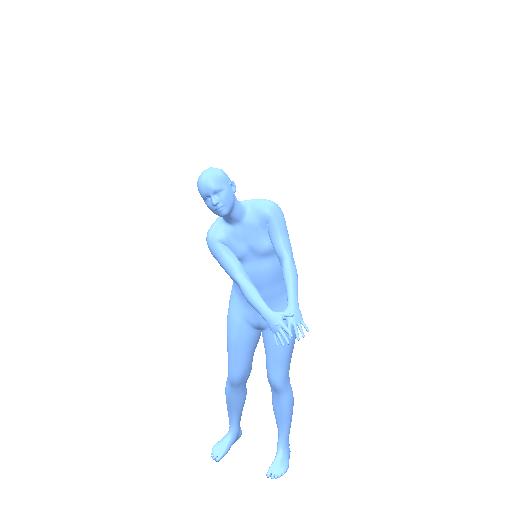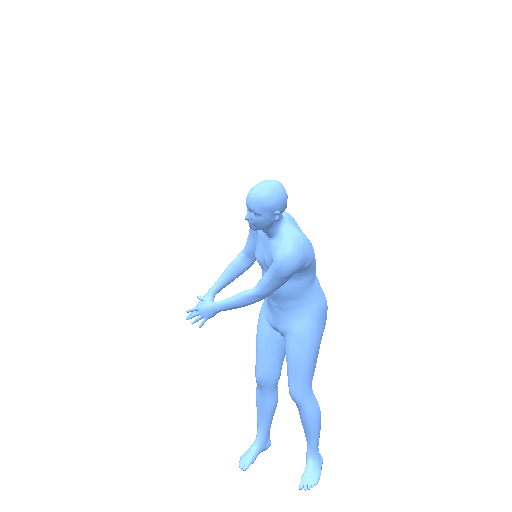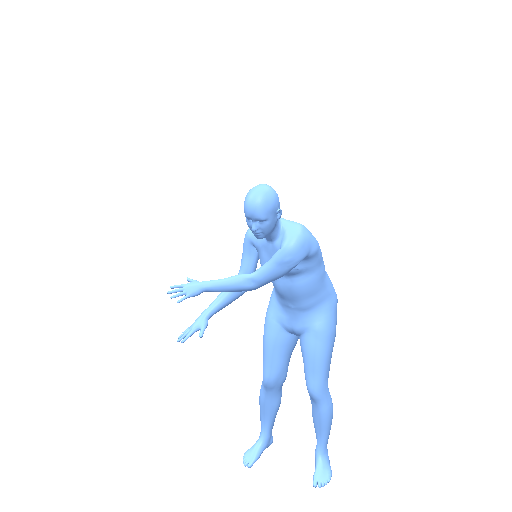 |
001840 | hands in fighting position while the left foot kicks aggressively up and over. | 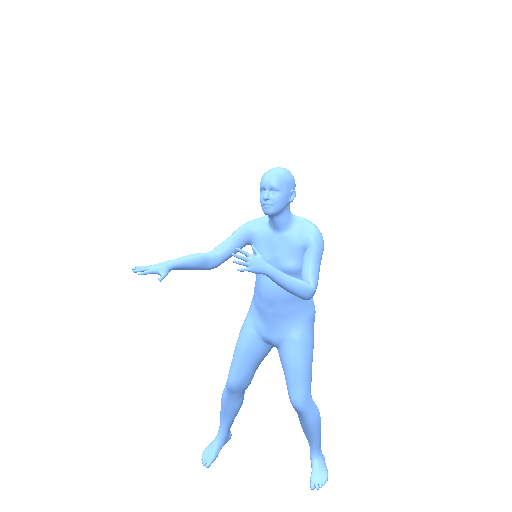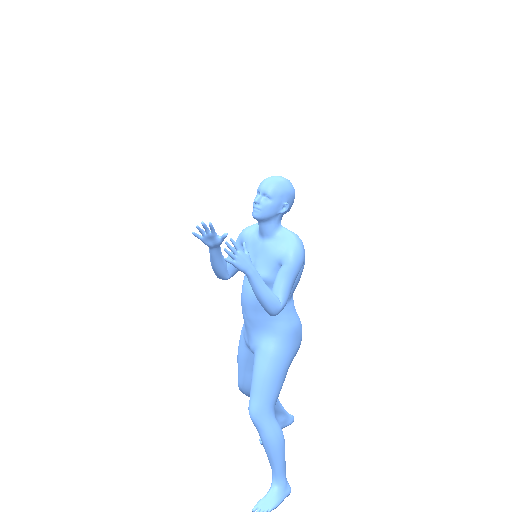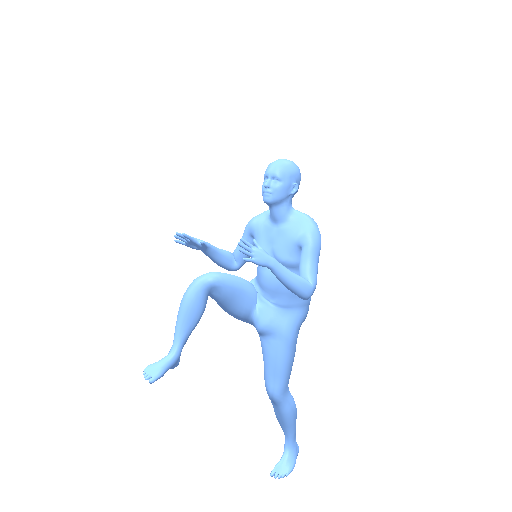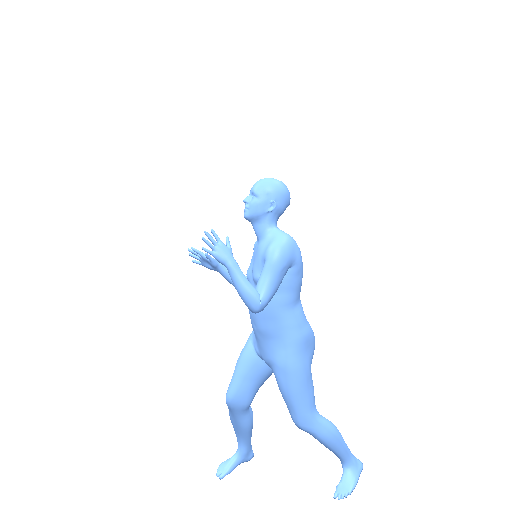 |
006944 | the person who does arms straight out and then it's doing something with their right hand in front of their face. |  |
512px / 30fps GIF previews rendered from released HumanML3D test outputs.
Release Snapshot
The Hugging Face artifact is self-contained apart from the frozen OpenAI CLIP text encoder. It contains SafeTensors weights, the exact network and diffusion configuration, and the official absolute-root normalization statistics. No upstream source checkout or dataset directory is needed at runtime.
For offline inference, set MOTIUS_CLIP_PATH to a local OpenAI CLIP ViT-B/32 checkpoint. MOTIUS_CLIP_CACHE can instead redirect the normal CLIP download cache.
Usage
Install the method-specific dependencies:
pip install -e ".[condmdi]"Text-to-motion generation:
from motius.pipelines.condmdi import CondMDIPipeline

pipe = CondMDIPipeline.from_pretrained(
    "ZeyuLing/motius-condmdi-humanml3d",
    bundle_kwargs={"respacing": "ddim100"},
    device="cuda",
)

motions = pipe.infer_t2m(
    ["a person walks forward and waves with the right hand"],
    [120],
    seed=42,
)
First-and-last-frame in-betweening uses a standard HML263 reference motion:
controlled = pipe.infer_control(
    ["a person turns around and walks away"],
    [reference_hml263],
    control_mode="first_last",
    transition_length=10,
    seed=42,
)
Other built-in control modes include start, sparse, prefix, suffix, middle, trajectory, lower_body, pelvis_feet, pelvis_vr, and joints. For arbitrary controls, pass an (B, 263, 1, T) Boolean observation_mask or provide keyframe_indices. All returned arrays have shape (T, 263) in the standard, denormalized HumanML3D representation.
Evaluation Results
Text-to-Motion
Protocol: all 4,042 motions are generated from the HumanML3D selected-caption test manifest. The official evaluator consumes 3,970 valid HumanML3D clips; the MotionStreamer retrieval evaluator consumes 4,032 complete batch entries; the Motius evaluator pairs 4,034 SMPL-22 motions. Results use one deterministic generation per caption and one metric repeat. For FID and MM-Dist, lower is better.
The Motius row reports raw embedding-space FID for consistency with the public T2M leaderboard; its L2-normalized FID is 0.1919. MotionStreamer and Motius evaluation first convert every output through the same SMPL-22 skeleton bridge.
Physical diagnostics use all 4,042 converted SMPL motions. Lower is better for all metrics; PoseQ is the MBench NRDF pose-quality score.
Motion Control
Control results use 4,012 HumanML3D test motions. Start 1f observes the first frame, Both 1f observes the first and last frames, Prefix 20 observes the first 20 frames, and Middle 80 observes a centered 80-frame interval.
The following reconstruction and physical diagnostics are computed on the same 4,012 cases after conversion to the shared SMPL-22 skeleton. MPJPE and P-MPJPE are in meters; lower is better for every column.
Motion Representation
The official CondMDI model changes the four root channels of HumanML3D-263 from root-relative velocities to absolute yaw and horizontal translation. All remaining joint, rotation, velocity, and contact channels keep their original HumanML3D layout.
Motius performs this conversion inside the pipeline:
- Standard HML263 input is integrated into the official absolute-root form.
- The official normalization statistics are applied before diffusion.
- The generated root trajectory is converted back to standard relative HML263 before it is returned.
This keeps public CondMDI outputs compatible with the representation toolkit, SMPL renderer, and all three T2M evaluators. The conversion round-trip matches the official formulation to floating-point precision for every recoverable frame; as with standard HML263, the final forward root delta is not encoded.
Motius Components
The vendored method runtime retains the upstream MIT license in motius/models/condmdi/LICENSE.
Reproduction Check
The migrated network was checked against the official implementation using the same checkpoint, text embedding, input tensor, and diffusion timestep. A single UNet forward pass differs by at most 1.41e-5 (6.45e-7 mean absolute error). For a complete 100-step fp16 sample, accumulated mean absolute error is 8.62e-4 (1.59e-2 maximum).
Citation
@inproceedings{cohan2024flexible,
  title={Flexible Motion In-betweening with Diffusion Models},
  author={Cohan, Setareh and Tevet, Guy and Reda, Daniele and Peng, Xue Bin and van de Panne, Michiel},
  booktitle={ACM SIGGRAPH 2024 Conference Proceedings},
  year={2024}
}
Direct Loading
from motius import Pipeline

pipeline = Pipeline.from_pretrained("ZeyuLing/motius-condmdi-humanml3d")