
WICKED4950/BwETAFv2-53M
0
🧾 BwETAFv2-53M: Model Card
Boring’s Experimental Transformer for Autoregression (Flax) A 53M parameter autoregressive language model built using a custom Flax pipeline, loads of tuning, and a sprinkle of existential dread.
Trained on determination, fueled by suffering, powered by free TPUs.
📌 Model Summary
- Model Name: BwETAFv2-53M
- Parameters: 53,012,480
- Training Tokens: 1,348,599,808
- Training Time: 3.21 TPUv2-8 Hours
- Framework: Flax / JAX
- Max Context Length: 2048 tokens
- Tokenizer: GPT-2 BPE (50,257 vocab size)
🧪 Hyperparameters
{
  "num_heads": 8,
  "attention_dim": 512,
  "vocab_size": 50260,
  "num_blocks": 8,
  "ff_dim": 1536,
  "dropout_rate": 0.1,
  "max_len": 2048,
  "emb_splt": 256,
  "attn_chunks": 1,
  "use_flash_attention": false,
  "emb_init_range": 0.02,
  "use_rope": true,
  "emb_scaling_factor": 1,
  "res_scale": 1
}
🛠 Optimizer Settings
{
  "peaklr": 1.3e-3,
  "warmup_percent": 0.04,
  "min_value": 1e-7,
  "training_decay": "cosine",
  "weight_decay": 0.1,
  "b1": 0.87,
  "b2": 0.94,
  "eps": 1e-6
}
📈 Performance
- Final Validation Loss:
3.7718 - Validation loss Graphs:
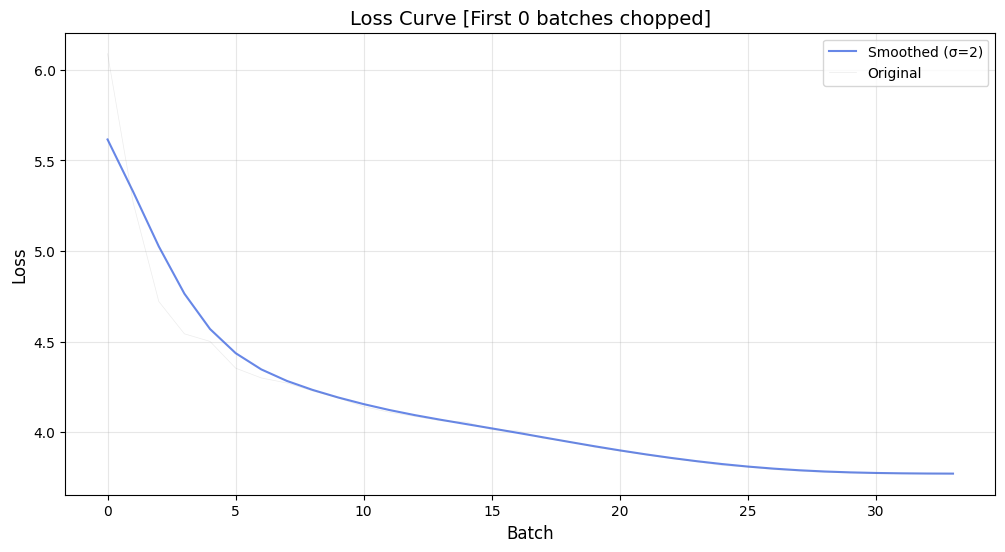
- Training loss Graphs:
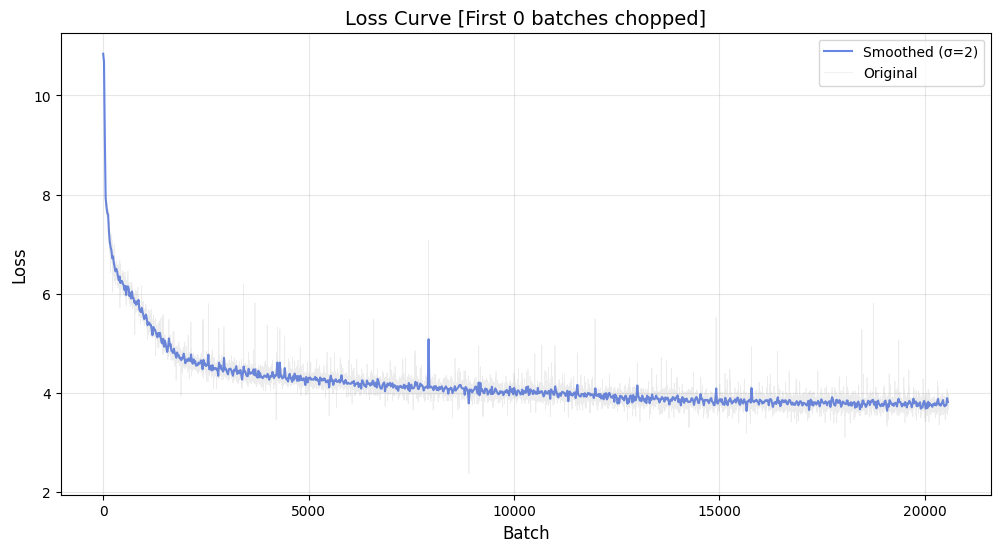
- For detailed stats, refer to
stats.jsonin the model files.
⚡ Quickstart
pip install BwETAF==0.5.1import BwETAF
# 🔍 Quick API test
prompt = "The meaning of life is"
output = BwETAF.SetUpAPI(prompt, "WICKED4950/BwETAFv2-53M")
print(output)
# ⬇️ Load from Hugging Face Hub
model = BwETAF.load_hf("WICKED4950/BwETAFv2-53M")
# 📁 Load from local path
BwETAF.load_model("path/to/model")
# 💾 Save to local directory
model.save_model("path/to/save")
# 🔧 Inspect model
params = model.trainable_variables
structure = model.model_struct☁️ Colab support and examples coming soon!
🧠 BwETAFv2 Architecture Overview
The BwETAFv2 architecture introduces several refinements over its predecessors, improving convergence, training stability, and scalability. Below is an architecture-level overview shared across all models in this series.
🔩 Core Architecture
- Attention: Standard multi-head self-attention (no GQA, no MQA, no FlashAttention)
- FFN: Uses Swish-GLU with FF dimension =
3 × model_dim - Norm Layer: RMSNorm, pre-layer
- Positional Encoding: RoPE on embeddings and K/Q vectors
- Precision:
- Weights & forward pass:
bfloat16 (bf16) - Optimizer states:
float32 - Tokenization: GPT-2 BPE (
vocab_size = 50257) - Bias Terms: No biases in K/Q/V dense projections
⚙️ Training Setup
- Optimizer: AdamW
- Batch Size: 32 per step
- Learning Schedule: Cosine decay with linear warmup (4%)
- Chinchilla Scaling Law: Followed (20× tokens per parameter)
- Context Window during Training:
- BwETAFv2-53M: 2048
- BwETAFv2-130M: 4096
📊 Model Comparison
📬 Contact Me
- 📸 Instagram: boring.\_.wicked
- 💬 Discord:
fused_computation.1(if you spot me lurking in any AI-related servers)