
WICKED4950/BwETAF-IID-400M
0
⚙️ BwETAF-IID-400M — Model Card
Boring’s Experimental Transformer for Autoregression (Flax) A 378M parameter autoregressive transformer built with a custom training pipeline and questionable life choices.
Trained on determination, fueled by suffering, powered by free TPUs. 🔥
📊 Model Overview
- Name: BwETAF-IID-400M
- Parameters: 378,769,408
- Tokens Seen: 6,200,754,176
- Training Time: 63,883.53 sec
- Framework: Flax + JAX
- Context Window: 512 tokens
- Tokenizer: GPT-2 BPE (50,257)
- Positional Encoding: Sin/Cos
- Activation Function: SwiGLU
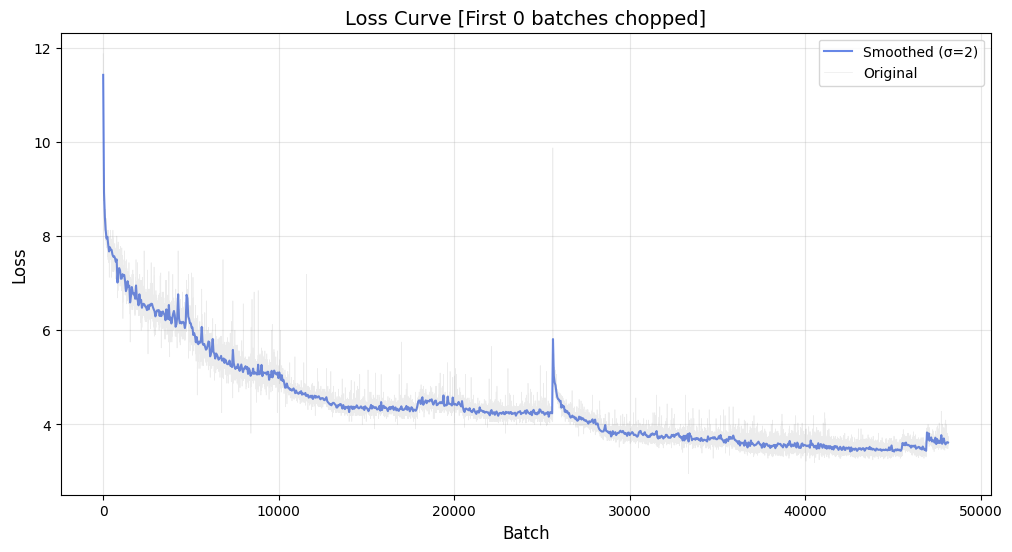
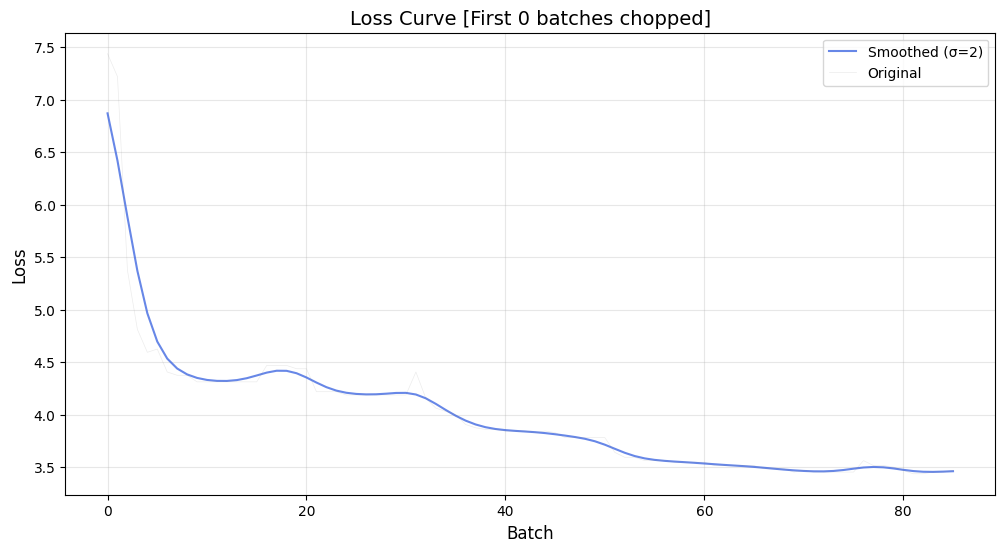
- Final Validation Loss: ~3.4
📈 Training & Validation Loss
Training Loss
Validation Loss
🤔 Why BwETAF?
- ⚙️ Built from scratch — No hugging-face trainer shortcuts here.
- 🔬 Flexible architecture — Swap blocks, change depths, scale it how you want.
- 🧪 Experimental core — Try weird ideas without breaking a corporate repo.
- ⚡ TPU-optimized — Trained on free Google TPUs with custom memory-efficient formats.
- 📦 Lightweight-ish — You can actually run this model without a data center.
⚡ Quickstart
pip install BwETAF==0.4.2import BwETAF
# Quick API testing
prompt = "The meaning of life is"
output = BwETAF.SetUpAPI(prompt, "WICKED4950/BwETAF-IID-400M")
print(output)
# Load from Hugging Face
model = BwETAF.load_hf("WICKED4950/BwETAF-IID-400M")
# Load from local
BwETAF.load_model("path/to/model")
# Save the model
model.save_model("path/to/save")
# View params & structure
params = model.trainable_variables
structure = model.model_struct☁️ Google collab notes not updated for now
🚧 Known Limitations
- Did not meet target benchmark (aimed for ≤2.7, got \~3.4)
- No fine-tuning or task-specific optimization
- Early stopping due to saturation
- Works, but won’t win any LLM trophies (yet)
📩 Reach Out
Got questions, bugs, or chaos to share? Ping me on Instagram: [Here](https://www.instagram.com/boring._.wicked/?__pwa=1) I like weird LLM experiments and random ML convos 💬
🔮 Upcoming Experiments
- 🚀 BwETAF-IID-1B: Scaling this mess further
- 🧬 Layer rewrite tests: Because the FFN deserves some drama
- 🌀 Rotary + sparse attention tests
- 🧃 Trying norm variations for training stability