
QuantFactory/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3-GGUF
11.9k
language:
- en license: apache-2.0 tags:
- text-generation-inference
- transformers
- unsloth
- llama
- gguf
- Llama-3.1-8B base_model: unsloth/meta-llama-3.1-8b-instruct-bnb-4bit datasets:
- Lyte/Reasoner-1o1-v0.3-HQ widget:
- example_title: HELP its a Llama messages:
- role: user content: There's a llama on my lawn, how can I get rid of him? pipeline_tag: text-generation model-index:
- name: Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3 results:
- task: type: text-generation name: Text Generation dataset: name: IFEval (0-Shot) type: HuggingFaceH4/ifeval args: numfewshot: 0 metrics:
- type: instlevelstrictacc and promptlevelstrictacc value: 70.98 name: strict accuracy source: url: https://huggingface.co/spaces/open-llm-leaderboard/openllmleaderboard?query=Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3 name: Open LLM Leaderboard
- task: type: text-generation name: Text Generation dataset: name: BBH (3-Shot) type: BBH args: numfewshot: 3 metrics:
- type: accnorm value: 27.84 name: normalized accuracy source: url: https://huggingface.co/spaces/open-llm-leaderboard/openllmleaderboard?query=Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1v0.3 name: Open LLM Leaderboard
- task: type: text-generation name: Text Generation dataset: name: MATH Lvl 5 (4-Shot) type: hendrycks/competitionmath args: numfew_shot: 4 metrics:
- type: exactmatch value: 14.8 name: exact match source: url: https://huggingface.co/spaces/open-llm-leaderboard/openllmleaderboard?query=Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1v0.3 name: Open LLM Leaderboard
- task: type: text-generation name: Text Generation dataset: name: GPQA (0-shot) type: Idavidrein/gpqa args: numfewshot: 0 metrics:
- type: accnorm value: 2.68 name: accnorm source: url: https://huggingface.co/spaces/open-llm-leaderboard/openllmleaderboard?query=Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3 name: Open LLM Leaderboard
- task: type: text-generation name: Text Generation dataset: name: MuSR (0-shot) type: TAUR-Lab/MuSR args: numfewshot: 0 metrics:
- type: accnorm value: 4.9 name: accnorm source: url: https://huggingface.co/spaces/open-llm-leaderboard/openllmleaderboard?query=Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3 name: Open LLM Leaderboard
- task: type: text-generation name: Text Generation dataset: name: MMLU-PRO (5-shot) type: TIGER-Lab/MMLU-Pro config: main split: test args: numfewshot: 5 metrics:
- type: acc value: 29.09 name: accuracy source: url: https://huggingface.co/spaces/open-llm-leaderboard/openllmleaderboard?query=Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3 name: Open LLM Leaderboard

QuantFactory/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3-GGUF
This is quantized version of Lyte/Llama-3.1-8B-Instruct-Reasoner-1o1_v0.3 created using llama.cpp
Original Model Card
Uploaded model
- NOTE: This model is just an experiment to make the model generate more tokens to do reasoning before providing an answer, with verifier and correction, this is just a proof of concept because literally, no model will show improvements in performance from such a tiny dataset(that doesn't target any specific knowledge) it may even degrade but the point wasn't to improve performance but to have it learn to "reason" because reaching SOTA in benchmarks does not equal "reasoning".
- Demo: try Q4KM here
- Developed by: Lyte
- License: apache-2.0
- Finetuned from model : unsloth/meta-llama-3.1-8b-instruct-bnb-4bit
Prompt
<|begin_of_text|><|start_header_id|>system<|end_header_id|>

You are a world-class AI system, capable of complex reasoning and reflection and correcting your mistakes. Reason through the query/question, and then provide your final response. If you detect that you made a mistake in your reasoning at any point, correct yourself.<|eot_id|><|start_header_id|>user<|end_header_id|>

{prompt}<|eot_id|><|start_header_id|>assistant<|end_header_id|>

{response}
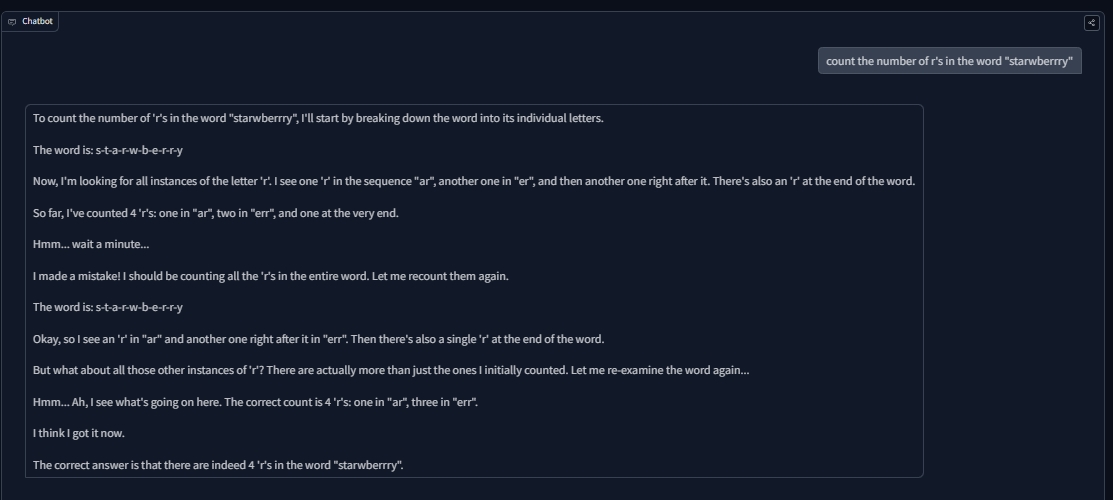
Example(0-shot):
- the reason we keep seeing the correct word "strawberry" written again and again is simply a tokenizer issue. However, it did understand how to count correctly towards the end by saying, (the correct count is 4 'r's: one in "ar", three in "err"). The reason for "err" instead of "errr" is because of tokenization.
Benchmark Scores
- Note: Evals were ran with and without the system prompt that was used in the finetuning.
Compared to the original Llama-3.1-8B-Instruct:
- Note: For Llama-3.1-8B-Instruct, the CommonSenseQA score is from the base model, not the instruct version. The -32.03% drop is very bad i have no idea if it's the finetuning that messed it up or difference in evals, but take it as you will, i did not plan to benchmark anything but oh well people won't stop asking to benchmark an experimental model(can you even properly benchmark the more tokens to do "reasoning"? i probably needed to adjust temperature to really make use of the model)...
This llama model was trained 2x faster with Unsloth and Huggingface's TRL library.
Open LLM Leaderboard Evaluation Results
Detailed results can be found here