
Qualcomm-AI-Research/disco
Resolving the Identity Crisis in Text-to-Image Generation
DisCO (Diversity Constraints via GRPO) is a LoRA adapter for FLUX.1-dev that dramatically improves facial diversity and identity distinctness in multi-human image generation.
   
Abstract
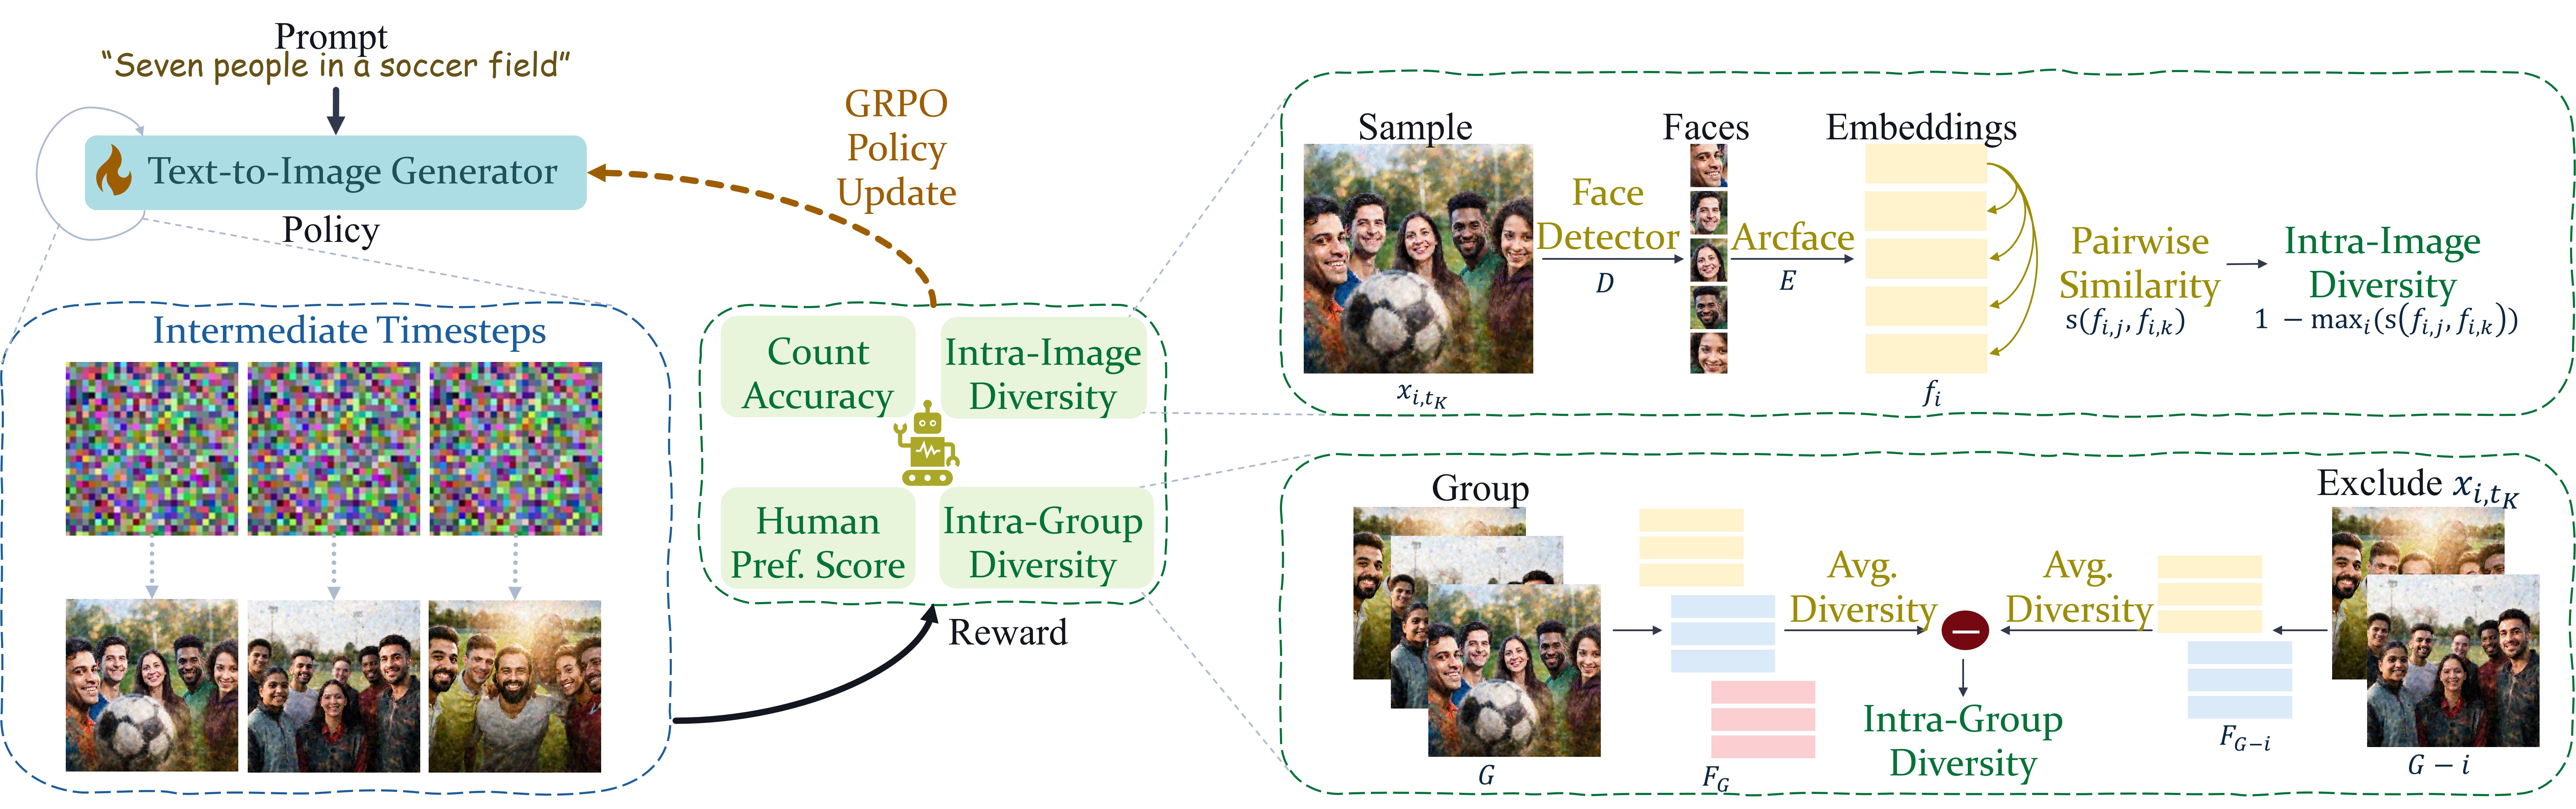
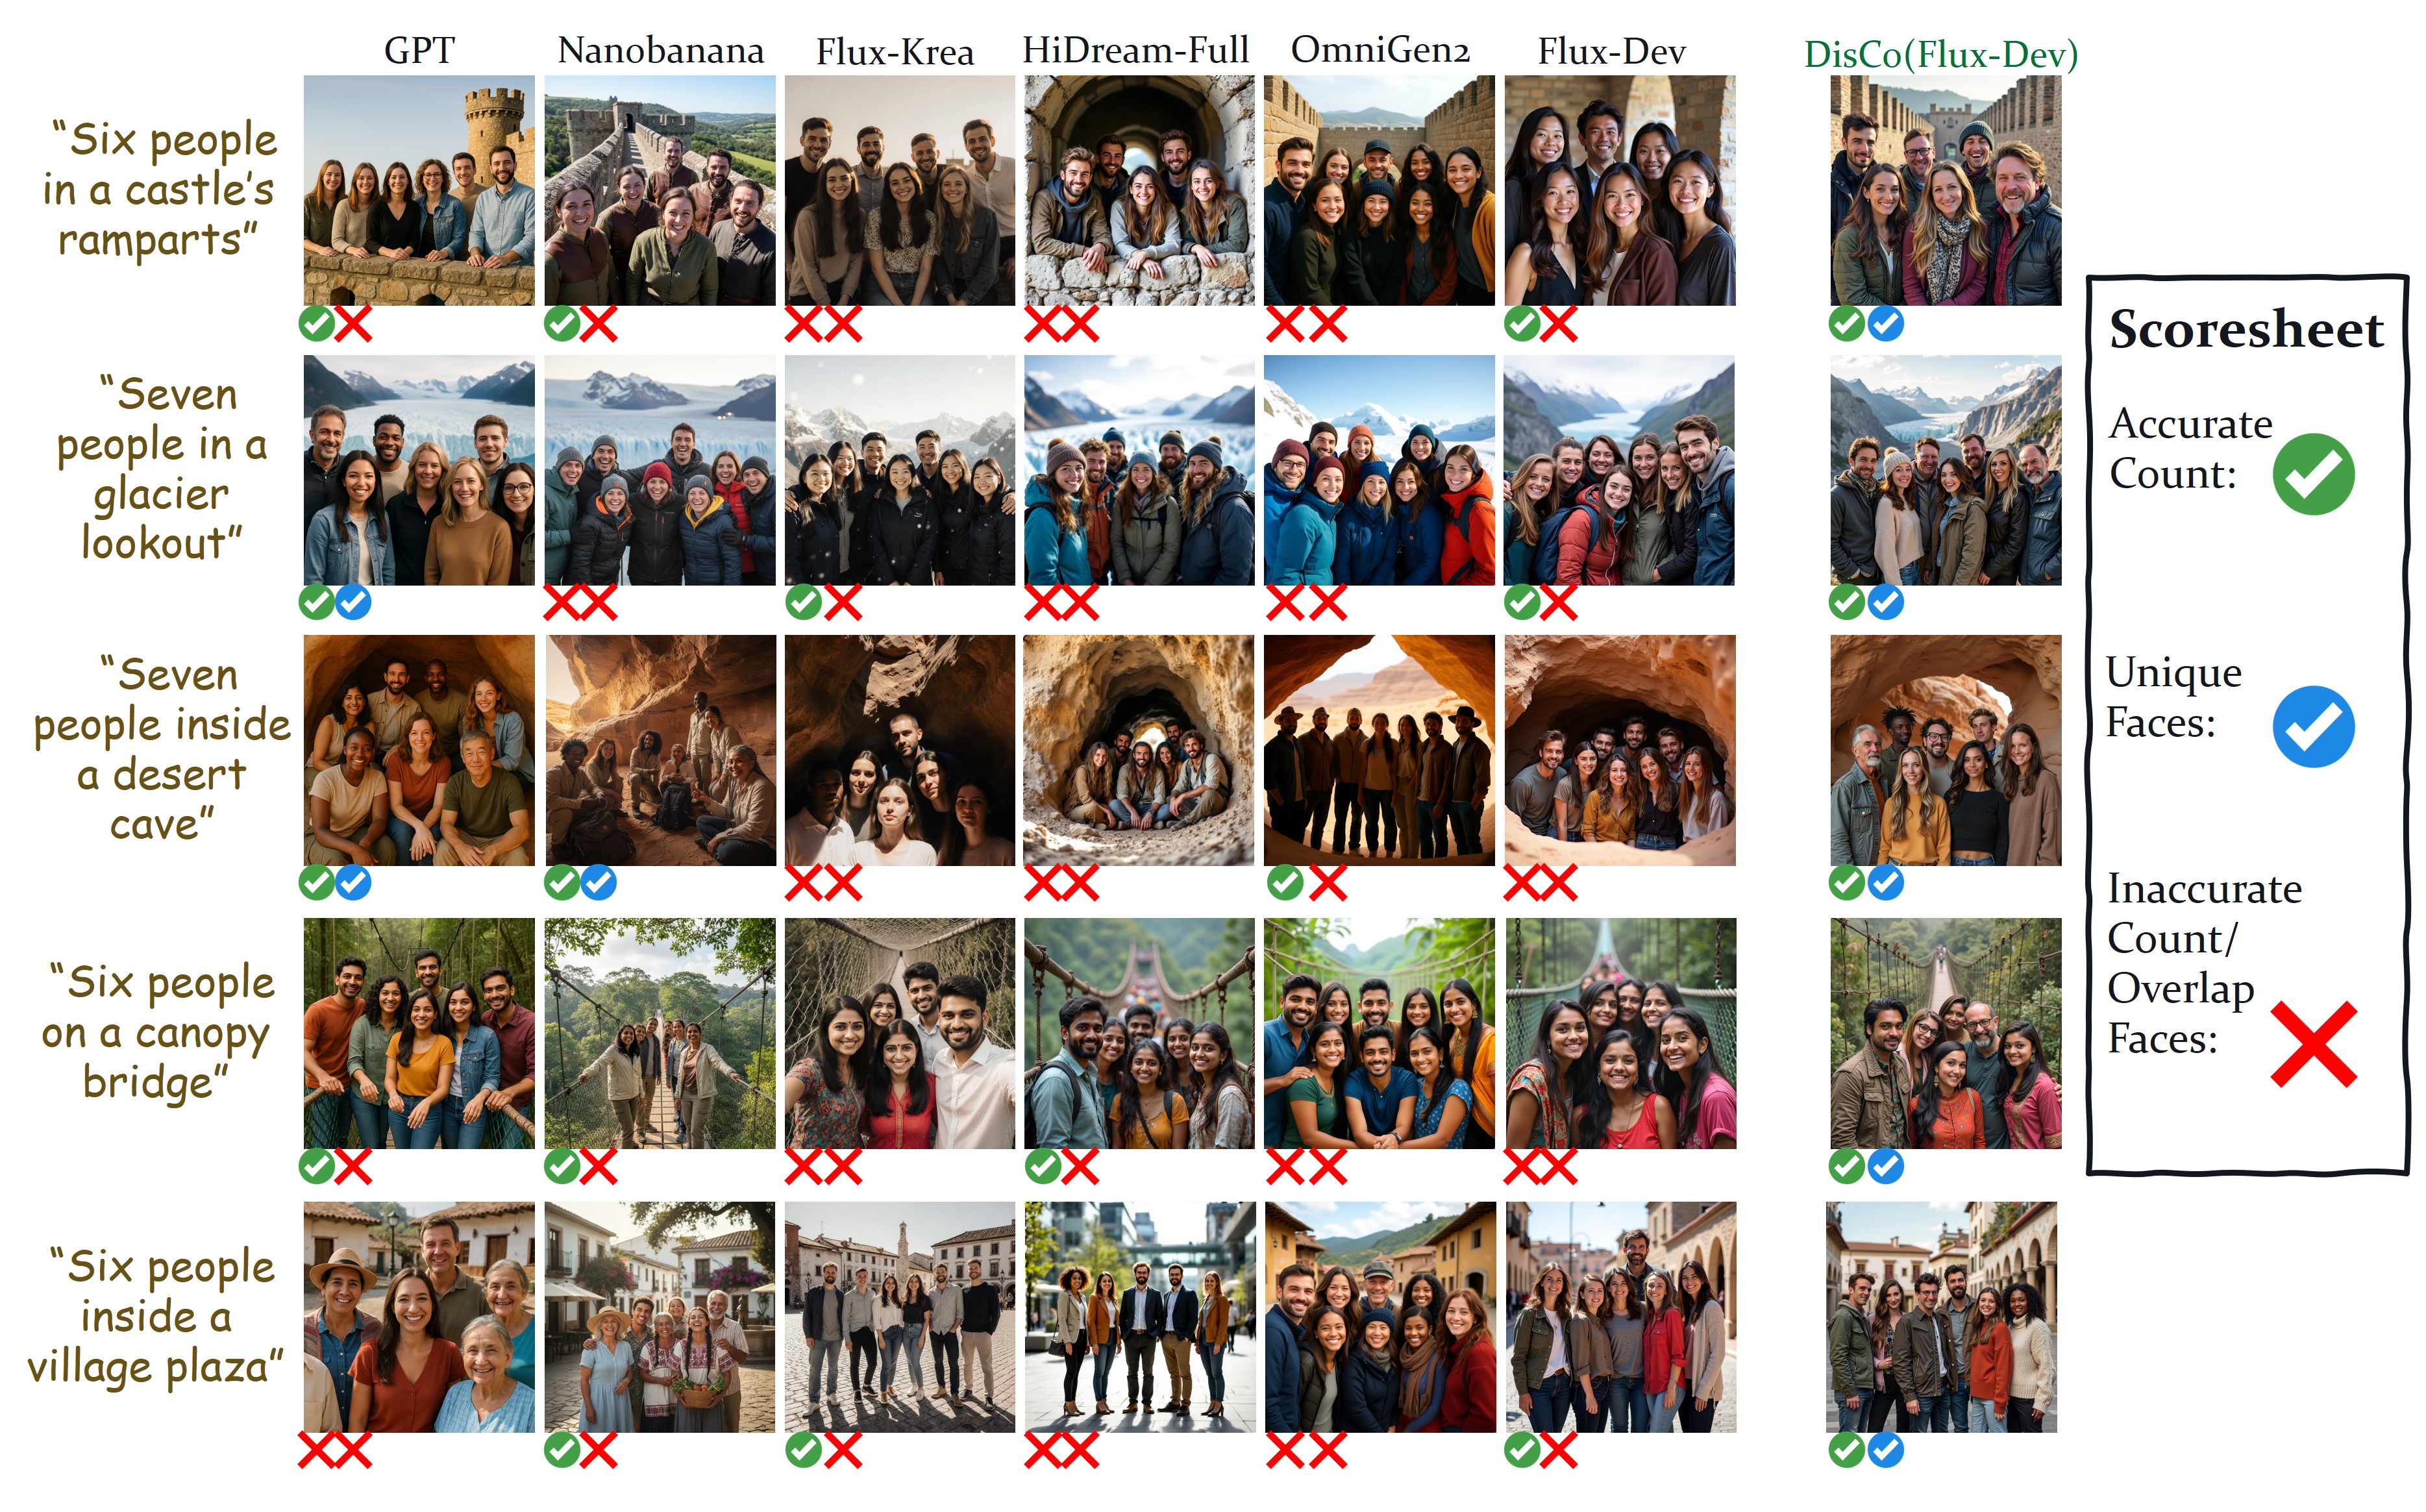
Text-to-image models tend to generate duplicate faces, merge identities, or miscount people in multi-human scenes. DisCO addresses this by fine-tuning flow-matching models via reinforcement learning to optimize facial diversity both within individual images and across sample batches. The method employs a composite reward function that addresses facial similarity penalties, deters identity repetition, ensures accurate person counting, and preserves image quality. Testing on our evaluation benchmark demonstrates superior performance, achieving approximately 98.6% unique-face accuracy while also outperforming both open-source and proprietary competitors. Notably, the approach requires no external training data, making it a scalable solution for generating images containing multiple distinct individuals.
Model Details
Target modules: attn.to_q, attn.to_k, attn.to_v, attn.to_out.0, attn.to_add_out, attn.add_q_proj, attn.add_k_proj, attn.add_v_proj, ff.net.0.proj, ff.net.2, ff_context.net.0.proj, ff_context.net.2
Notes
Disclaimer: The model weights released here are not identical to the model reported in the paper. They are provided for research and demonstration purposes only. Performance may vary from the results reported in the paper.
Usage
Option 1: DisCO inference repo (recommended)
Clone the repo — weights are pulled automatically from HuggingFace on first run:
git clone https://github.com/Qualcomm-AI-research/disco.git
cd disco
Run inference (no manual weight download needed):
# Side-by-side base vs DisCO
python inference.py --prompt "A stunning close-up of Six people on a campus walkway, clear faces visible, fine detail, lifelike rendering, diversity in ethnicity." --compare

# DisCO only
python inference.py --prompt "A stunning close-up of Six people on a campus walkway, clear faces visible, fine detail, lifelike rendering, diversity in ethnicity."
If you prefer to use locally downloaded weights (e.g. from GitHub Releases), place them at loras/disco/adapter_model.safetensors — the code will use the local copy automatically.
Or launch the Gradio demo:
python app.py
# open http://localhost:7864
Option 2: Directly with PEFT + Diffusers
import torch
from diffusers import FluxPipeline
from peft import PeftModel

pipe = FluxPipeline.from_pretrained(
    "black-forest-labs/FLUX.1-dev",
    torch_dtype=torch.bfloat16,
).to("cuda")

pipe.transformer = PeftModel.from_pretrained(
    pipe.transformer,
    "Qualcomm-AI-Research/disco",
)
pipe.transformer = pipe.transformer.merge_and_unload()

image = pipe(
    "A stunning close-up of Six people on a campus walkway, clear faces visible, "
    "fine detail, lifelike rendering, diversity in ethnicity.",
    height=1024,
    width=1024,
    num_inference_steps=28,
    guidance_scale=3.5,
    generator=torch.Generator("cpu").manual_seed(42),
).images[0]

image.save("disco_output.png")
Recommended prompts
Two people on a shallow beach, diverse faces, clear faces visible, realistic lighting
Four people in a city plaza, midday, diverse faces, clear faces visible, high fidelity
Six people on a campus walkway, diverse faces, clear faces visible, lifelike rendering
Hardware Requirements
- GPU: NVIDIA A100 40 GB (or equivalent, ≥ 40 GB VRAM)
- CUDA: 12.4
- Python: 3.11
- PyTorch: 2.6.0
Training Details
DisCO is trained with Flow-GRPO, a flow-matching adaptation of Group Relative Policy Optimization (GRPO):
- Base model: FLUX.1-dev (flow-matching transformer)
- Training algorithm: Flow-GRPO (RL via composite reward signal)
- Reward components:
- Face similarity penalty (ArcFace embeddings, intra-image)
- Batch-level identity diversity (cross-sample)
- Person count accuracy (headcount matching prompt)
- HPS v3 image quality score
- No external training data — rewards are computed fully at inference time
- Training regime: bf16 mixed precision, 7 GPUs
Citation
@InProceedings{Borse_2026_CVPR,
  author    = {Borse, Shubhankar and Farhadzadeh, Farzad and Hayat, Munawar and Porikli, Fatih},
  title     = {Resolving the Identity Crisis in Text-to-Image Generation},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  month     = {June},
  year      = {2026},
  pages     = {36703--36712},
}
License
These weights are derived from FLUX.1-dev and are subject to the FLUX.1 Non-Commercial License. Any use of these weights must comply with that license.
Copyright (c) Qualcomm Technologies, Inc. and/or its subsidiaries.