
PsiPi/NousResearch_Nous-Hermes-2-Vision-GGUF
GGUF Quants by Twobob, Thanks to @jartine and @cmp-nct for the assists
It's vicuna ref: here
Caveat emptor: There is still some kind of bug in the inference that is likely to get fixed upstream. Just FYI 
Nous-Hermes-2-Vision - Mistral 7B
In the tapestry of Greek mythology, Hermes reigns as the eloquent Messenger of the Gods, a deity who deftly bridges the realms through the art of communication. It is in homage to this divine mediator that I name this advanced LLM "Hermes," a system crafted to navigate the complex intricacies of human discourse with celestial finesse.
Model description
Nous-Hermes-2-Vision stands as a pioneering Vision-Language Model, leveraging advancements from the renowned OpenHermes-2.5-Mistral-7B by teknium. This model incorporates two pivotal enhancements, setting it apart as a cutting-edge solution:
- SigLIP-400M Integration: Diverging from traditional approaches that rely on substantial 3B vision encoders, Nous-Hermes-2-Vision harnesses the formidable SigLIP-400M. This strategic choice not only streamlines the model's architecture, making it more lightweight, but also capitalizes on SigLIP's remarkable capabilities. The result? A remarkable boost in performance that defies conventional expectations.
- Custom Dataset Enriched with Function Calling: Our model's training data includes a unique feature – function calling. This distinctive addition transforms Nous-Hermes-2-Vision into a Vision-Language Action Model. Developers now have a versatile tool at their disposal, primed for crafting a myriad of ingenious automations.
This project is led by qnguyen3 and teknium.
Training
Dataset
- 220K from LVIS-INSTRUCT4V
- 60K from ShareGPT4V
- 150K Private Function Calling Data
- 50K conversations from teknium's OpenHermes-2.5
Usage
Prompt Format
- Like other LLaVA's variants, this model uses Vicuna-V1 as its prompt template. Please refer to
conv_llava_v1in this file - For Gradio UI, please visit this GitHub Repo
Function Calling
- For functiong calling, the message should start with a
<fn_call>tag. Here is an example:
<fn_call>{
  "type": "object",
  "properties": {
    "bus_colors": {
      "type": "array",
      "description": "The colors of the bus in the image.",
      "items": {
        "type": "string",
        "enum": ["red", "blue", "green", "white"]
      }
    },
    "bus_features": {
      "type": "string",
      "description": "The features seen on the back of the bus."
    },
    "bus_location": {
      "type": "string",
      "description": "The location of the bus (driving or pulled off to the side).",
      "enum": ["driving", "pulled off to the side"]
    }
  }
}
Output:
{
  "bus_colors": ["red", "white"],
  "bus_features": "An advertisement",
  "bus_location": "driving"
}
Example
Chat

Function Calling
Input image:
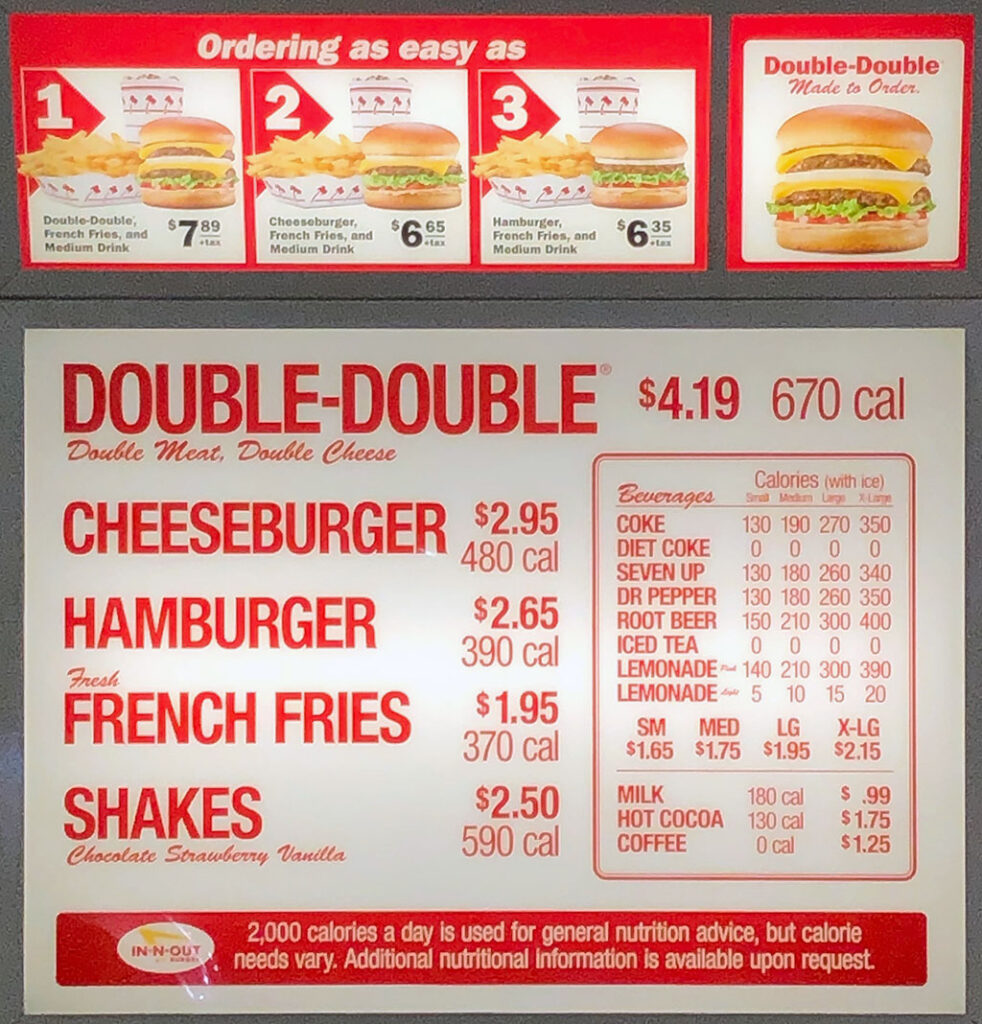
Input message:
<fn_call>{
    "type": "object",
    "properties": {
      "food_list": {
        "type": "array",
        "description": "List of all the food",
        "items": {
          "type": "string",
        }
      },
    }
}
Output:
{
    "food_list": [
        "Double Burger",
        "Cheeseburger",
        "French Fries",
        "Shakes",
        "Coffee"
    ]
}