
MonsterMMORPG/CogVLMFixed
CogVLM2-Video-Llama3-Chat
中文版本README
Introduction
CogVLM2-Video achieves state-of-the-art performance on multiple video question answering tasks. It can achieve video understanding within one minute. We provide two example videos to demonstrate CogVLM2-Video's video understanding and video temporal grounding capabilities.
<table> <tr> <td> <video width="100%" controls> <source src="https://github.com/THUDM/CogVLM2/raw/main/resources/videos/lion.mp4" type="video/mp4"> </video> </td> <td> <video width="100%" controls> <source src="https://github.com/THUDM/CogVLM2/raw/main/resources/videos/basketball.mp4" type="video/mp4"> </video> </td> </tr> </table>
BenchMark
The following diagram shows the performance of CogVLM2-Video on the MVBench, VideoChatGPT-Bench and Zero-shot VideoQA datasets (MSVD-QA, MSRVTT-QA, ActivityNet-QA). Where VCG- refers to the VideoChatGPTBench, ZS- refers to Zero-Shot VideoQA datasets and MV-* refers to main categories in the MVBench.
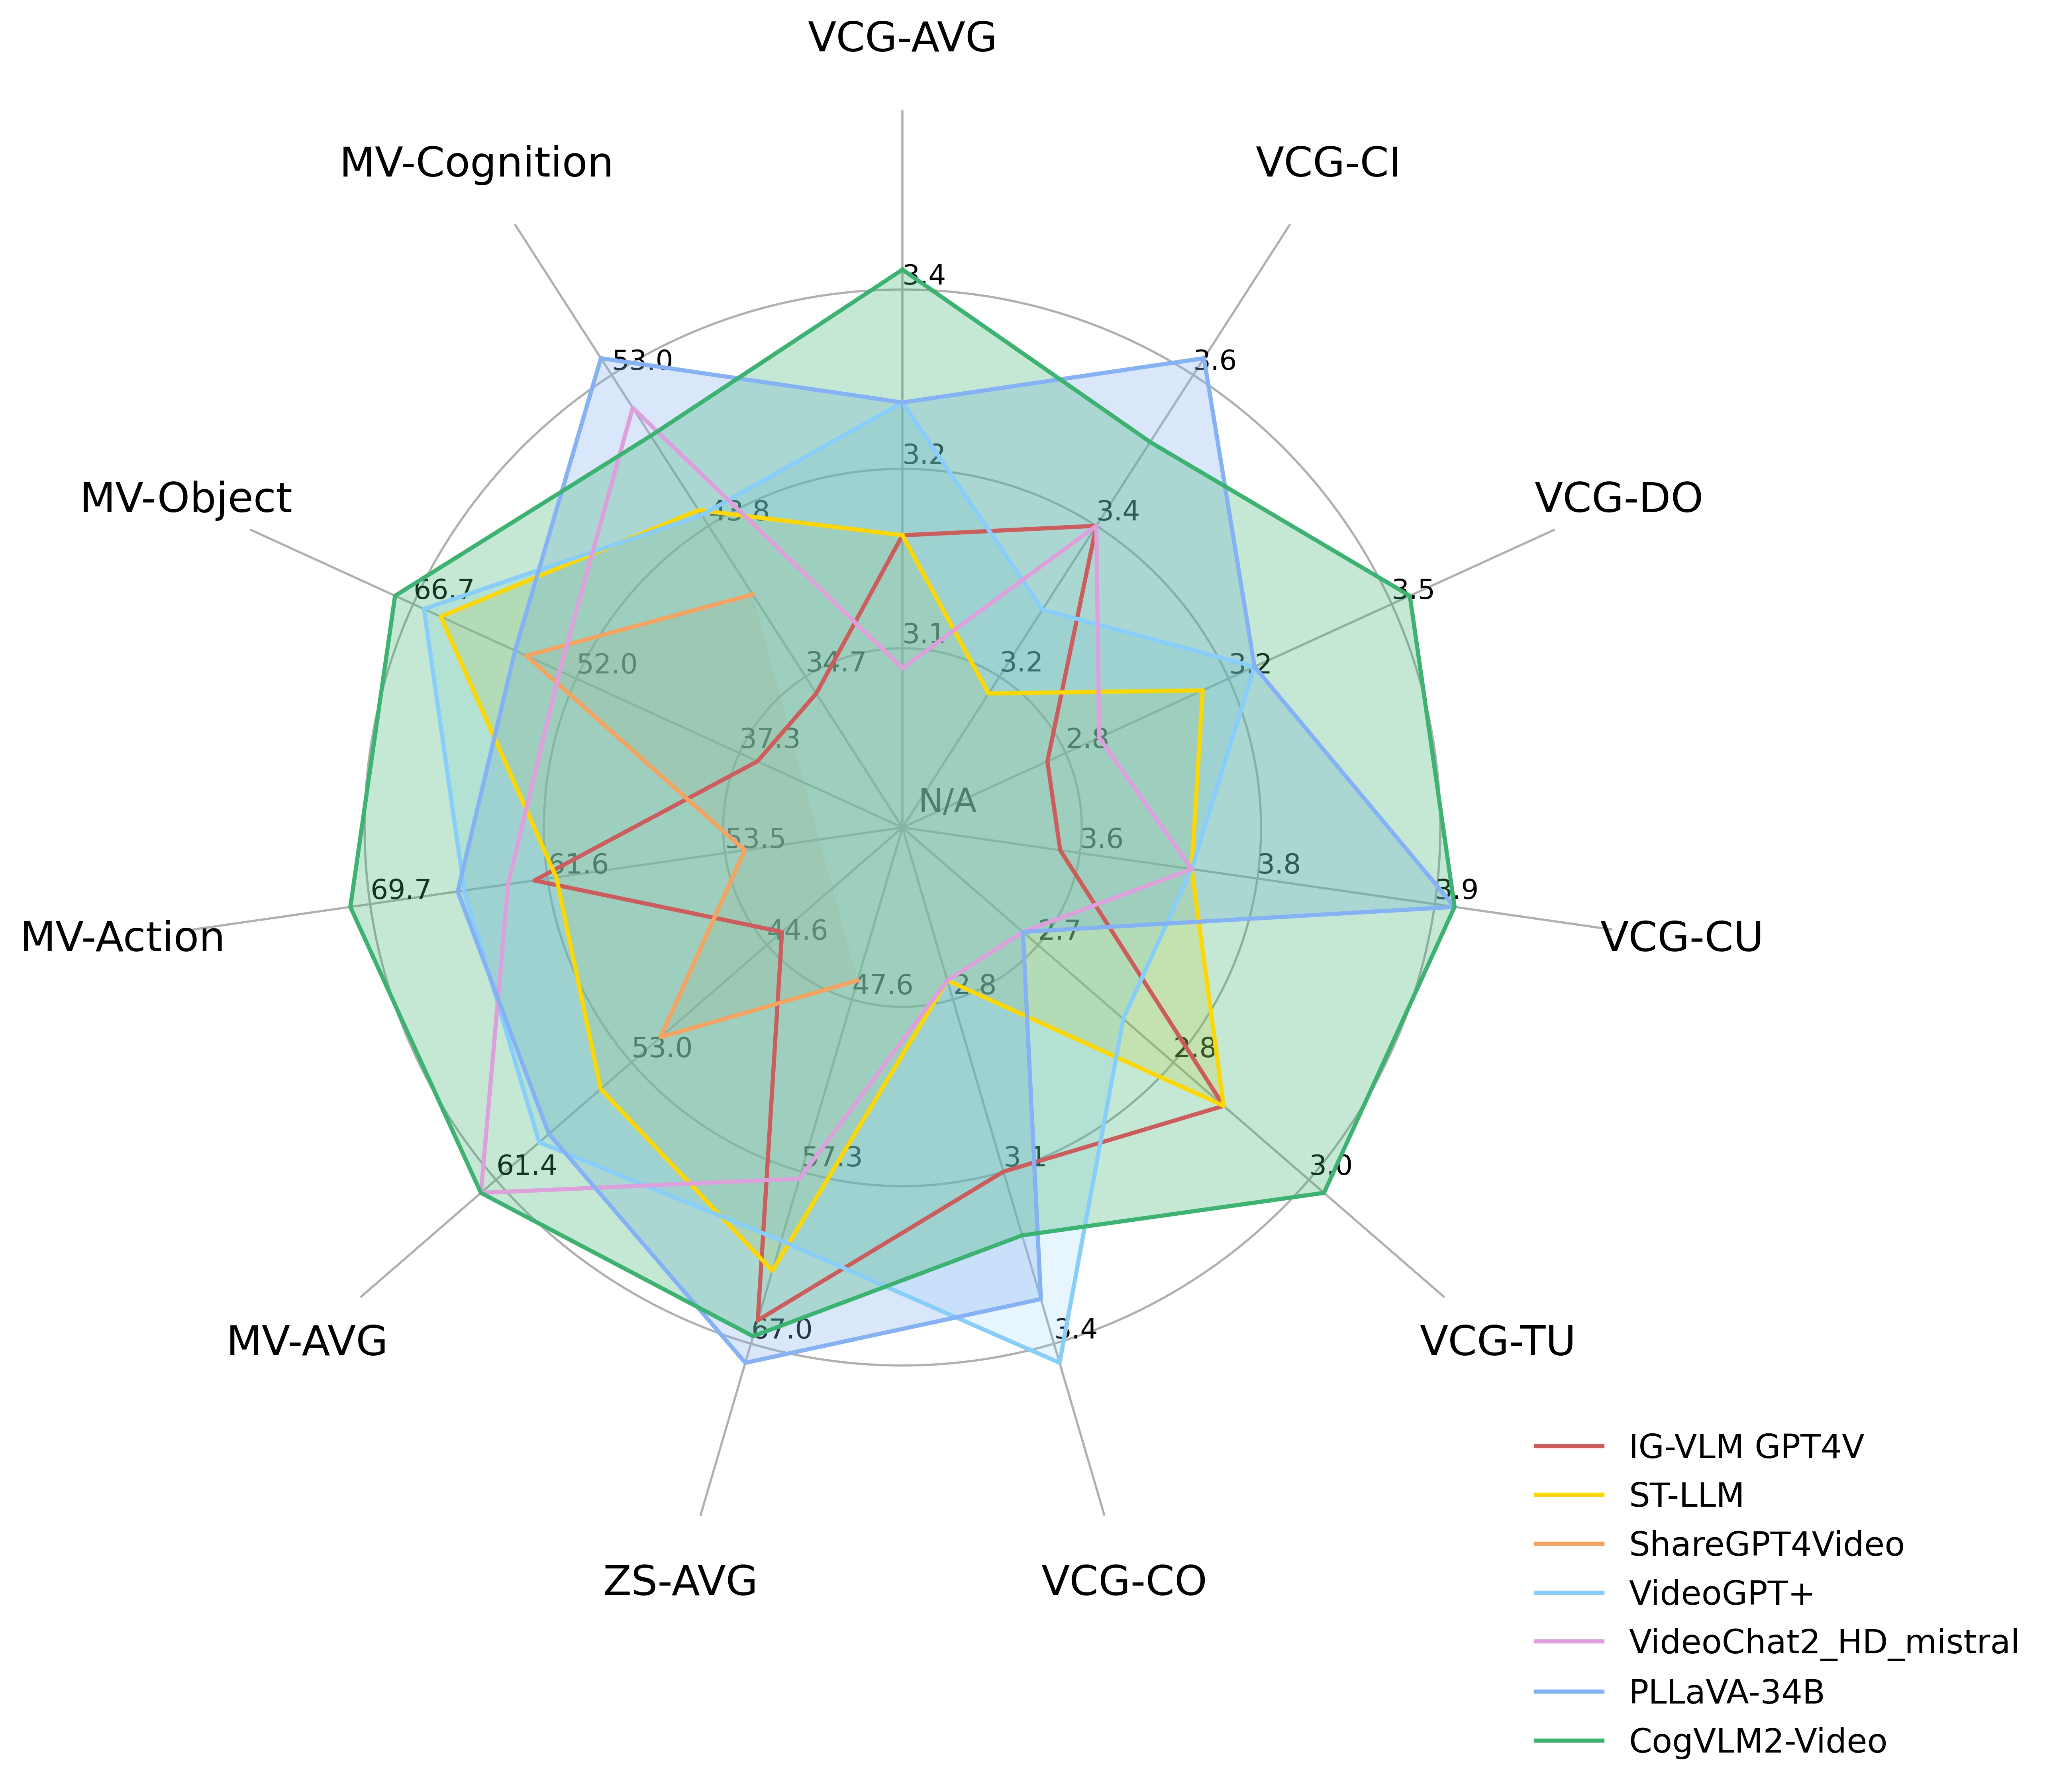
Performance on VideoChatGPT-Bench and Zero-shot VideoQA dataset:
Performance on MVBench dataset:
Evaluation details
We follow the previous works to evaluate the performance of our model. In different benchmarks, we craft task-specific prompts for each benchmark:
# For MVBench
prompt = f"Carefully watch the video and pay attention to the cause and sequence of events, the detail and movement of objects, and the action and pose of persons. Based on your observations, select the best option that accurately addresses the question.\n " + f"{prompt.replace('Short Answer.', '')}\n" + "Short Answer:"
# For VideoChatGPT-Bench
prompt = f"Carefully watch the video and pay attention to the cause and sequence of events, the detail and movement of objects, and the action and pose of persons. Based on your observations, comprehensively answer the following question. Your answer should be long and cover all the related aspects\n " + f"{prompt.replace('Short Answer.', '')}\n" + "Answer:"
# For Zero-shot VideoQA
prompt = f"The input consists of a sequence of key frames from a video. Answer the question comprehensively including all the possible verbs and nouns that can discribe the events, followed by significant events, characters, or objects that appear throughout the frames.\n " + f"{prompt.replace('Short Answer.', '')}\n" + "Answer:"
For evaluation codes, please refer to the evaluation script in PLLaVA.
Using This Model
This repository is a chat version model and it support single-round chat.
You can quickly install the Python package dependencies and run model inference in our github.
License
This model is released under the CogVLM2 LICENSE. For models built with Meta Llama 3, please also adhere to the LLAMA3_LICENSE.
Training details
Pleaser refer to our technical report for training formula and hyperparameters.