
KoreaPeter/ms-eff-gcvit-deepfake-b5-kodf
🚀 Multi Scale Efficient Global Context Vision Transformer


<img src="./mseffgcvit.JPG" width="900">
🔗 GitHub Repository: HanMoonSub/DeepGuard
🤗 Live demo: DeepFake Video Detection
🤗 Live demo: DeepFake Image Detection
🤗 Live demo: DeepFake Detection XAI
Multi-Scale Efficient Global Context Vision Transformer (MS-EffGCViT) is a hybrid CNN-ViT architecture for deepfake detection. It fuses CNN-driven spatial inductive bias with hierarchical global-context attention to catch both local artifacts (textures, blending seams) and global artifacts (lighting, structural inconsistency).
A single architecture ships in two sizes and three domain-tuned checkpoints, working on both static images and video at the frame level.
✨ Core Features
- 🎞️ Frame-level — one model handles both images and videos (frame-level inference + aggregation).
- 🌍 Cross-domain — robust on both East-Asian (KoDF) and Western (Celeb-DF-v2, FaceForensics++) faces.
- ⚡🔥 Two variants — Fast (b0) for real-time/edge, Pro (b5) for enterprise accuracy.
- 🧩 timm-compatible — load via the
timminterface or thedeepguardpackage.
⚙️ Model Specifications
🧬 Model Zoo
⚡ ms_eff_gcvit_b0 is Optimized for real-time inference and mobile deployment.
🔥 ms_eff_gcvit_b5 is Engineered for high-fidelity analysis and enterprise-grade accuracy.
📚 Dataset: KoDF (Korean Deepfake Dataset)
Large-scale Korean deepfake dataset provided by AI-Hub in 2020
featuring 400 Korean participants across 6 deepfake synthesis methods
- [x] Number of Subjects: 400 participants
- [x] Videos per Subject: 150+ videos
- [x] Total Data Duration: 88.5 days
- [x] Deepfake Model Variants: 6 types(DeepFaceLab, FaceSwap, FSGAN, FOMM, 3DMM, Wav2Lip)
📈 Test Evaluation
Trained and tested on the same dataset.
📈 Cross-Dataset Evaluation (Trained on KoDF)
Generalization to unseen domains — trained on KoDF, evaluated on western-face datasets.
🚀 Model Usage
pip install deepguard
from transformers import pipeline
🖼️ Image Classification
clf = pipeline(
    "image-classification",
    model="KoreaPeter/ms-eff-gcvit-deepfake-b5-kodf",
    trust_remote_code=True,
)

# ── Basic Inference ───────────────────────────────────────────────
result = clf("face.jpg")
# [{'label': 'fake', 'score': 0.9712}, {'label': 'real', 'score': 0.0288}]

# ── Custom Parameters ─────────────────────────────────────────────
result = clf(
    "face.jpg",
    margin_ratio=0.2,      # Margin ratio around the detected face bbox (default: 0.2)
    conf_thres=0.5,        # Confidence threshold for YOLO face detection (default: 0.5)
    min_face_ratio=0.01,   # Minimum face-to-frame area ratio to process (default: 0.01)
    tta_hflip=0.0,         # Probability of horizontal flip for TTA (default: 0.0)
    top_k=1,               # Number of top labels to return (default: all)
)
# [{'label': 'fake', 'score': 0.9712}]
🎬 Video Classification
clf = pipeline(
    "video-classification",
    model="KoreaPeter/ms-eff-gcvit-deepfake-b5-kodf",
    trust_remote_code=True,
)

# ── Basic Inference ───────────────────────────────────────────────
result = clf("video.mp4")
# [{'label': 'fake', 'score': 0.9634}, {'label': 'real', 'score': 0.0366}]

# ── Custom Parameters ─────────────────────────────────────────────
result = clf(
    "video.mp4",
    num_frames=20,              # Number of frames to sample (default: 20)
    margin_ratio=0.2,           # Margin ratio around the detected face bbox (default: 0.2)
    conf_thres=0.5,             # Confidence threshold for YOLO face detection (default: 0.5)
    min_face_ratio=0.01,        # Minimum face-to-frame area ratio to process (default: 0.01)
    tta_hflip=0.0,              # Probability of horizontal flip for TTA (default: 0.0)
    agg_mode="conf",            # Aggregation mode: 'conf' | 'mean' | 'vote' (default: 'conf')
    return_frame_scores=True,   # Return per-frame scores (default: False)
)
# [{'label': 'fake', 'score': 0.9634},
#  {'label': 'real', 'score': 0.0366},
#  {'frame_scores': [0.97, 0.95, 0.98, ...], 'agg_mode': 'conf'}]
Deep Dive into Model
Part 1: CNN-based Patch Embedding for Spatial Inductive Bias
While traditional Vision Transformers (ViTs) utilize a Linear Projection for patch embedding, our proposed model adopts a CNN-based Patch Embedding module incorporating MBConvBlocks.
- Injecting Inductive Bias : Standard ViTs often suffer from a lack of inherent spatial inductive bias, typically necessitating massive datasets to learn fundamental visual structures from scratch. In contrast, our CNN-based module leverages overlapping receptive fields to facilitate information sharing between neighboring patches. By explicitly injecting this spatial bias into the architecture, the model achieves more stable and accelerated convergence during the training process.
Part 2: Long-Short Range Spatial Interaction
We utilizes two distinct types of self-attention to capture both long-range and short-range information across feature maps.
<img src="./window_attention.JPG" width="900">
- Local Window Attention: this model efficiently captures local textures and precise spatial details while maintaining linear computational complexity relative to the image size.
- Global Window Attention: Unlike Swin Transformer, this module utilizes global-queries that interact with local window keys and values. This allows each local region to incorporate global context, effectively capturing long-range dependencies and providing a comprehensive understanding of the entire spatial structure
Part 3: Computational Efficiency
- Efficient Backbone While both Xception and EfficientNet show great results on DeepFake benchmarks, EfficientNet is chosen for its superior computational efficiency. By utilizing MBconv (Inverted Residual Blocks) and depthwise convolutions, it achieves significantly lower FLOPS compared to Xception.
- Window-based Attention: Instead of applying self-attention on raw images, this model operates on feature maps extracted from backbone blocks. By partitioning these maps into windows, the $O(N^2)$ complexity is restricted to the window size, siginificantly lowering the computational footprint.
Part 4: Multi-Scale Feature Map Fusion
<img src="./dual_branch.gif" width="900">
Modern DeepFakes can leave very localized forgery region. To Capture this, we adopts a multi-scale strategy by extracting features from different levels of the backbone.
- 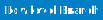 (_Subtle Artifacts_): High-Resolution feature maps are extracted from early backbone blocks(
l_block_idx) to capture like skin texture or boundary artifacts
- 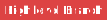 (_Global Features_): Low-Resolution feature maps are extracted from deeper blocks(
h_block_idx) to analyze overall lighting, shadows, and structural consistency.
- Feature Fusion: The Outputs from both branches (
L-GCViT and H-GCViT) are fused to make a comprehensive decision based on both local and global context.
🤝 Citation
@misc{deepguard2026,
  title  = {DeepGuard: Multi-Scale Efficient Global Context Vision Transformer for Deepfake Detection},
  author = {seoyunje},
  year   = {2026},
  url    = {https://github.com/HanMoonSub/DeepGuard}
}