
Genentech/assayllm-sft
AssayLLM-SFT
Website | Checkpoints | Paper | 
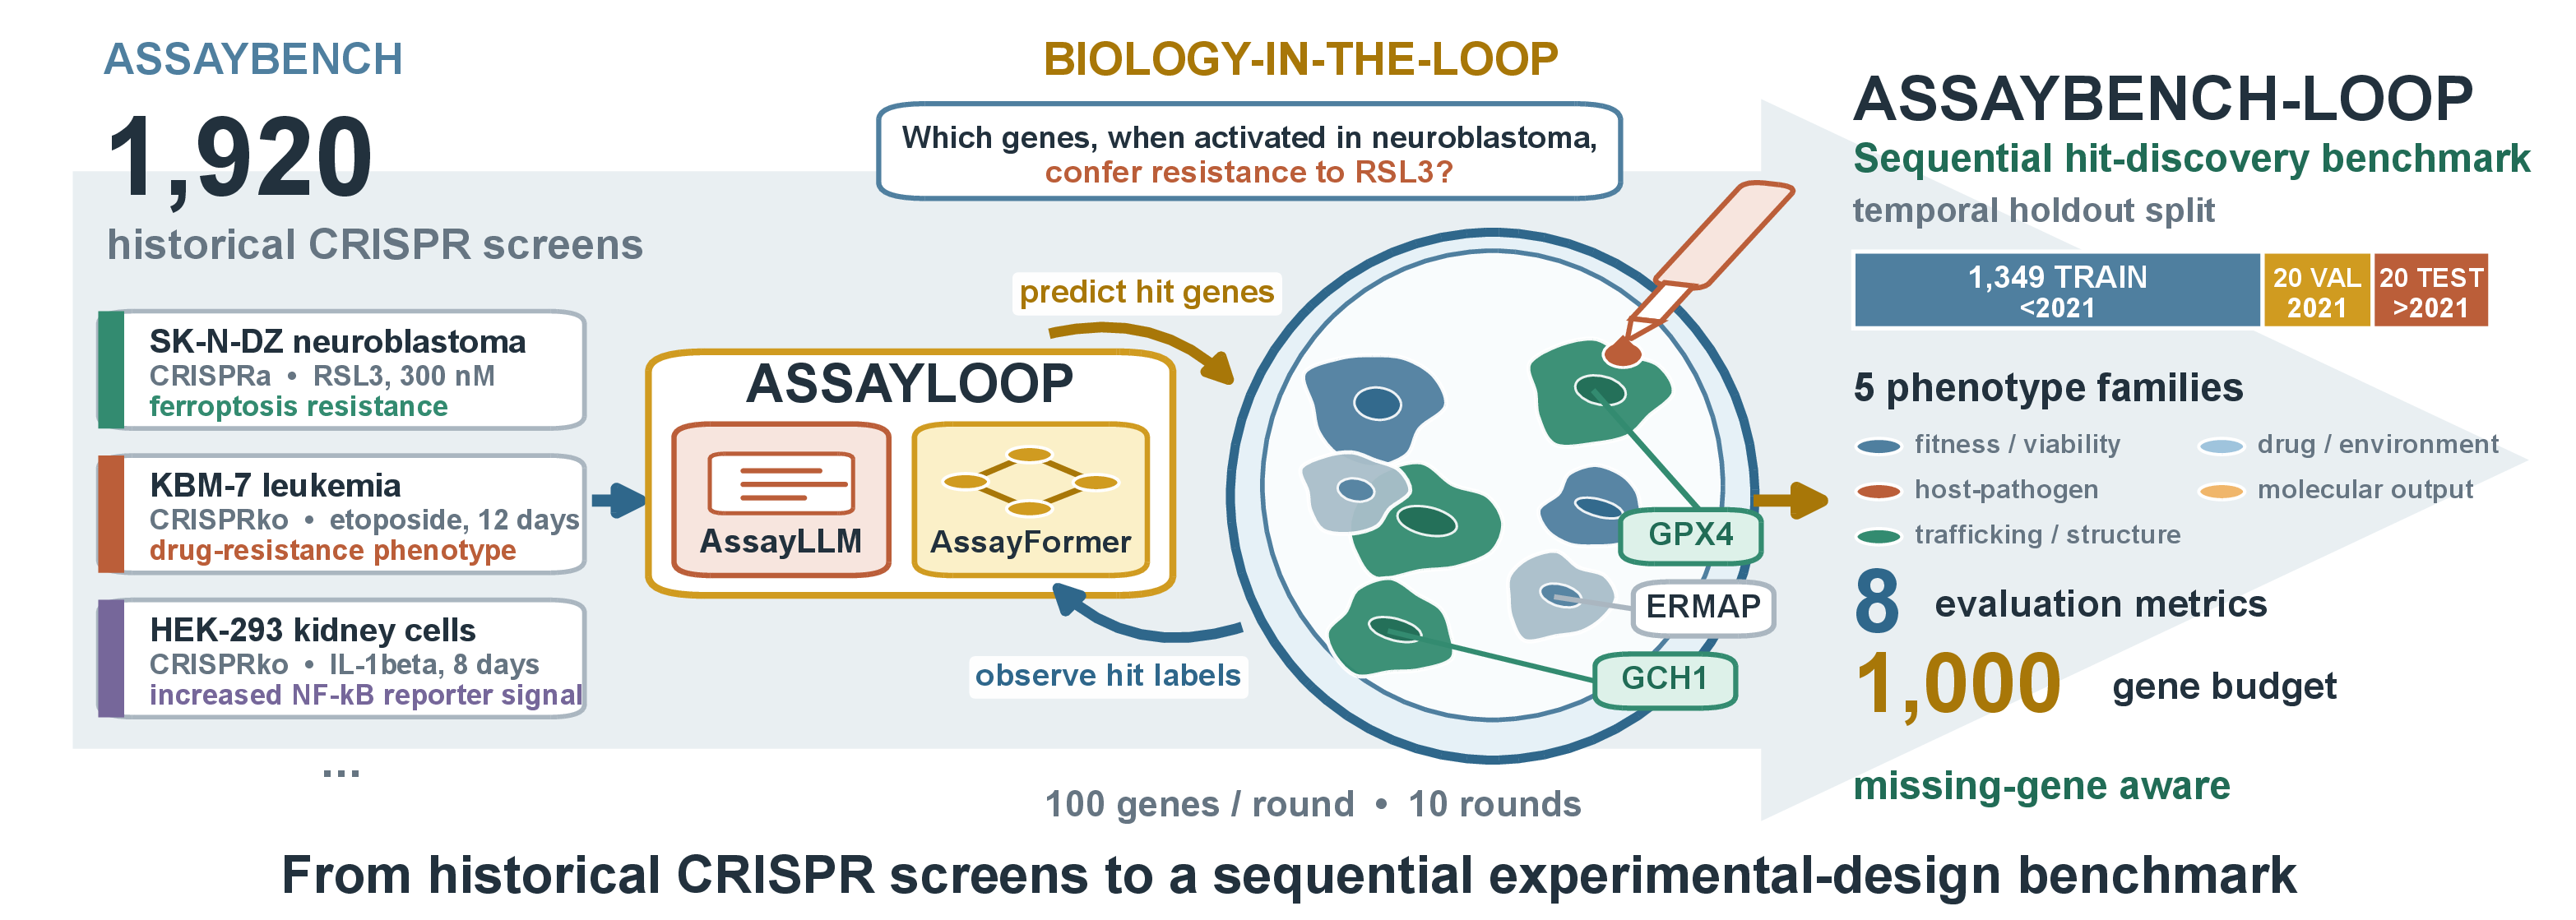
Qwen3.6-27B supervised-fine-tuned to pick the next hundred genes to assay in a CRISPR screen. Given a screen description and everything assayed so far, it returns a ranked list of 100 HGNC gene symbols.
Usage
vllm serve Genentech/assayllm-sft --served-model-name assayllm-sft \
    --reasoning-parser qwen3 --port 8061 --api-key token-abc123
Within the AssayLoop harness:
Copy configs/lm/collect-qwen3.6-27b.yaml to configs/lm/collect-assayllm-sft.yaml, point lm.model at assayllm-sft and lm.api_base at that port, then:
uv run assayloop run --model null --acq llm_single --screen-set public --full-genome \
    --lm-config configs/lm/collect-assayllm-sft.yaml
Without the harness:
from transformers import AutoModelForCausalLM, AutoTokenizer

tok = AutoTokenizer.from_pretrained("Genentech/assayllm-sft")
model = AutoModelForCausalLM.from_pretrained(
    "Genentech/assayllm-sft", dtype="bfloat16", device_map="auto")

prompt = """## Goal

You are tasked with ranking genes from a genetic perturbation screen. Based on the
experimental context and hit criteria provided below, provide a list of exactly 100 genes
that are hits in this screen, ranked from strongest to weakest.

## Experimental Context

This screen was performed in HeLa cells. Researchers used a genome-wide library
(CRISPR knockout) to systematically perturb gene function.

## Screen Objective

The primary objective of this screen was to identify a set of hit genes, each of which is
required for RelA nuclear translocation upon TNF-alpha stimulation.

## Required Output Format

Provide your response as an ordered list of exactly 100 HGNC gene symbols (standard
nomenclature for Homo sapiens).

Format:
GENE1, GENE2, GENE3, ..., GENE100
"""

chat = tok.apply_chat_template([{"role": "user", "content": prompt}],
                               add_generation_prompt=True, tokenize=False)
enc = tok(chat, return_tensors="pt").to(model.device)
out = model.generate(**enc, max_new_tokens=4096,
                     do_sample=True, temperature=1.0, top_p=0.95, top_k=20)
print(tok.decode(out[0][enc["input_ids"].shape[-1]:], skip_special_tokens=True))
Scoring an output
pip install assaybench scores a ranking against a screen's ground truth. It carries the screens and the candidate pool as well as the metrics, so nothing else is needed, and no GPU:
from assaybench import enrichment_factor, gene_universe, load_screens

screens = load_screens("assayloop-test")      # the paper's 20-screen test set
universe = gene_universe(screens)             # the f2 pool, 21,147 genes

screen = screens[0]
hits = [g for g, h in zip(screen.genes, screen.hits) if h]
picked = [...]                                # the symbols this model named, in order

enrichment_factor(picked, screen.genes, hits, universe=universe, budget=1000)
Pass universe=. It says which names outside this screen's library are still real genes: those picks are forgiven and leave the effective budget, everything else is charged as a miss. Omit it and every out-of-library name is forgiven, hallucinations included, which can only shrink the denominator, so the EF you get back sits at or above the number in the table below.
Loading
# text-only
from transformers import AutoModelForCausalLM
model = AutoModelForCausalLM.from_pretrained(REPO, dtype="bfloat16", device_map="auto")
Results
Results are evaluated on AssayBench-Loop.
Citation
@article{edwards2026biologyloop,
  title={Biology-in-the-loop: Amortized Adaptive Hit Discovery in CRISPR Screens},
  author={Edwards, Carl and De Brouwer, Edward and Li, Xiner and Lee, Namkyeong and
          Hajiramezanali, Ehsan and Biton, Anne and Mostafavi, Sara and Scalia, Gabriele},
  journal={arXiv preprint arXiv:2609.11877},
  url={https://arxiv.org/abs/2609.11877},
  year={2026}
}