
Atotti/miipher-2-HuBERT-HiFi-GAN-v0.1
Speech Enhancement Model
このモデルは日本語と英語で小規模に学習された音声復元モデルです。 SSLモデルとしてmHuBERT-147を用い、VocoderとしてHiFi-GANを用いました。 HiFi-GANに関してはssl-vocoderの実装を使って学習しました。
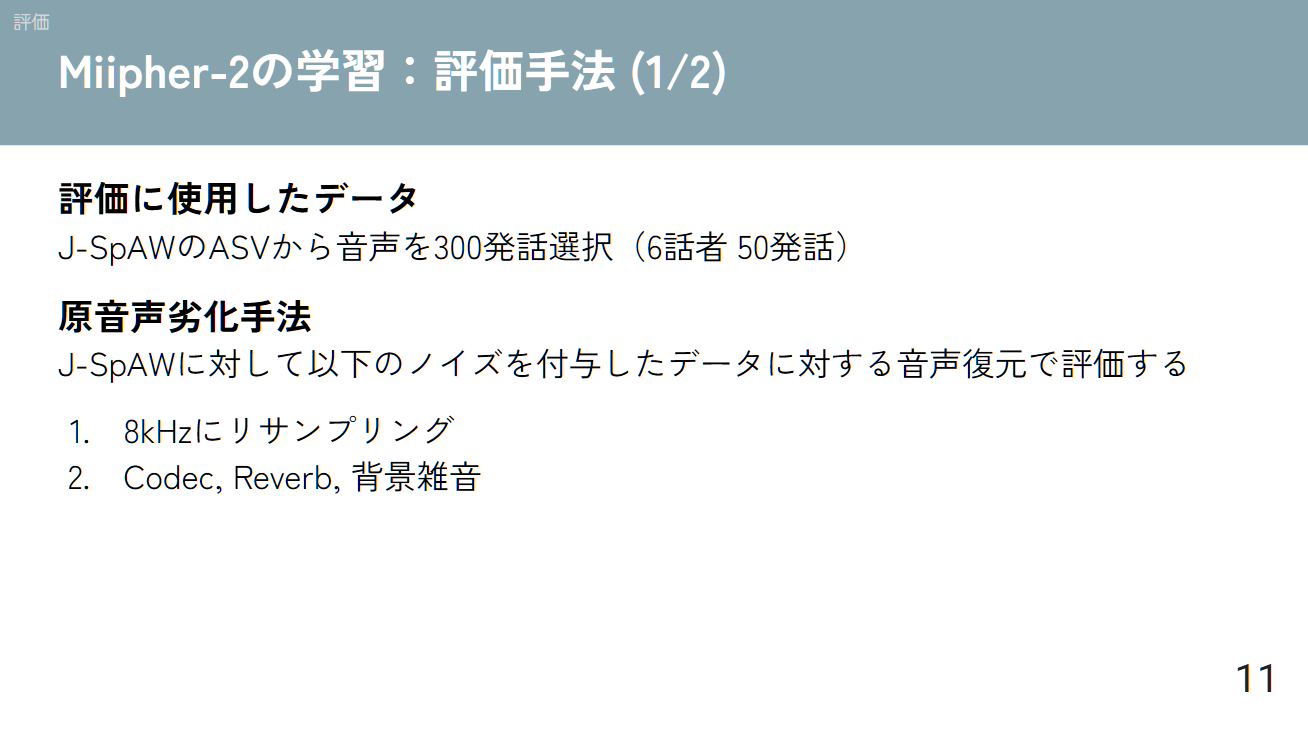
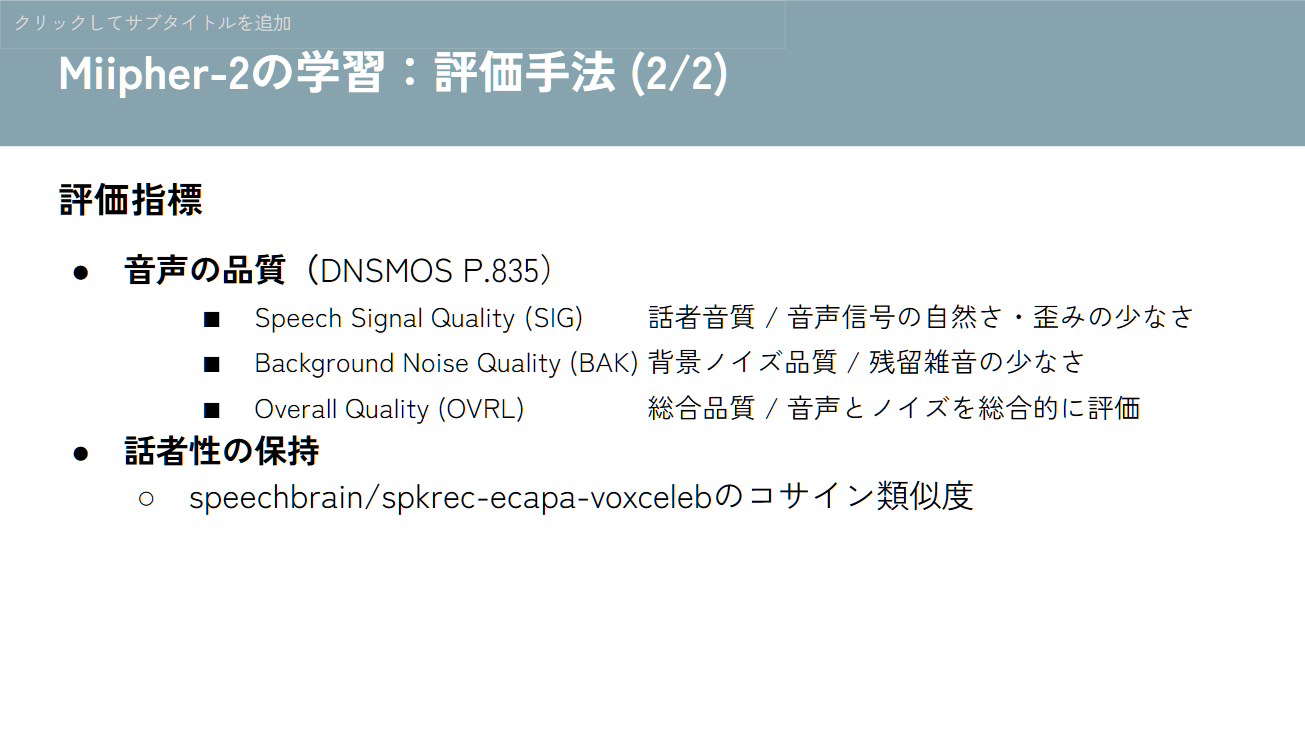
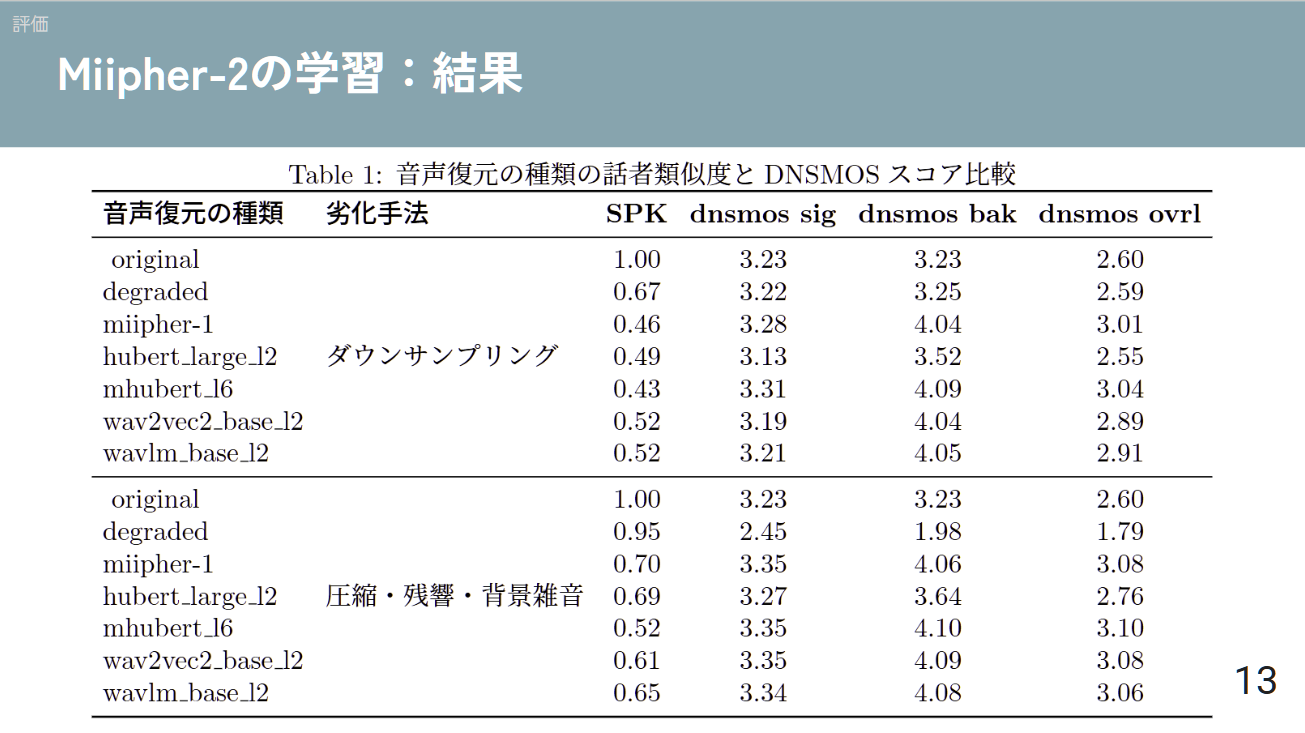
[!Note] このモデルはMiipher-2の再現を目指して実装されましたが、学習の規模も使用している事前学習済みモデルも大きく異なります。 ノイズの除去は上手く動きますが、話者性がやや変動するモデルとなっています。 また、計算資源の都合で学習も十分に行えていません。 Miipher-1の再現実装であるWataru-Nakata/miipherとの比較評価結果を載せているので参考にしてください。
<!-- 2‑column comparison table --> <table style="width:100%; text-align:center;"> <thead> <tr> <th style="padding:0.5rem 0;">degraded</th> <th style="padding:0.5rem 0;">enhanced</th> </tr> </thead>
<tbody> <!-- Spectrogram row --> <tr> <td style="padding:0.5rem 1rem;"> <img src="https://cdn-uploads.huggingface.co/production/uploads/64a0f51eddcdc3438ed10a7d/Vi-S6--fnsEh4FyM23UNv.png" alt="スペクトログラム (degraded)" style="width:100%; max-width:320px;"
</td> <td style="padding:0.5rem 1rem;"> <img src="https://cdn-uploads.huggingface.co/production/uploads/64a0f51eddcdc3438ed10a7d/AC1_h5ur8dnayBC8yahpM.png" alt="スペクトログラム (enhanced)" style="width:100%; max-width:320px;"
</td> </tr> <tr> <td style="padding:1rem 1rem 0.5rem;"> <audio controls style="width:100%; max-width:240px;"> <source src="https://huggingface.co/Atotti/miipher-2-HuBERT-HiFi-GAN-v0.1/resolve/main/sample.wav" type="audio/wav"> Your browser does not support the audio element. </audio> </td> <td style="padding:1rem 1rem 0.5rem;"> <audio controls style="width:100%; max-width:240px;"> <source src="https://huggingface.co/Atotti/miipher-2-HuBERT-HiFi-GAN-v0.1/resolve/main/miipher2hubertbase_l6.wav" type="audio/wav"> Your browser does not support the audio element. </audio> </td> </tr> </tbody> </table>
Model Components
1. Parallel Adapter
- Architecture: Lightweight feedforward network inserted into mHuBERT-147
- Target Layer: Layer 6
- Hidden Dimension: 768
2. Lightning SSL-Vocoder
- Architecture: HiFi-GAN based vocoder with PyTorch Lightning
- Input: SSL features from enhanced mHuBERT
- Output: High-quality audio at 22050Hz
Model Performance
- Target: Speech enhancement from noisy/degraded audio
- Training Data: JVS & LibriTTS-R
Usage
学習および推論コードは以下のリポジトリにあります。
https://github.com/Atotti/miipher-2
HugginFace Spaces上にデモを用意しました。Web上から使えます。
https://huggingface.co/spaces/Atotti/miipher-2-HuBERT-HiFi-GAN-v0.1
License
Apache-2.0