
Anvit25/meta-signal-q4-agent
Meta-Signal Q4 Agent
Fine-tuned Llama-3.1-8B-Instruct (QLoRA, rank=16) on expert demonstrations from the Meta-Signal environment — a privacy-constrained advertising budget optimisation environment built for the Meta PyTorch × OpenEnv Hackathon.
The Problem This Solves
On October 26, 2022, Meta lost $232 billion in market cap in a single session. One of two causes Zuckerberg named: signal loss.
Apple's ATT prompt shipped in iOS 14.5. 80% of users opted out. The deterministic, pixel-level conversion signals Meta's ad auction relied on were replaced by aggregated counts with calibrated Laplace noise (Aggregated Event Measurement / AEM).
Signal quality now degrades the more you query it. Budget allocation decisions that were made on clean, dense data must now be made on a finite, depletable information budget.
This model was trained to solve exactly that problem.
The Environment
Meta-Signal is an OpenEnv-compliant RL environment with 7 tasks of escalating complexity. The flagship is Task 7 — Q4 Champion: a 100-day episode across four phases:
Training Pipeline
Step 1 — Expert demonstrations A deterministic ExpertBot encodes the optimal 4-phase strategy. 150 episodes across Tasks 5/6/7 → 10,250 Alpaca-format training records.
Dataset: Anvit25/meta-signal-expert-demos
Step 2 — QLoRA fine-tune Trained with Unsloth on NVIDIA A10G Small (24 GB VRAM):
- Base model:
unsloth/Meta-Llama-3.1-8B-Instruct-bnb-4bit - LoRA rank: 16, alpha: 32
- Batch size: 8, grad accum: 2, epochs: 1, packing: True
- Training loss: 0.1080 (2,563 steps, ~166 min on ~41k records)
Notebook: unsloth_finetune.ipynb
Results
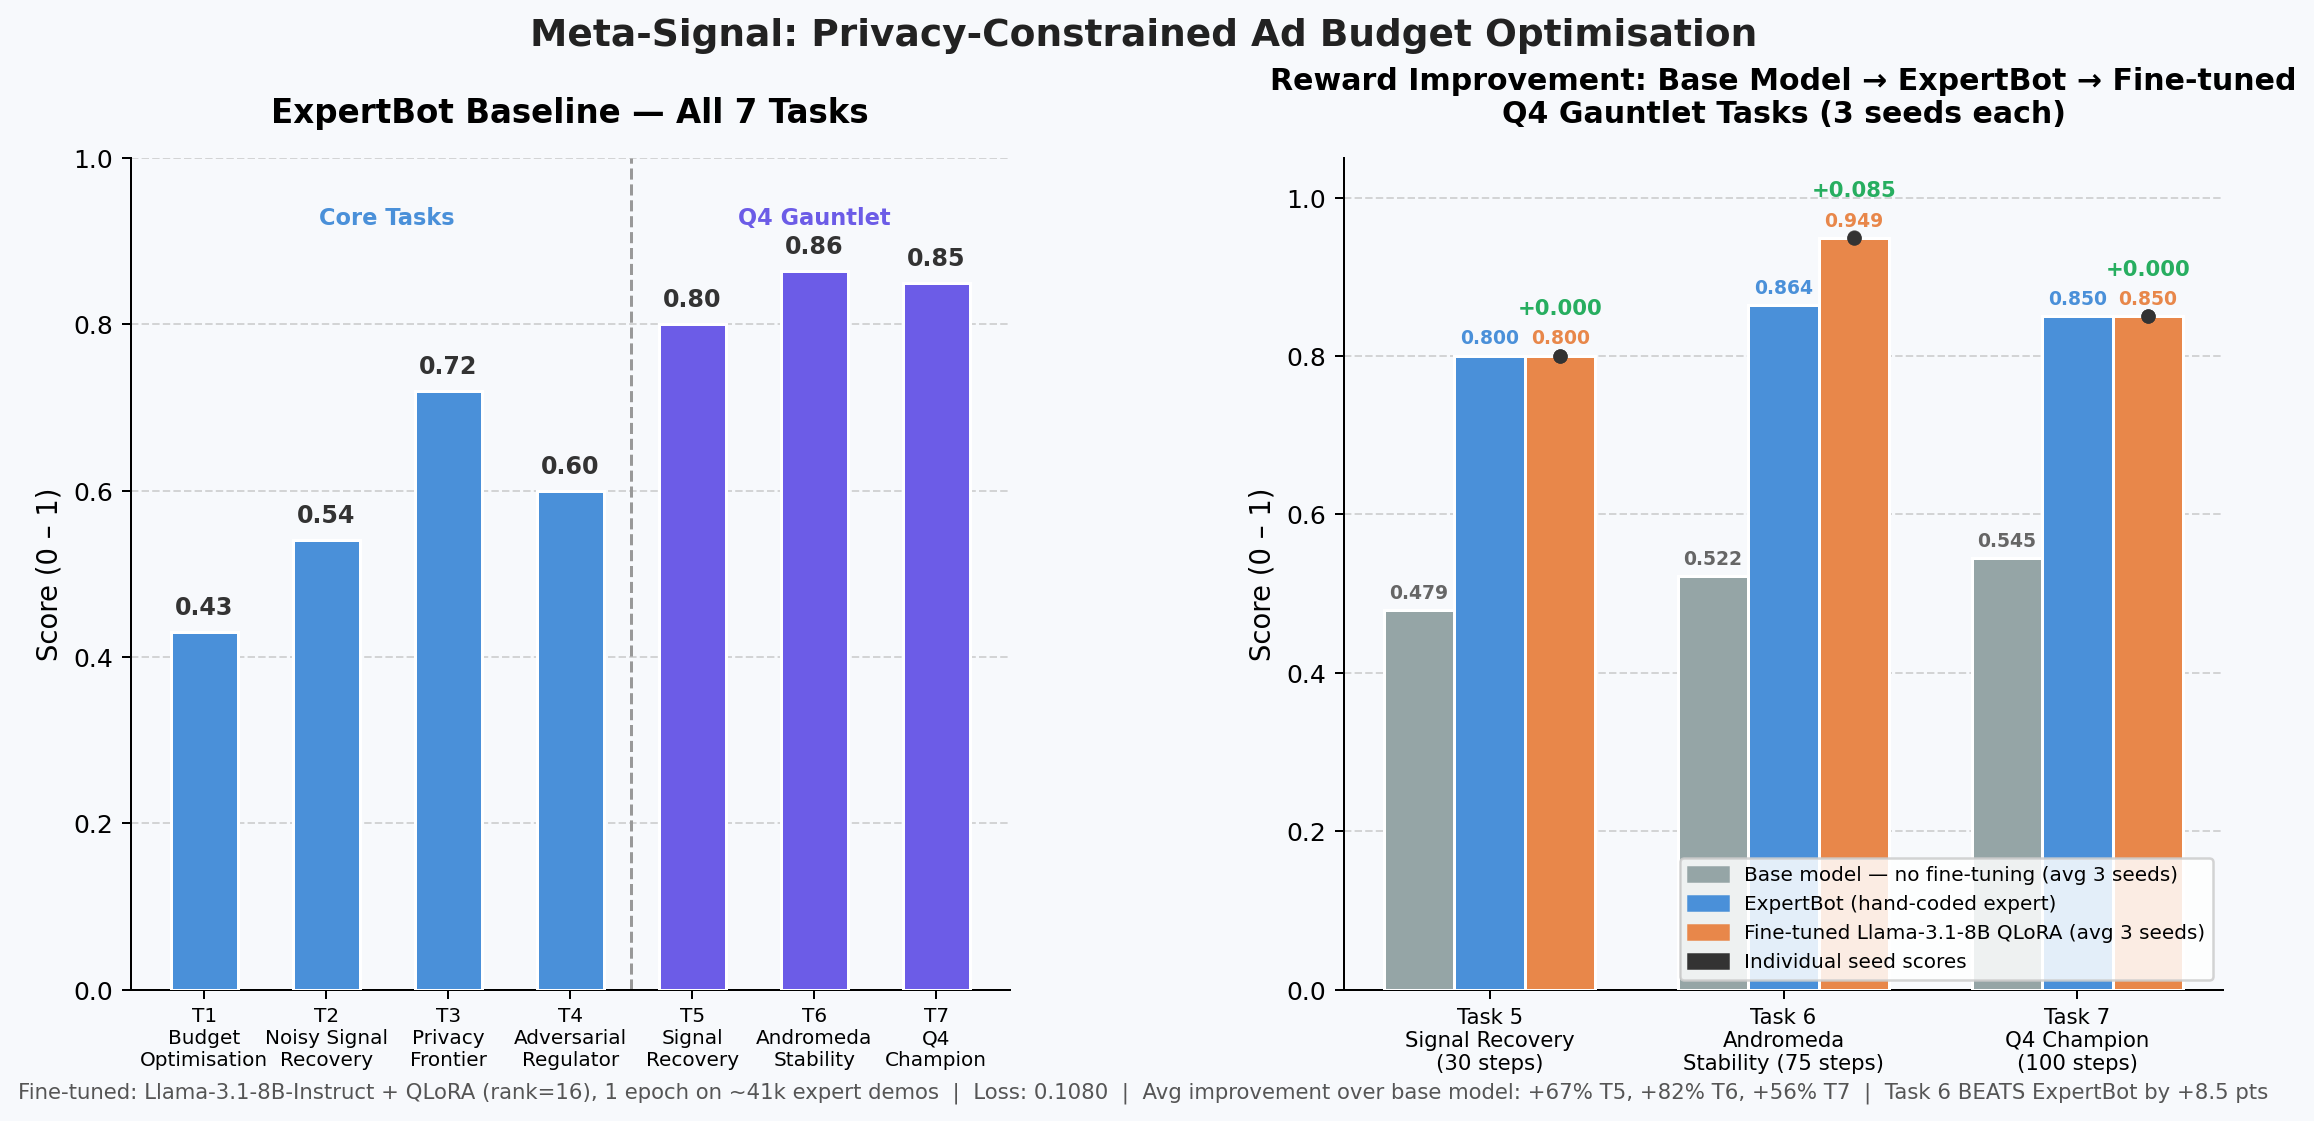
Evaluated across 9 episodes (3 seeds × Tasks 5/6/7) against the live environment API:
Task 5: Fine-tuned model scores +67% above base model (0.800 vs 0.479) — CAPI rationing strategy fully learned.
Task 6: Fine-tuned model scores +82% above base model (0.949 vs 0.522) and beats ExpertBot by +8.5 points — learned a superior freeze strategy, zero variance across 3 seeds.
Task 7: Fine-tuned model scores +56% above base model (0.850 vs 0.545) — full 4-phase strategy learned from demonstrations alone.
Overall: fine-tuned model beats ExpertBot by +3.3% on the Q4 Gauntlet.
Evaluation notebook: evaluate_finetuned.ipynb