
AlekseyCalvin/QWEN_IMAGE_fp4_w_AbliteratedTE_Diffusers
<p align="center"> <img src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Image/qwenimagelogo.png" width="200"/> <p>
QWEN-IMAGE Model |fp4|+Abliterated Qwen2.5VL-7b
This repo contains a variant of QWEN's [QWEN-IMAGE](https://huggingface.co/Qwen/Qwen-Image), the state-of-the-art generative model with extensive and (image/)text-to-image &/or instruction/control-editing capabilities. <br>
To make these cutting edge capabilities more accessible to those constrained to low-end consumer-grade hardware, we've quantized the DiT (Diffusion Transformer) component of Qwen-Image to the 4-bit FP4 format using the Bits&Bytes toolkit.<br> This optimization was derived by us directly from the BF16 base model weights released on 08/04/2025, with no other mix-ins or modifications to the DiT component. <br> NOTE: Install `bitsandbytes` prior to inference. <br>
QWEN-IMAGE is an open-weights customization-friendly frontier model released under the highly permissive Apache 2.0 license, welcoming unrestricted (within legal limits) commercial, experimental, artistic, academic, and other uses &/or modifications. <br>
To help highlight horizons of possibility broadened by the QWEN-IMAGE release, our quantization is bundled with an "Abliterated" (aka de-censored) finetune of Qwen2.5-VL 7B Instruct, QWEN-IMAGE model's sole conditioning encoder (of prompts, instructions, input images, controls, etc), as well as a powerful Vision-Language-Model in its own right. <br>
As such, our repo saddles a lean & prim FP4 DiT over the [Qwen2.5-VL-7B-Abliterated-Caption-it](https://huggingface.co/prithivMLmods/Qwen2.5-VL-7B-Abliterated-Caption-it/tree/main) by Prithiv Sakthi (aka prithivMLmods). <p align="center"> <img src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Image/merge3.jpg" width="1600"/> <p>
NOTICE:
Do not be alarmed by the file warning from the ClamAV automated checker. <br> It is a clear false positive. In assessing one of the typical Diffusers-adapted Safetensors shards (model weights), the checker reads: `The following viruses have been found: Pickle.Malware.SysAccess.sys.STACK_GLOBAL.UNOFFICIAL` <br> However, a Safetensors by its sheer design can not contain suchlike inserts. You may confirm for yourself thru HF's built-in weight/index viewer. <br> So, to be sure, this repo does not contain any pickle checkpoints, or any other pickled data. <br>
TEXT-TO-IMAGE PIPELINE EXAMPLE:
This repo is formatted for usage with Diffusers (0.35.0.dev0+) & Transformers libraries, vis-a-vis associated pipelines & model component classes, such as the defaults listed in model_index.json (in this repo's root folder). <br> Sourced/adapted from [the original base model repo](https://huggingface.co/Qwen/Qwen-Image) by QWEN. EDIT: We've confronted some issues with using the below pipeline. Will update once a reliable replacement is confirmed. <br>
from diffusers import DiffusionPipeline
import torch
import bitsandbytes
model_name = "AlekseyCalvin/QwenImage_fp4_diffusers"
# Load the pipeline
if torch.cuda.is_available():
    torch_dtype = torch.bfloat16
    device = "cuda"
else:
    torch_dtype = torch.float32
    device = "cpu"
pipe = DiffusionPipeline.from_pretrained(model_name, torch_dtype=torch_dtype)
pipe = pipe.to(device)
positive_magic = [
    "en": "Ultra HD, 4K, cinematic composition." # for english prompt,
    "zh": "超清,4K,电影级构图" # for chinese prompt,
]
# Generate image
prompt = '''A coffee shop entrance features a chalkboard sign reading "Qwen Coffee 😊 $2 per cup," with a neon light beside it displaying "通义千问". Next to it hangs a poster showing a beautiful Chinese woman, and beneath the poster is written "π≈3.1415926-53589793-23846264-33832795-02384197". Ultra HD, 4K, cinematic composition'''
negative_prompt = " "
# Generate with different aspect ratios
aspect_ratios = {
    "1:1": (1328, 1328),
    "16:9": (1664, 928),
    "9:16": (928, 1664),
    "4:3": (1472, 1140),
    "3:4": (1140, 1472)
}
width, height = aspect_ratios["16:9"]
image = pipe(
    prompt=prompt + positive_magic["en"],
    negative_prompt=negative_prompt,
    width=width,
    height=height,
    num_inference_steps=50,
    true_cfg_scale=4.0,
    generator=torch.Generator(device="cuda").manual_seed(42)
).images[0]
image.save("example.png")
<br>
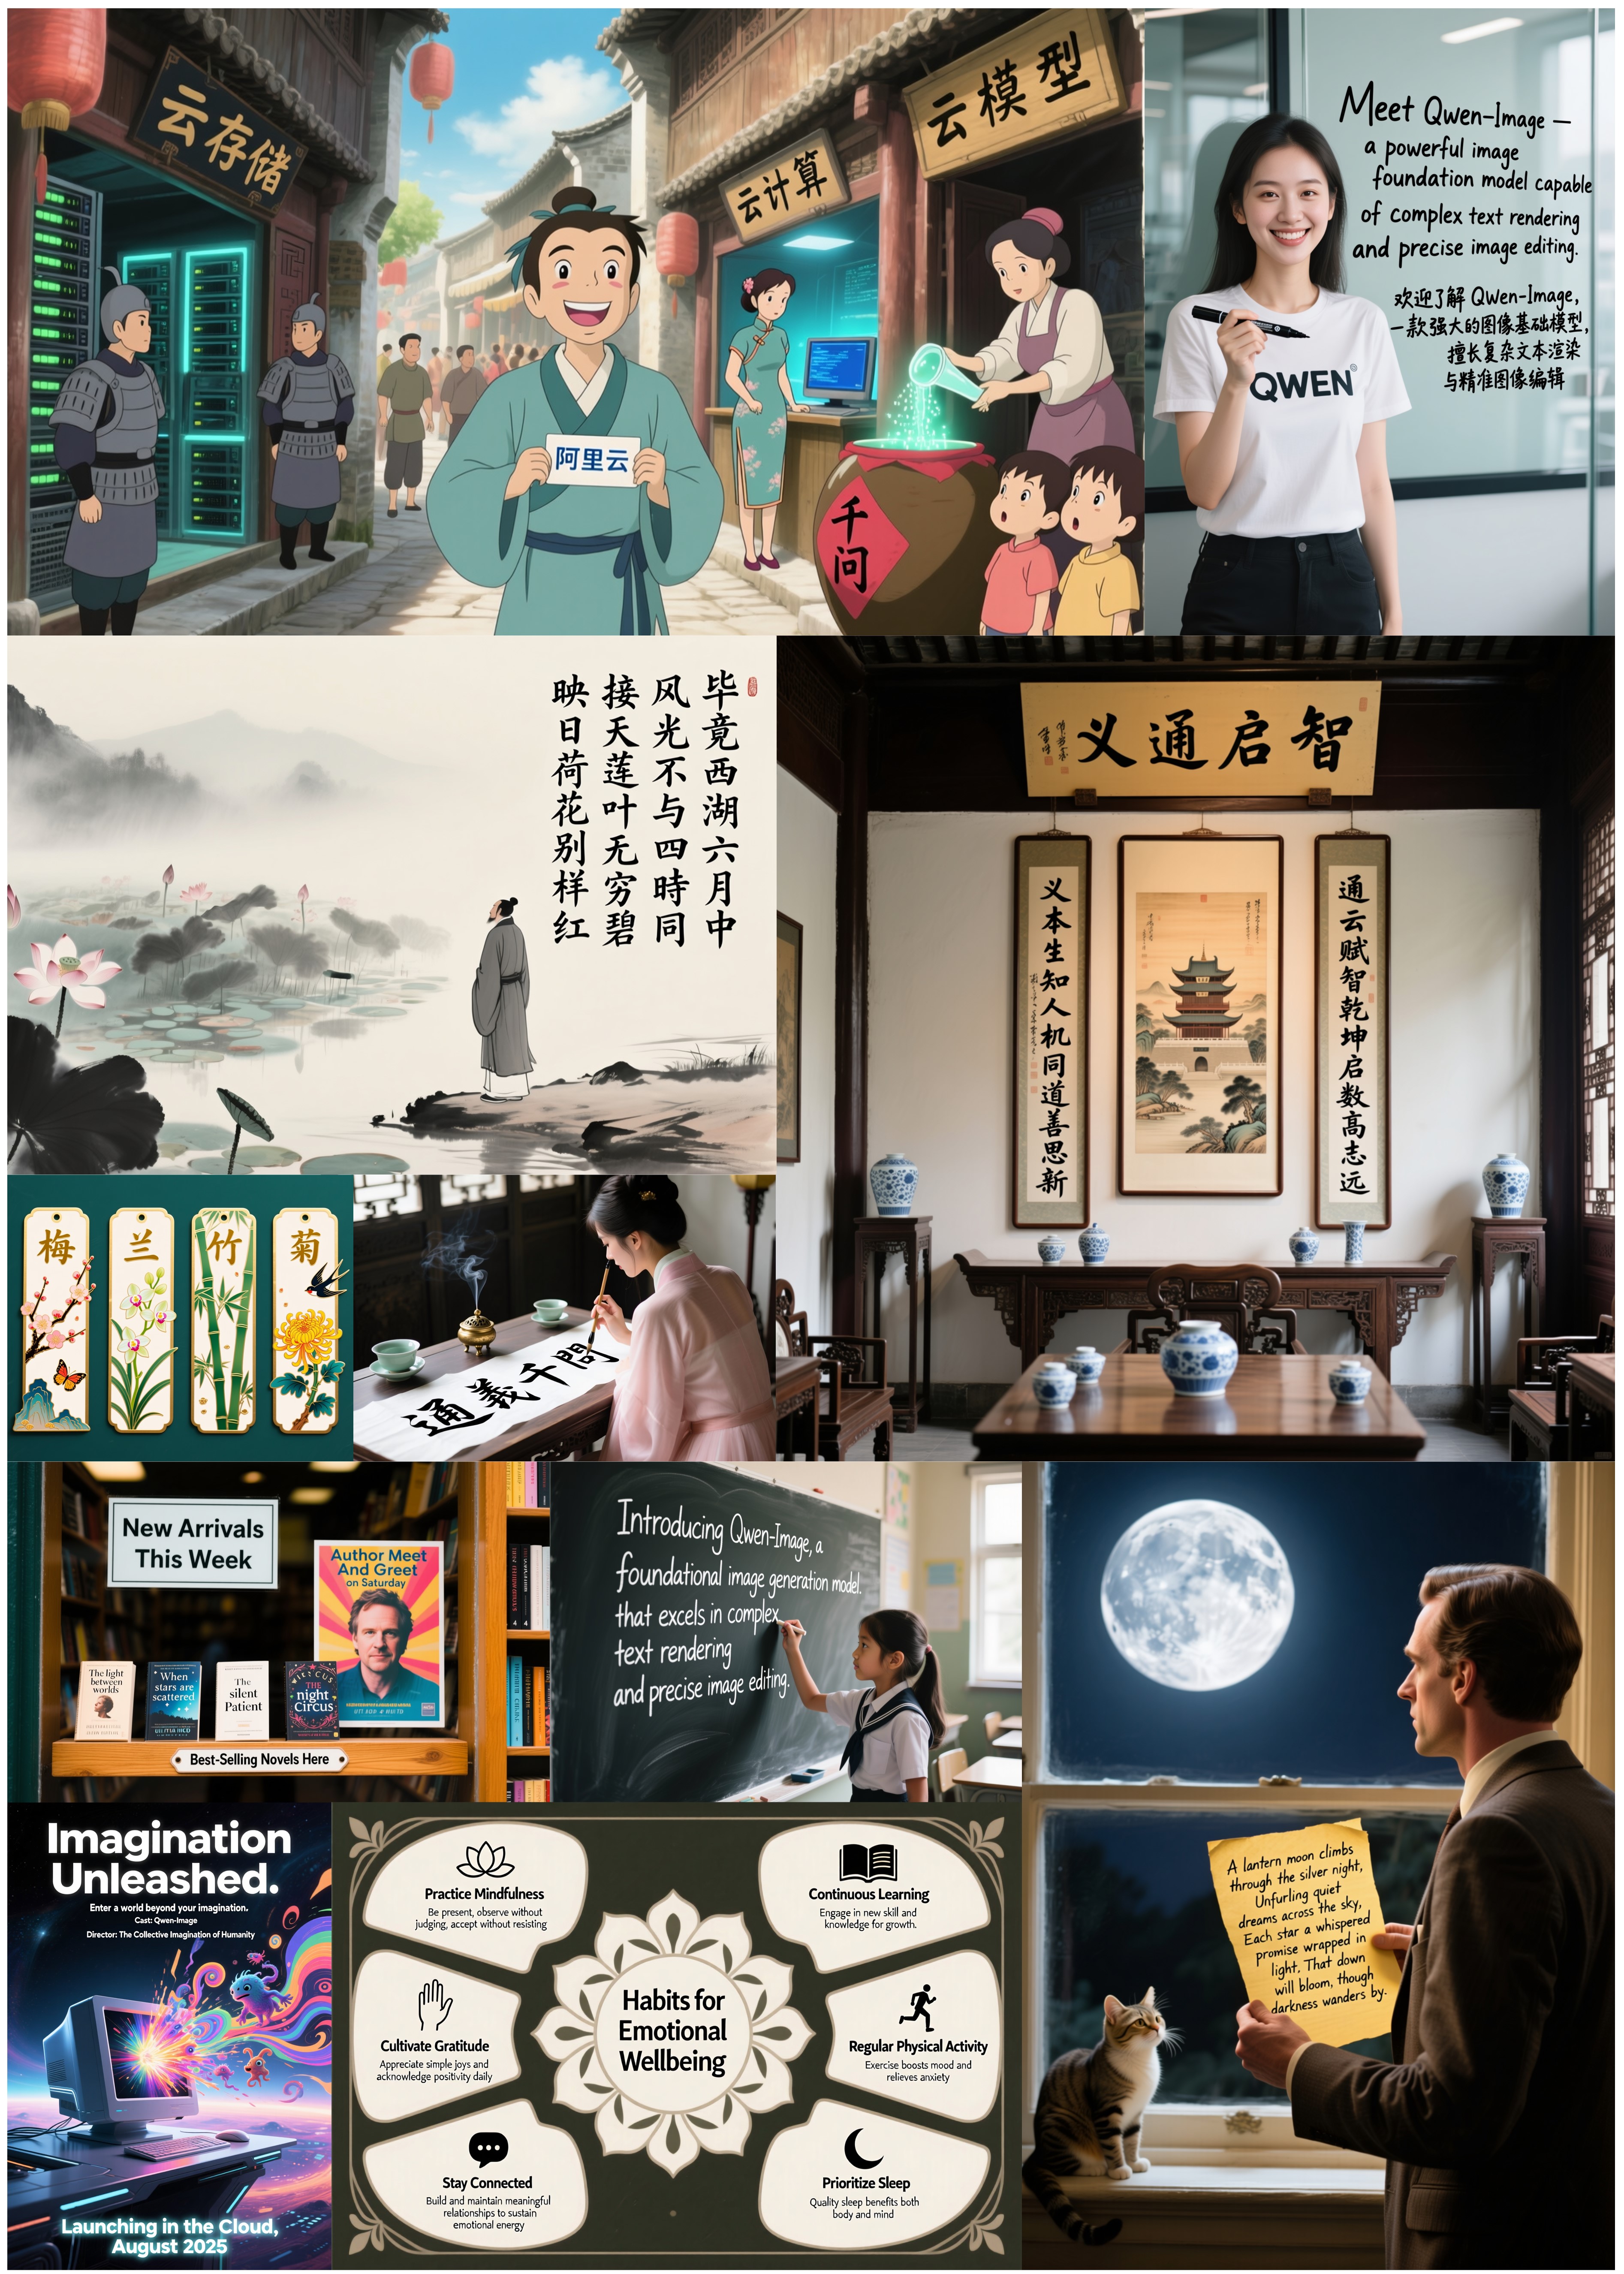
SHOWCASES FROM THE QWEN TEAM:


MORE INFO:
- Check out the Technical Report for QWEN-IMAGE, released by the Qwen team! <br>
- Find source base model weights here at huggingface and at Modelscope.
QWEN LINKS:
<p align="center"> 💜 <a href="https://chat.qwen.ai/"><b>Qwen Chat</b></a>   |   🤗 <a href="https://huggingface.co/Qwen/Qwen-Image">Hugging Face</a>   |   🤖 <a href="https://modelscope.cn/models/Qwen/Qwen-Image">ModelScope</a>   |    📑 <a href="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Image/Qwen_Image.pdf">Tech Report</a>    |    📑 <a href="https://qwenlm.github.io/blog/qwen-image/">Blog</a>    <br> 🖥️ <a href="https://huggingface.co/spaces/Qwen/qwen-image">Demo</a>   |   💬 <a href="https://github.com/QwenLM/Qwen-Image/blob/main/assets/wechat.png">WeChat (微信)</a>   |   🫨 <a href="https://discord.gg/CV4E9rpNSD">Discord</a>   </p>
QWEN-IMAGE TECHNICAL REPORT CITATION:
@article{qwen-image,
    title={Qwen-Image Technical Report},
    author={Qwen Team},
    journal={arXiv preprint},
    year={2025}
}