
AMAImedia/GLM-5.3-Flash-FP8-GGUF
<!-- apex-banner --> <div style="background-color: #f59e0b; color: white; padding: 20px; border-radius: 10px; text-align: center; margin: 20px 0;"> <h2 style="color: white; margin: 0 0 10px 0;">⚡ Each donation funds the next large quant.</h2> <p style="font-size: 16px; margin: 0 0 15px 0;">I host free GGUF or MoE quants as independent research.<br> Local hardware: <b>Mechrevo Kuangshi GM7AG0M</b> — RTX 3060 Laptop 6GB GDDR6, 64GB DDR5, i7-12700H (14C/20T, 4.7GHz), Windows 11, Samsung 990 Pro.<br> Good for imatrix and 0.6–35B-class work in RAM. <b>9B+ and searches need rented H200/Blackwell</b>, typically $100 per quant.</p> <p style="font-size: 20px; margin: 0;"> <a href="https://boosty.to/amaimediacom" style="color: white; text-decoration: underline;">🎉 Boosty🦄</a> | <a href="https://donatex.gg/widgets/donation-goal/89bc59e8-b69c-467a-9aa0-5e1c3f8842d6" style="color: white; text-decoration: underline;">☕ Buy Me a Coffee🦄</a> | <a href="https://www.donationalerts.com/r/djbionicl" style="color: white; text-decoration: underline;">⭐ DonationAlerts🦄</a> </p> <p style="font-size: 14px; margin: 10px 0 0 0; opacity: 0.9;">💚 Thanks to Hugging Face for extra storage.🦄</p> </div>
NOESIS / AMAImedia
Released as part of the NOESIS Professional Multilingual Dubbing Automation Platform (framework: DHCF-FNO — Deterministic Hybrid Control Framework for Frozen Neural Operators).
- Founder: Ilia Bolotnikov
- Organization: AMAImedia.com
- X (Twitter): @AMAImediacom
- LinkedIn: Ilia Bolotnikov
- Telegram: @djbionicl
- Release date: 2026-09-21
AMAImedia
- Original repository: zai-org/GLM-5.3-Flash
GLM-5.3-Flash
<div align="center"> <img src=https://raw.githubusercontent.com/zai-org/GLM-5/refs/heads/main/resources/logo.svg width="15%"/> </div> <p align="center"> Join our <a href="https://raw.githubusercontent.com/zai-org/GLM-5/refs/heads/main/resources/wechat.png" target="blank">WeChat</a> or <a href="https://discord.gg/QR7SARHRxK" target="blank">Discord</a> community. <br> Check out the GLM-5.3-Flash <a href="https://z.ai/blog/glm-5.3-flash">blog</a> and GLM-5 <a href="https://arxiv.org/abs/2602.15763">technical report</a>. <br> Use GLM-5.3-Flash API services on the <a href="https://docs.z.ai/guides/llm/glm-5.3-flash">Z.ai API Platform</a>. </p>
Introduction
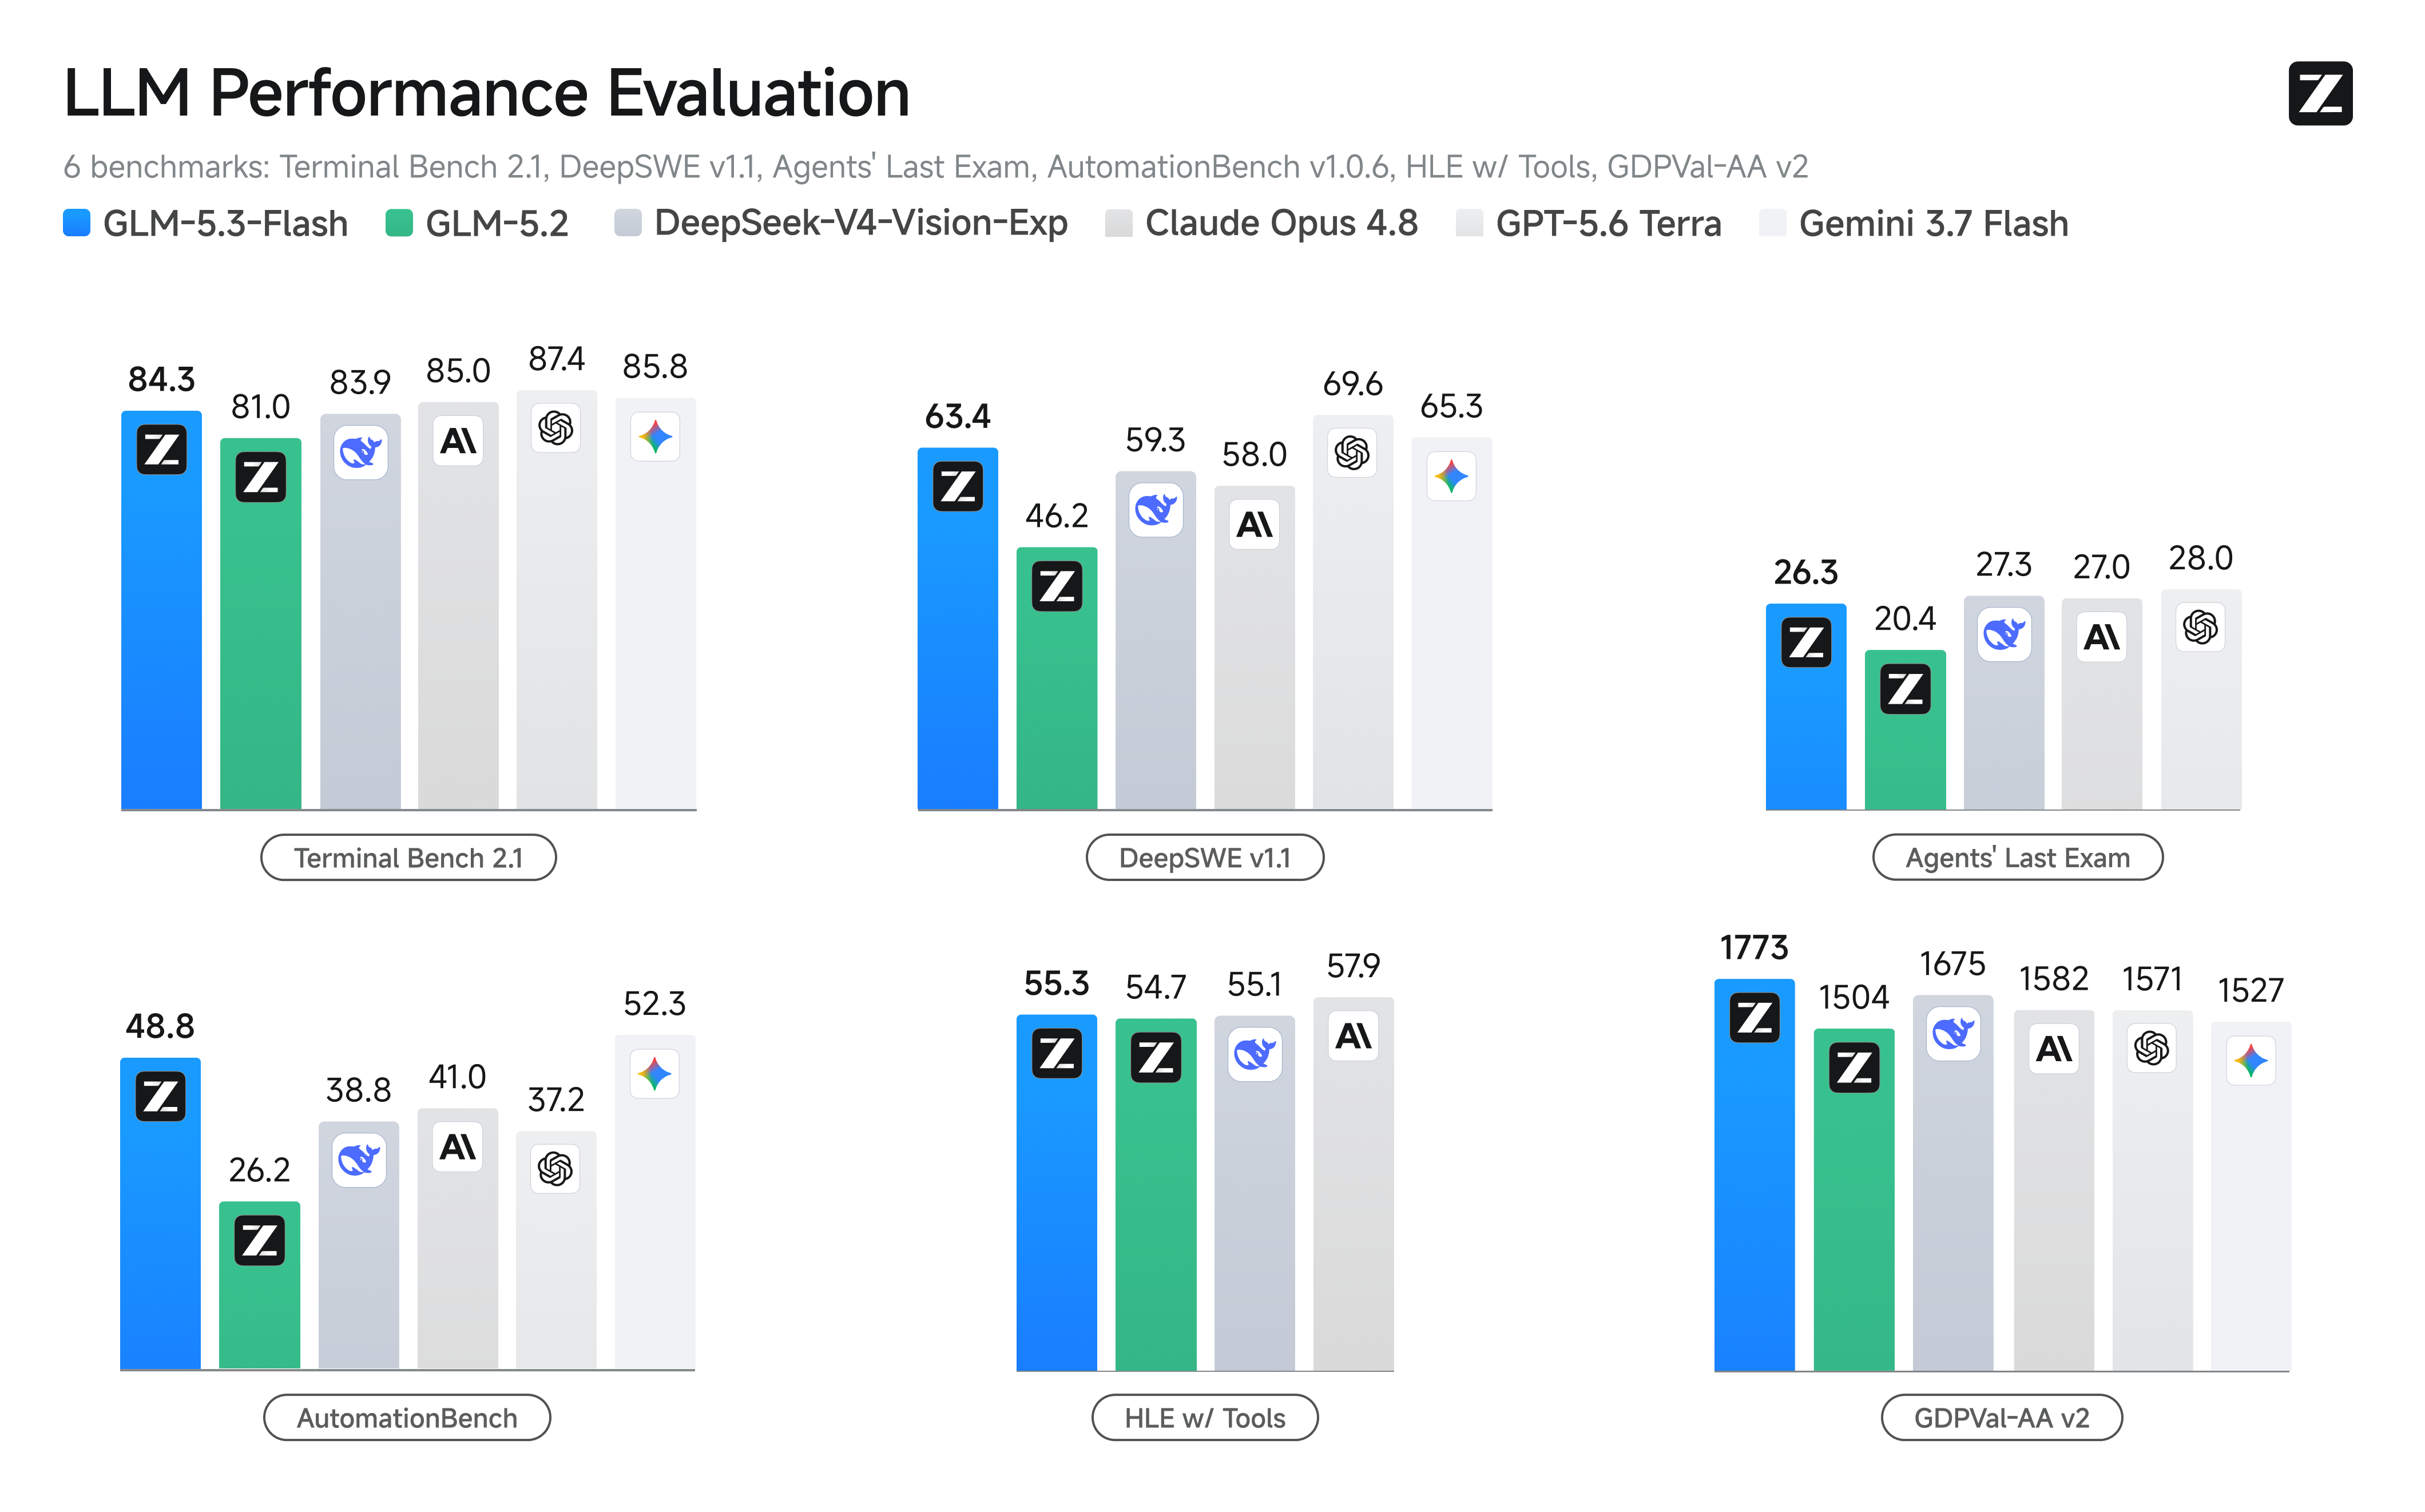
We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it is designed for efficient long-context, coding, agentic, and multimodal workloads.
GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. It combines sparse and linear attention with Manifold-Constrained Hyper-Connections (mHC) and a multimodal pre-training corpus.
Serve GLM-5.3-Flash Locally
GLM-5.3-Flash supports deployment with the following frameworks:
- SGLang — see the cookbook
- vLLM — see the recipes
- TokenSpeed — see the model recipe
- KTransformers — see the tutorial
Usage
Transformers: text generation
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "AMAImedia/GLM-5.3-Flash"
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto",
    trust_remote_code=True,
)

messages = [{"role": "user", "content": "Explain the main benefits of multimodal agents."}]
inputs = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt",
).to(model.device)

with torch.inference_mode():
    output = model.generate(
        inputs,
        max_new_tokens=512,
        temperature=0.7,
        top_p=0.9,
        do_sample=True,
    )

print(tokenizer.decode(output[0][inputs.shape[-1]:], skip_special_tokens=True))
Transformers: multimodal input
For image questions, use the official GLM processor and multimodal message format documented by the model implementation. Keep image inputs in the message content and use the processor to build model inputs; verify the exact API against the installed Transformers version.
from transformers import AutoProcessor, AutoModelForMultimodalLM

model_id = "AMAImedia/GLM-5.3-Flash"
processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForMultimodalLM.from_pretrained(
    model_id,
    device_map="auto",
    torch_dtype="auto",
    trust_remote_code=True,
)

messages = [{
    "role": "user",
    "content": [
        {"type": "image", "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/p-blog/candy.JPG"},
        {"type": "text", "text": "What is shown in this image?"},
    ],
}]

inputs = processor.apply_chat_template(
    messages,
    add_generation_prompt=True,
    tokenize=True,
    return_dict=True,
    return_tensors="pt",
).to(model.device)

outputs = model.generate(**inputs, max_new_tokens=128)
print(processor.decode(outputs[0][inputs["input_ids"].shape[-1]:], skip_special_tokens=True))
vLLM
pip install -U vllm
vllm serve AMAImedia/GLM-5.3-Flash \
  --trust-remote-code \
  --tensor-parallel-size 8 \
  --max-model-len 131072
The server exposes an OpenAI-compatible endpoint:
from openai import OpenAI

client = OpenAI(base_url="http://localhost:8000/v1", api_key="EMPTY")
response = client.chat.completions.create(
    model="AMAImedia/GLM-5.3-Flash",
    messages=[{"role": "user", "content": "Write a concise summary of this document."}],
    temperature=0.7,
    max_tokens=512,
)
print(response.choices[0].message.content)
Practical deployment notes
Use bfloat16 where supported, or a framework-supported quantized checkpoint when GPU memory is limited. For multimodal serving, follow the selected framework's documented image-input format. Confirm the installed framework version, GPU memory requirements, tensor-parallel configuration, and supported context length before production deployment.
Footnotes
- HLE w/ tools (full set): Evaluation uses temperature=1.0 and top_p=0.95 with a maximum generation length of 163,840 tokens and a maximum context length of 300,000 tokens.
- NL2Repo: Evaluation uses temperature=1.0, topp=1.0, and maxnew_tokens=64k under 1M context.
- DeepSWE: Evaluation uses temperature=0.95, top_p=1.0, timeout=6h, and 400K context.
- Terminal-Bench 2.1: Evaluation uses temperature=1.0, topp=1, maxnew_tokens=65536, and a 6h timeout.
- Toolathlon Verified: Results are reported as pass@1 averaged over three independent runs.
- AutomationBench: Evaluation uses AutomationBench v1.0.6.
- GDPval-AA v2: Models are evaluated by Artificial Analysis.
- BabyVision: Evaluation uses temperature=1.0, top_p=0.95, and a maximum context length of 164K tokens.
Citation
If you find GLM-5.3-Flash useful in your research, please cite the official technical report:
@misc{glm5team2026glm5vibecodingagentic,
  title={GLM-5: from Vibe Coding to Agentic Engineering},
  author={GLM-5-Team},
  year={2026},
  eprint={2602.15763},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2602.15763},
}