
pySilver/GLAMI-1M-remapped
This is fork of original dataset converted to dataset format with adjusted category names. GLAMI-1M contains 1.1 million fashion items, 968 thousand unique images and 1 million unique texts. It contains 13 languages, mostly European. And 191 fine-grained categories, for example we have 15 shoe types. It contains high quality annotations from professional curators and it also presents a difficult production industry problem. Each sample contains an image, country code, name in… See the full description on the dataset page: https://huggingface.co/datasets/pySilver/GLAMI-1M-remapped.
This is fork of original dataset converted to dataset format with adjusted category names.
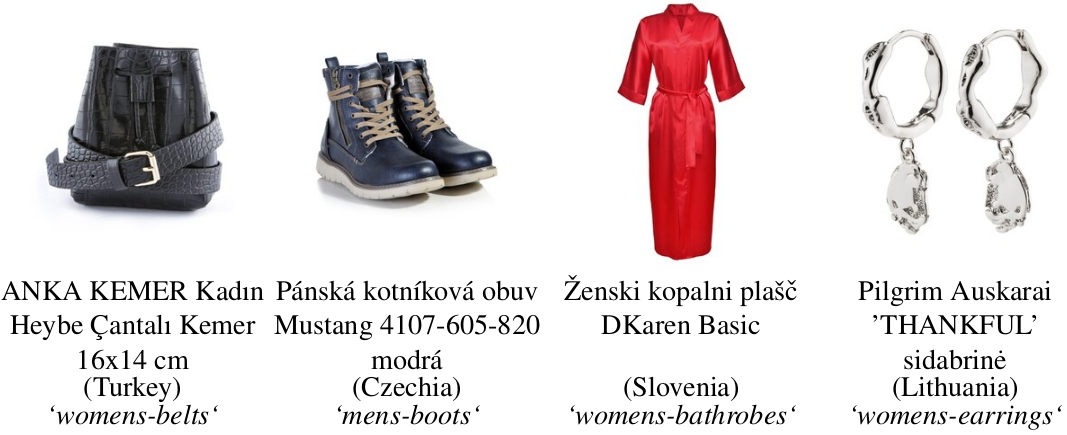
GLAMI-1M contains 1.1 million fashion items, 968 thousand unique images and 1 million unique texts. It contains 13 languages, mostly European. And 191 fine-grained categories, for example we have 15 shoe types. It contains high quality annotations from professional curators and it also presents a difficult production industry problem.
Each sample contains an image, country code, name in corresponding language, description, target category and source of the label which can be of multiple types, it can be human or rule-based but most of the samples are human-based labels.
Read more on GLAMI-1M home page at GitHub