
chuuhtetnaing/myanmar-wikipedia-dataset
Myanmar Wikipedia Dataset (Last Crawl Date: 25/03/2025) A collection of scraped Myanmar Wikipedia pages organized by category paths. Overview This dataset contains Myanmar Wikipedia articles scraped based on categorical organization. Unlike the official Wikimedia dataset (subset: 20231101.my), this repository provides an alternative approach to Myanmar Wikipedia content by following the categorical structure starting from the main entry page. Figure 1: The… See the full description on the dataset page: https://huggingface.co/datasets/chuuhtetnaing/myanmar-wikipedia-dataset.
Myanmar Wikipedia Dataset (Last Crawl Date: 25/03/2025)
A collection of scraped Myanmar Wikipedia pages organized by category paths.
Overview
This dataset contains Myanmar Wikipedia articles scraped based on categorical organization. Unlike the official Wikimedia dataset (subset: 20231101.my), this repository provides an alternative approach to Myanmar Wikipedia content by following the categorical structure starting from the main entry page.
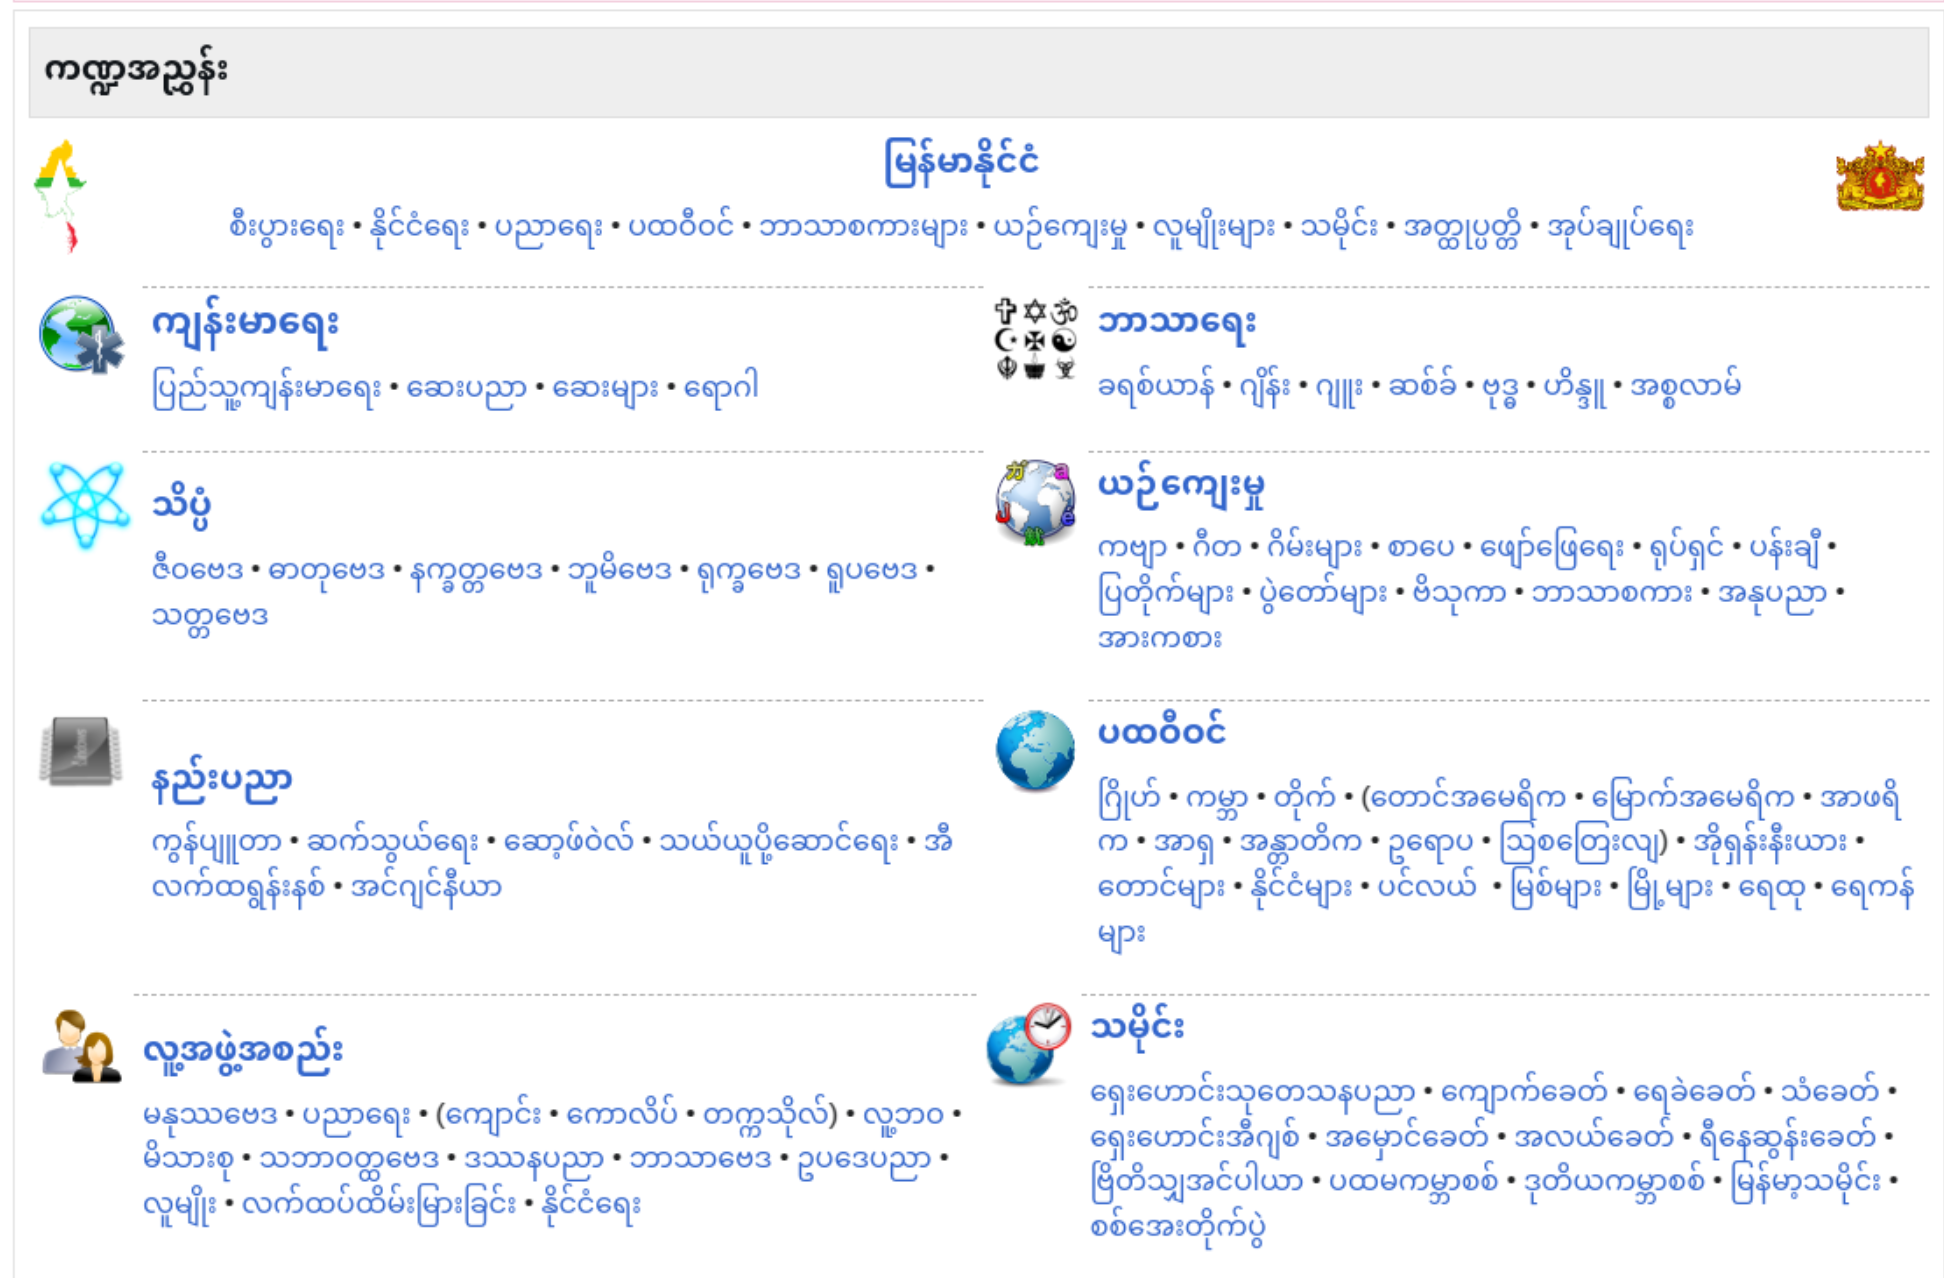 Figure 1: The initial category page showing both direct article links and category links
Dataset Structure
Columns
How to Use
You can easily load this dataset using the Hugging Face datasets library:
from datasets import load_dataset

ds = load_dataset("chuuhtetnaing/myanmar-wikipedia-dataset")
Data Organization Methodology
This dataset was created with a focus on comprehensive categorical coverage while minimizing redundancy:
- Articles are crawled following different category paths
- To reduce duplication, identical categories under different paths are excluded
- Example: If articles (page-1, page-2, page-3) are found under both:
category_path_1: category-a > category-b > category-ccategory_path_2: category-d > category-e > category-c- The second path is excluded to prevent duplication
- However, identical articles found under different category names are included:
- Example: If articles (page-1, page-2, page-3) can be found under both:
category_path_1: category-a > category-b > category-ccategory_path_2: category-a > category-e > category-f- Both paths are included since they represent different categorical organizations
Use Cases
This dataset is particularly useful for:
- Research on Myanmar language NLP tasks
- Building Myanmar-language models that benefit from categorical understanding
- Topic modeling of Myanmar-language content
License
This dataset is free to use for any purpose - personal, commercial, or educational.
Contributions
Feel free to create a pull request if you find any errors or have improvements to suggest for the dataset. Contributions to enhance the accuracy and completeness of the data are welcome.
Acknowledgments
Special thanks to the Wikipedia contributors who created and maintain the original Myanmar Wikipedia content that made this dataset possible.