
Qualcomm-AI-Research/QIVD
QIVD: Qualcomm Interactive Video Dataset A collection of 2,900 video clips paired with visual question-answer annotations. Each clip is associated with exactly one question drawn from one of 13 fine-grained QA categories, a full-sentence answer, a concise short answer, and a timestamp pinpointing the relevant moment in the video. Overview QIVD is a dataset and benchmark for online, situated audio-visual question answering. Unlike existing video QA benchmarks… See the full description on the dataset page: https://huggingface.co/datasets/Qualcomm-AI-Research/QIVD.
QIVD: Qualcomm Interactive Video Dataset
 
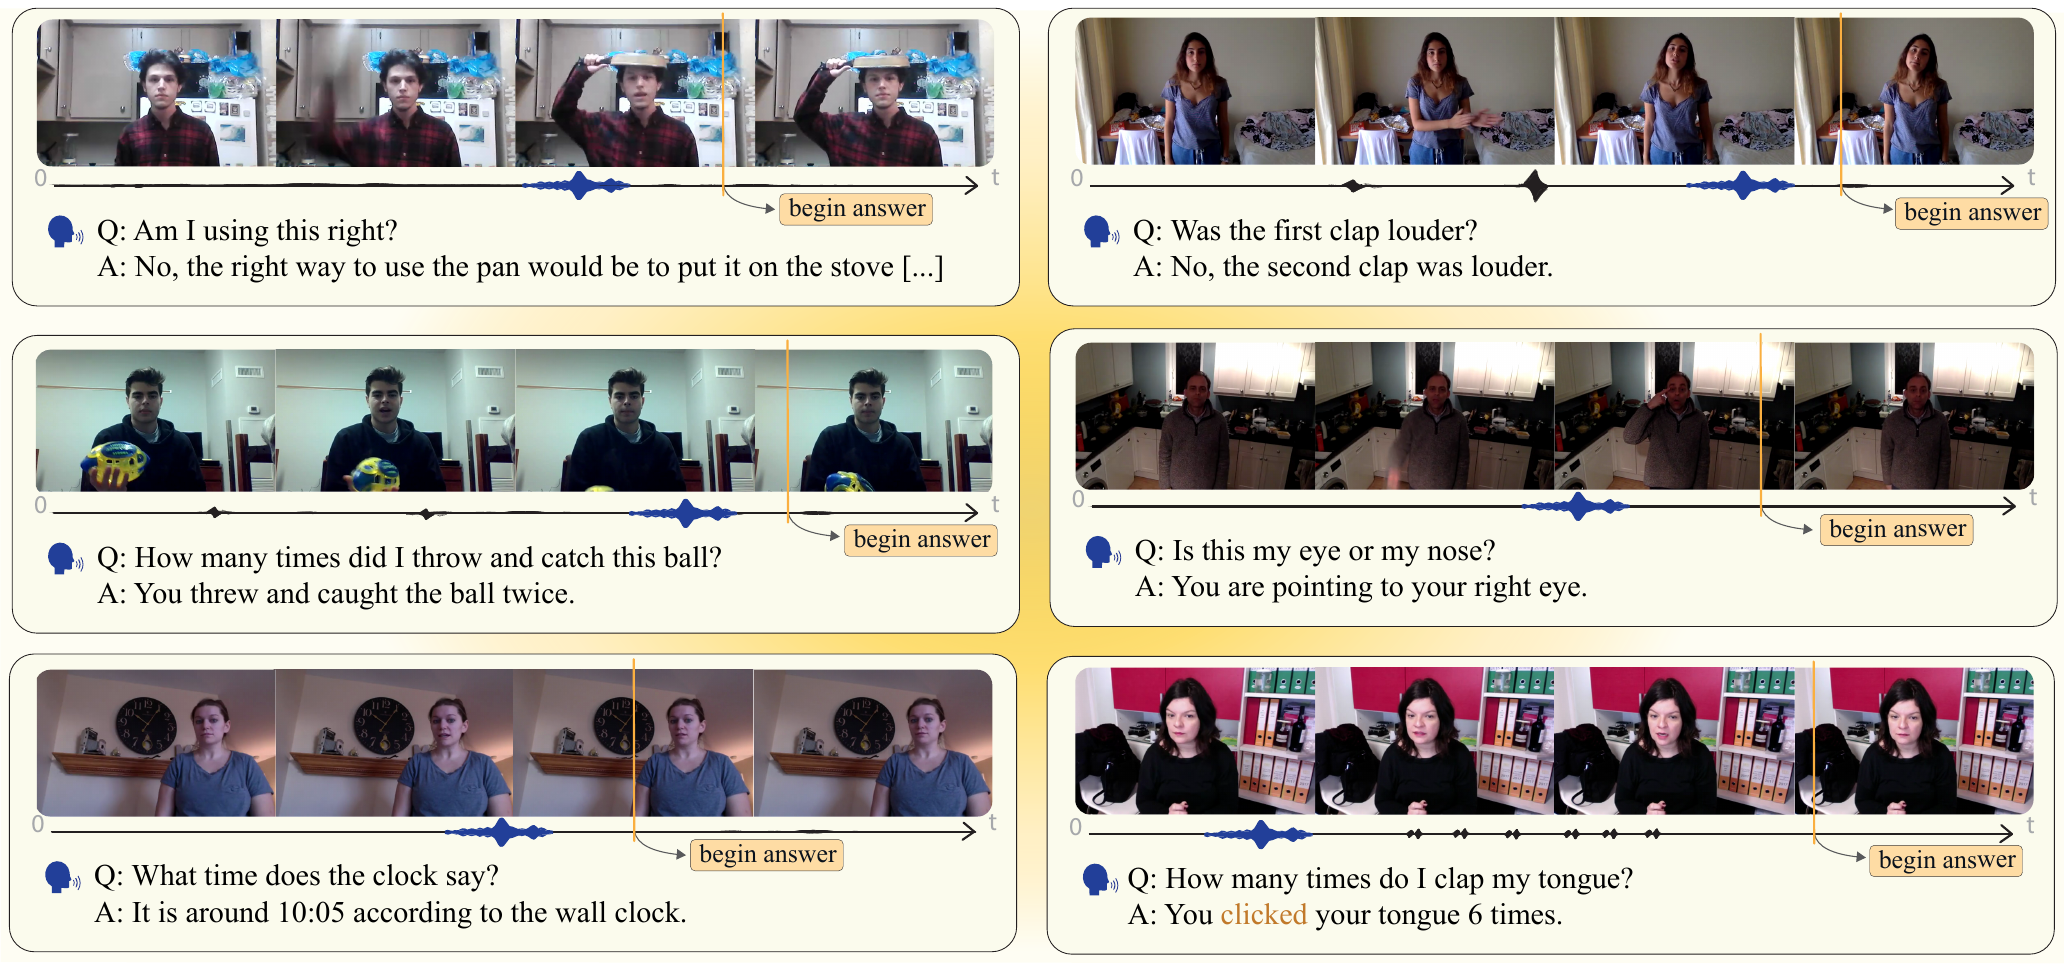
A collection of 2,900 video clips paired with visual question-answer annotations. Each clip is associated with exactly one question drawn from one of 13 fine-grained QA categories, a full-sentence answer, a concise short answer, and a timestamp pinpointing the relevant moment in the video.
Overview
QIVD is a dataset and benchmark for online, situated audio-visual question answering. Unlike existing video QA benchmarks that operate in an offline paradigm (full video + question given at once), QIVD captures a genuinely interactive setup: crowd workers recorded short egocentric clips while simultaneously speaking a question into the camera. The AI system must answer in real time from the audio-visual stream, identifying both what to answer and when to start answering.
Dataset Structure
├── metadata.parquet
└── videos/
    ├── 00000000.mp4
    ├── 00000001.mp4
    └── ...
Schema
Usage
from datasets import load_dataset

ds = load_dataset("Qualcomm-AI-Research/QIVD")
print(ds["train"][0])
# {
#   'video_file_name': 'videos/00000000.mp4',
#   'id': 1972,
#   'category': 'object referencing',
#   'question': "What am I holding in my left hand?",
#   'answer': "You are holding a Rubik's cube in your left hand.",
#   'short_answer': "A Rubik's cube",
#   'timestamp': '00:04.4'
# }
To download a specific video:
from huggingface_hub import hf_hub_download

video_path = hf_hub_download(
    repo_id="Qualcomm-AI-Research/QIVD",
    filename="videos/00000000.mp4",
    repo_type="dataset",
)
Dataset License
This dataset is released for research purposes only. Use of the dataset is subject to the license terms of the Qualcomm Interactive Video Dataset. Please refer to the accompanying license documentation for full terms, conditions, and usage restrictions.
Citation
@inproceedings{pourreza2026can,
    title={Can Vision-Language Models Answer Face to Face Questions in the Real-World?},
    author={Reza Pourreza and Rishit Dagli and Apratim Bhattacharyya and Sunny Panchal and Guillaume Berger and Roland Memisevic},
    booktitle={The Fourteenth International Conference on Learning Representations},
    year={2026},
    url={https://openreview.net/forum?id=I3dPEvbp8o}
}