
Pranesh535/NIH-Chest-X-ray-dataset
The NIH Chest X-ray dataset consists of 100,000 de-identified images of chest x-rays. The images are in PNG format. The data is provided by the NIH Clinical Center and is available through the NIH download site: https://nihcc.app.box.com/v/ChestXray-NIHCC
Dataset Card for NIH Chest X-ray dataset
Table of Contents
- Table of Contents
- Dataset Description
- Dataset Summary
- Languages
- Dataset Structure
- Data Instances
- Data Fields
- Data Splits
- Dataset Creation
- Curation Rationale
- Source Data
- Annotations
- Personal and Sensitive Information
- Considerations for Using the Data
- Social Impact of Dataset
- Discussion of Biases
- Other Known Limitations
- Additional Information
- Dataset Curators
- Licensing Information
- Citation Information
- Contributions
Dataset Description
- Homepage: NIH Chest X-ray Dataset of 10 Common Thorax Disease Categories
- Repository:
- Paper: ChestX-ray8: Hospital-scale Chest X-ray Database and Benchmarks on Weakly-Supervised Classification and Localization of Common Thorax Diseases
- Leaderboard:
- Point of Contact: rms@nih.gov
Dataset Summary
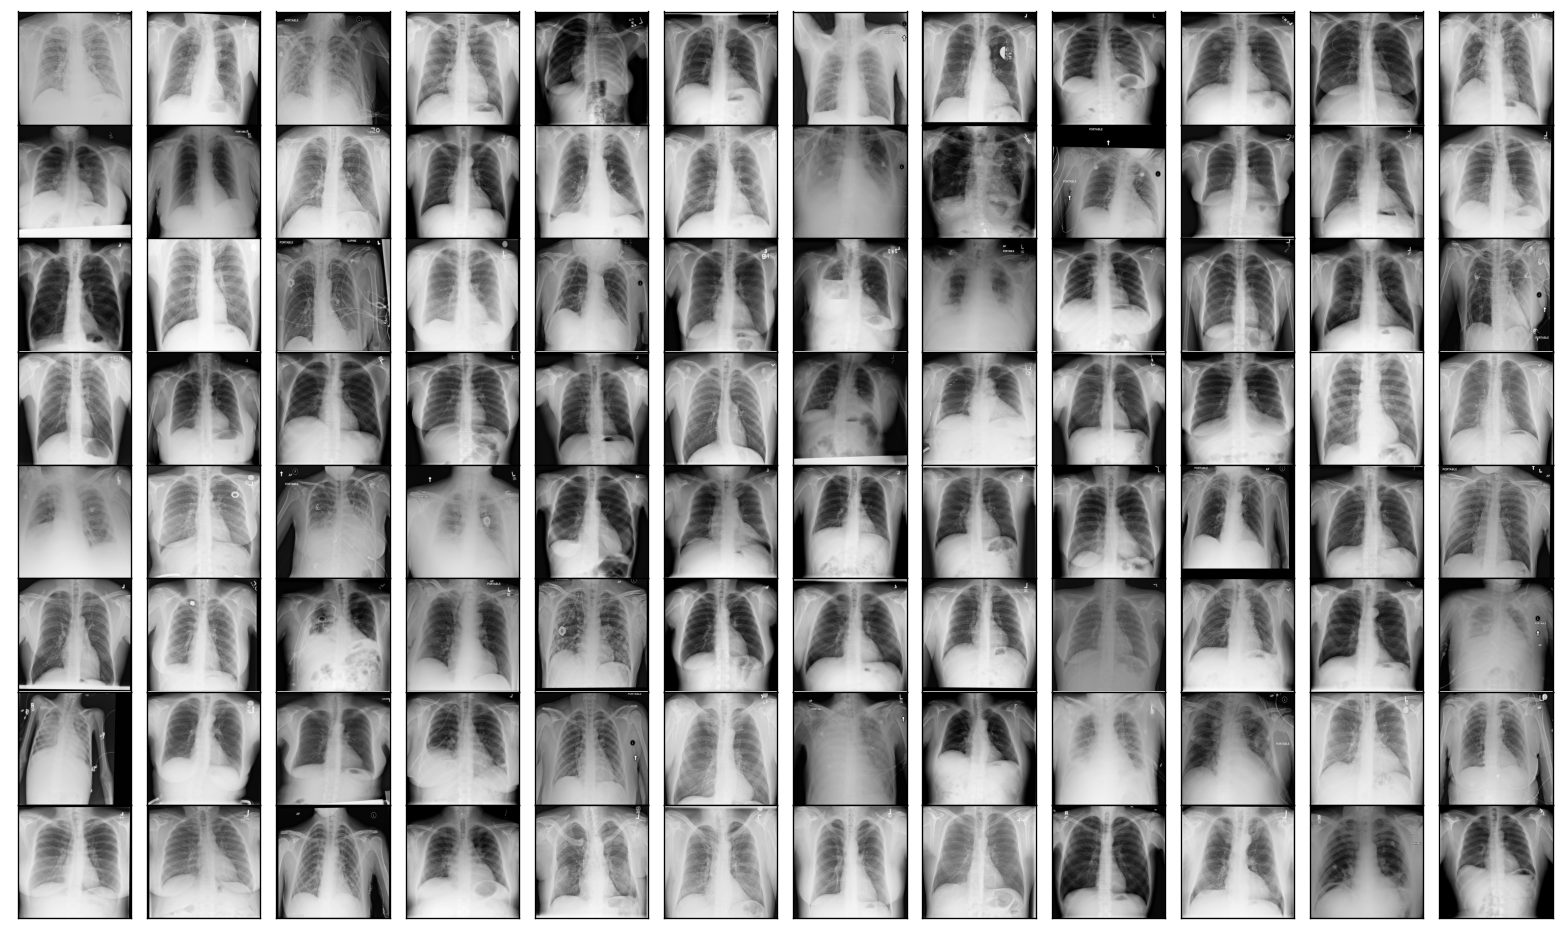
ChestX-ray dataset comprises 112,120 frontal-view X-ray images of 30,805 unique patients with the text-mined fourteen disease image labels (where each image can have multi-labels), mined from the associated radiological reports using natural language processing. Fourteen common thoracic pathologies include Atelectasis, Consolidation, Infiltration, Pneumothorax, Edema, Emphysema, Fibrosis, Effusion, Pneumonia, Pleuralthickening, Cardiomegaly, Nodule, Mass and Hernia, which is an extension of the 8 common disease patterns listed in our CVPR2017 paper. Note that original radiology reports (associated with these chest x-ray studies) are not meant to be publicly shared for many reasons. The text-mined disease labels are expected to have accuracy >90%.Please find more details and benchmark performance of trained models based on 14 disease labels in our arxiv paper: 1705.02315_
Dataset Structure
Data Instances
A sample from the training set is provided below:
{'image_file_path': '/root/.cache/huggingface/datasets/downloads/extracted/95db46f21d556880cf0ecb11d45d5ba0b58fcb113c9a0fff2234eba8f74fe22a/images/00000798_022.png',
 'image': <PIL.PngImagePlugin.PngImageFile image mode=L size=1024x1024 at 0x7F2151B144D0>,
 'labels': [9, 3]}
Data Fields
The data instances have the following fields:
image_file_pathastrwith the image pathimage: APIL.Image.Imageobject containing the image. Note that when accessing the image column:dataset[0]["image"]the image file is automatically decoded. Decoding of a large number of image files might take a significant amount of time. Thus it is important to first query the sample index before the"image"column, i.e.dataset[0]["image"]should always be preferred overdataset["image"][0].labels: anintclassification label. <details> <summary>Class Label Mappings</summary>
  {
    "No Finding": 0,
    "Atelectasis": 1,
    "Cardiomegaly": 2,
    "Effusion": 3,
    "Infiltration": 4,
    "Mass": 5,
    "Nodule": 6,
    "Pneumonia": 7,
    "Pneumothorax": 8,
    "Consolidation": 9,
    "Edema": 10,
    "Emphysema": 11,
    "Fibrosis": 12,
    "Pleural_Thickening": 13,
    "Hernia": 14
 }
</details>
Label distribution on the dataset:
Data Splits
Label distribution by dataset split:
Dataset Creation
Curation Rationale
[More Information Needed]
Source Data
Initial Data Collection and Normalization
[More Information Needed]
Who are the source language producers?
[More Information Needed]
Annotations
Annotation process
[More Information Needed]
Who are the annotators?
[More Information Needed]
Personal and Sensitive Information
[More Information Needed]
Considerations for Using the Data
Social Impact of Dataset
[More Information Needed]
Discussion of Biases
[More Information Needed]
Other Known Limitations
[More Information Needed]
Additional Information
Dataset Curators
[More Information Needed]
License and attribution
There are no restrictions on the use of the NIH chest x-ray images. However, the dataset has the following attribution requirements:
- Provide a link to the NIH download site: https://nihcc.app.box.com/v/ChestXray-NIHCC
- Include a citation to the CVPR 2017 paper (see Citation information section)
- Acknowledge that the NIH Clinical Center is the data provider
Citation Information
@inproceedings{Wang_2017,
	doi = {10.1109/cvpr.2017.369},
	url = {https://doi.org/10.1109%2Fcvpr.2017.369},
	year = 2017,
	month = {jul},
	publisher = {{IEEE}
},
	author = {Xiaosong Wang and Yifan Peng and Le Lu and Zhiyong Lu and Mohammadhadi Bagheri and Ronald M. Summers},
	title = {{ChestX}-Ray8: Hospital-Scale Chest X-Ray Database and Benchmarks on Weakly-Supervised Classification and Localization of Common Thorax Diseases},
	booktitle = {2017 {IEEE} Conference on Computer Vision and Pattern Recognition ({CVPR})}
}
Contributions
Thanks to @alcazar90 for adding this dataset.