
Multimedia-SMU/seeingculture-benchmark
Paper | Project Page | Leaderboard | Explorer | Code | CMB, the video successor Seeing Culture Benchmark (SCB) Evaluating Visual Reasoning and Grounding in Cultural Context The Seeing Culture Benchmark (SCB) evaluates cultural reasoning in vision-language models in two stages: i) selecting the correct visual option with multiple-choice visual question answering (VQA), and ii) segmenting the relevant cultural artifact as evidence of reasoning. Visual options in… See the full description on the dataset page: https://huggingface.co/datasets/Multimedia-SMU/seeingculture-benchmark.
Paper | Project Page | Leaderboard | Explorer | Code | CMB, the video successor
Seeing Culture Benchmark (SCB)
Evaluating Visual Reasoning and Grounding in Cultural Context
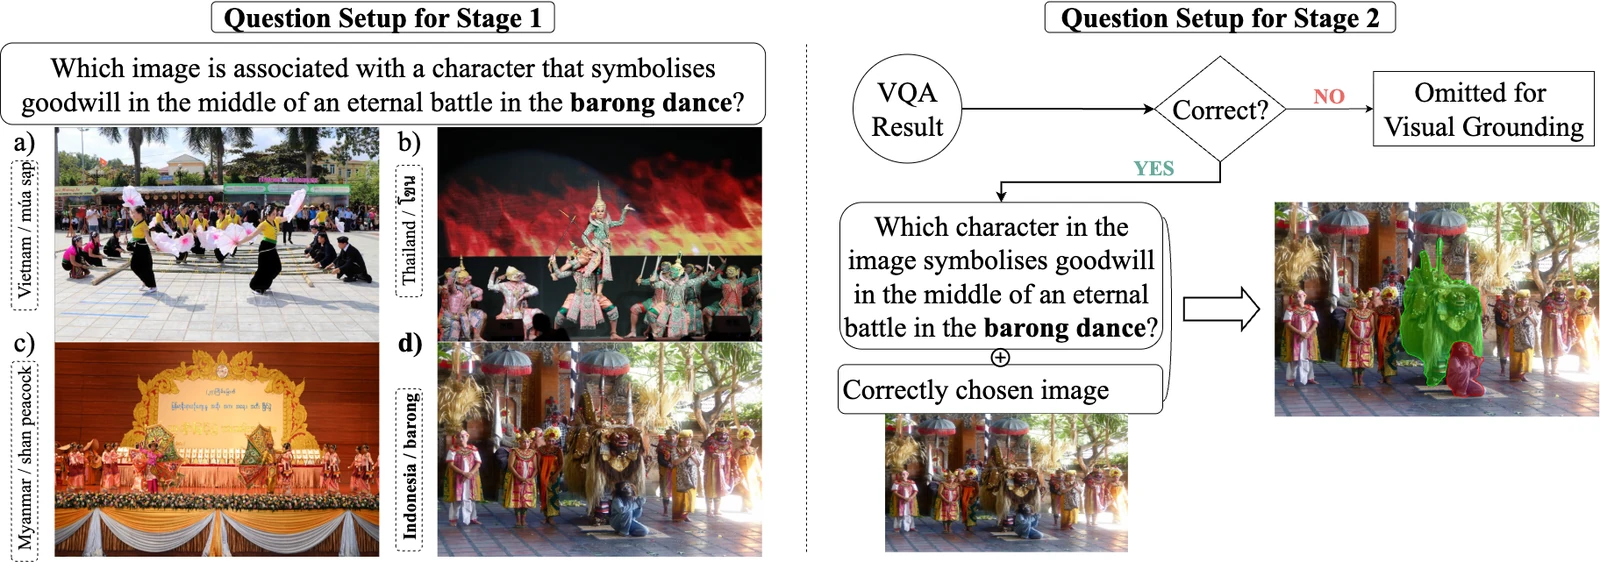
The Seeing Culture Benchmark (SCB) evaluates cultural reasoning in vision-language models in two stages: i) selecting the correct visual option with multiple-choice visual question answering (VQA), and ii) segmenting the relevant cultural artifact as evidence of reasoning. Visual options in the first stage are systematically organized into three types: those originating from the same country (Type 1), those from different countries (Type 2), or a mixed group (Type 3). Progression to the second stage occurs only after a correct visual option is chosen.
SCB comprises 1,065 images of 138 cultural artifacts across five categories (music, dance, game, wedding, celebration) from seven Southeast Asian countries, with 3,178 questions, of which 1,093 are unique and meticulously curated by human annotators. Our evaluation of various VLMs reveals the disparity between visual reasoning and spatial grounding in culturally nuanced scenarios: the best accuracy and the best grounding come from different models.
Results for 10 VLMs are on the live leaderboard; browse real samples in the interactive explorer.
News
- [2026-09] The Cultural Moment Benchmark (CMB) is selected for an Oral presentation at EMNLP 2026 (2.7% acceptance rate).
- [2026-08] Our video-based successor, the Cultural Moment Benchmark (CMB), is accepted to EMNLP 2026.
- [2026-07] Live leaderboard and dataset explorer launched on the project page. External results are welcome (see Evaluation below).
- [2025-11] SCB is presented at EMNLP 2025 (Main Conference) in Suzhou, China.
- [2025-09] Dataset released on HuggingFace, paper on arXiv.
Dataset Structure
image_data/Image_List_dev.csv(149 rows): the public dev split, one row per unique question withImage Path,Country,Category,Concept,Question,Rationale,Reference(source article), andURL(original image source). The other columns:Normal Index(the row's position in the full 1,093-row metadata list),Unique Index(the question id, shared by the few rows whose questions are variants of one another),Object(the artifact the question is about, also the fourth folder ofImage Path),Image ID(the file name) andNumber(its numeric suffix),Status(ACC, accepted by the annotators),Question w/o Image(the same question rephrased without reference to an image, for text-only probing),Split(dev), andSource(where the image was found:Google Image,Google LinkorSEA-VL). These are the same samples shown in the interactive explorer; use them to develop and debug prompts. Their 398 MCQ variants (listed inmcq_data/dev_mcq_ids.csv) are excluded from private test scoring. The full metadata list is provided to evaluators together with evaluation access.mcq_data/MCQ_List.csv(3,178 rows): the multiple-choice questions.choice_atochoice_dare opaque image identifiers (by design: they carry no information about the answer);typeis the option-composition type (1 = within culture, 2 = across cultures, 3 = mixed). Evaluators receive the identifier-to-image mapping together with evaluation access.mcq_data/MCQ_Avoid_List.csv: cross-country concept overlaps excluded during option generation.
Images are distributed separately; see Evaluation below.
Loading the metadata
from datasets import load_dataset

dev = load_dataset("Multimedia-SMU/seeingculture-benchmark", "Image_List_dev")
mcq = load_dataset("Multimedia-SMU/seeingculture-benchmark", "MCQ_List")
print(dev["dev"][0]["Question"])
print(mcq["test"][0]["question"])
Evaluation
The answer key and the segmentation masks are withheld: SCB is a test-only benchmark. To evaluate your model:
- Develop and debug your pipeline on the public dev split (
Image_List_dev.csv; its 398 MCQ variants are excluded from test scoring). - Contact buraks@smu.edu.sg for evaluation access (images and scoring).
- Run the two-stage evaluation with the official code.
- Submit your result JSON by email or as a GitHub issue to appear on the leaderboard.
The MCQ generator in the code repository can regenerate question variants; see its README for setup (source setup.sh, then source generate.sh).
Usage and License
SCB is a test-only benchmark designed to evaluate models. Please do not use it for training.
The images were collected from the internet and are not owned by the authors; copyright remains with the original sources; the dev split records each image's source URL and reference, and full provenance for the test set is available on request. All annotations (questions, rationales, masks) are released under the CC BY-NC-SA 4.0 license.
If you are the copyright owner of any image referenced in this dataset and believe its use conflicts with your licensing terms, please contact us at buraks@smu.edu.sg. We are committed to addressing legitimate concerns promptly.
Citation Information
If you use this dataset, please cite our EMNLP 2025 paper:
@inproceedings{satar-etal-2025-seeing,
    title = "Seeing Culture: A Benchmark for Visual Reasoning and Grounding",
    author = "Satar, Burak  and
      Ma, Zhixin  and
      Irawan, Patrick Amadeus  and
      Mulyawan, Wilfried Ariel  and
      Jiang, Jing  and
      Lim, Ee-Peng  and
      Ngo, Chong-Wah",
    booktitle = "Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing",
    month = nov,
    year = "2025",
    address = "Suzhou, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2025.emnlp-main.1131/",
    doi = "10.18653/v1/2025.emnlp-main.1131",
    pages = "22227--22243",
    ISBN = "979-8-89176-332-6"
}