
ps2181/invoice-processing-pipeline
<div align="center">
<img src="https://capsule-render.vercel.app/api?type=waving&color=gradient&customColorList=6,11,20&height=200§ion=header&text=Invoice%20Processing%20Pipeline&fontSize=40&fontColor=fff&animation=twinkling&fontAlignY=35&desc=Self-Improving%20Multi-Agent%20Fraud%20Detection%20%7C%20OpenEnv%20%2B%20GRPO%20%2B%20Qwen2.5&descAlignY=55&descSize=16" width="100%"/>
<p> <a href="https://ps2181-invoice-processing-pipeline.hf.space/web"> <img src="https://img.shields.io/badge/🚀%20Live%20Demo-HuggingFace%20Spaces-FF9D00?style=for-the-badge&logo=huggingface&logoColor=white" /> </a> <a href="https://colab.research.google.com/drive/1C13giNt-NmbzKNFJr5L1fms3L8LfmB"> <img src="https://img.shields.io/badge/Training%20Colab-Open%20Notebook-F9AB00?style=for-the-badge&logo=googlecolab&logoColor=white" /> </a> <a href="https://ps2181-invoice-processing-pipeline.hf.space/docs"> <img src="https://img.shields.io/badge/API%20Docs-FastAPI-009688?style=for-the-badge&logo=fastapi&logoColor=white" /> </a> </p>
<p> <img src="https://img.shields.io/badge/Framework-OpenEnv-1A356E?style=for-the-badge" /> <img src="https://img.shields.io/badge/Model-Qwen2.5--1.5B%20+%20LoRA%20r%3D16-8B1A4E?style=for-the-badge" /> <img src="https://img.shields.io/badge/Training-GRPO%20+%20Unsloth-00A67E?style=for-the-badge" /> <img src="https://img.shields.io/badge/Agents-5%20Adversarial-E44D26?style=for-the-badge" /> </p>
<p> <img src="https://img.shields.io/badge/Tasks-10%20Progressive-6C3483?style=for-the-badge" /> <img src="https://img.shields.io/badge/Deployment-Docker%20%7C%20HF%20Spaces-0D1117?style=for-the-badge&logo=docker" /> <img src="https://img.shields.io/badge/Theme-%234%20Self--Improvement-FF6B35?style=for-the-badge" /> <img src="https://img.shields.io/badge/Hackathon-Meta%20PyTorch%202026-185FA5?style=for-the-badge" /> </p>
<br/>
Meta PyTorch OpenEnv Hackathon — Grand Finale · April 25–26, 2026 Team: Pritam Satpathy & Gnana Nawin T · VIT, Vellore
<br/>
<a href="https://git.io/typing-svg"> <img src="https://readme-typing-svg.demolab.com?font=Fira+Code&weight=600&size=22&pause=1000&color=007A87¢er=true&vCenter=true&width=750&lines=5-Agent+Adversarial+Fraud+Detection+System;Self-Improving+via+Cross-Episode+Regulator;GRPO-Trained+LoRA+Agents+on+Live+Environment;Invoice+%E2%86%92+Extract+%E2%86%92+Audit+%E2%86%92+Approve+%E2%86%92+Improve" alt="Typing SVG" /> </a>
</div>
🔥 The Core Idea
A system that continuously generates harder challenges targeting its own weakest points.
Most fraud detection pipelines are static. Ours gets harder for itself over time: the Regulator finds where the Auditor keeps failing, the Generator exploits those exact blind spots in the next episode, the Auditor's new mistakes update the Regulator — and the loop closes without any human intervention.
Primary theme: #4 Self-Improvement · Secondary: #1 Multi-Agent Interactions
<div align="center"> <img width="1710" height="326" alt="5-agent self-improvement loop" src="https://github.com/user-attachments/assets/319654c3-aa24-47e8-9716-734d4e902168" /> </div>
🤖 5-Agent Architecture
🎯 Regulator ──bias weights──────────────────────────────────► ⚡ Generator
     ▲                                                                │
     │                                                      raw invoice text
     │ missed fraud types                                             ▼
     │                                                         🔍 Extractor
     │                                                                │
     │                                                     structured data
     │                                                                ▼
     └──── episode outcome ──── ✅ Approver ◄─audit results─── 🕵️ Auditor
<div align="center">
</div>
⚡ Three Novel Features
<table> <tr> <td width="33%" align="center">
🔮 Predictive Regulator
Computes trend slopes over 5-episode windows.<br/>Warns of emerging blind spots before detection rates cross the critical threshold — proactive oversight, not reactive retraining.
+0.15 early-warning bonus
</td> <td width="33%" align="center">
🧬 Compound Fraud
Invoices carry two fraud signals simultaneously (e.g. phantom vendor + price gouging).<br/>Partial credit +0.65 for catching one; full reward +0.99 for both.
Prevents single-signal heuristics.
</td> <td width="33%" align="center">
📊 Confidence Calibration
Tracks (confidence, correct?) pairs per fraud type.<br/>Detects overconfident misses — the Auditor saying "90% sure, approved" on fraud — the most dangerous real-world failure mode.
</td> </tr> </table>
🎯 10 Tasks — Progressive Curriculum
<div align="center">
</div>
Dynamic difficulty also adjusts within each task via a rolling 10-episode score window: score above 0.85 → heavier OCR, more discrepancies, deeper traps. Drop below 0.60 → it eases off.
📈 Training Results — GRPO on Live Environment
All 3 agents trained with TRL GRPOTrainer + Unsloth using the deployed HF Space as the live reward verifier — /grader endpoint is the reward function during training.
Before vs After Training
<div align="center">
</div>
Setup: Qwen2.5-1.5B-Instruct · 4-bit QLoRA r=16 · Unsloth + TRL · Google Colab A100
Extractor Reward Curve
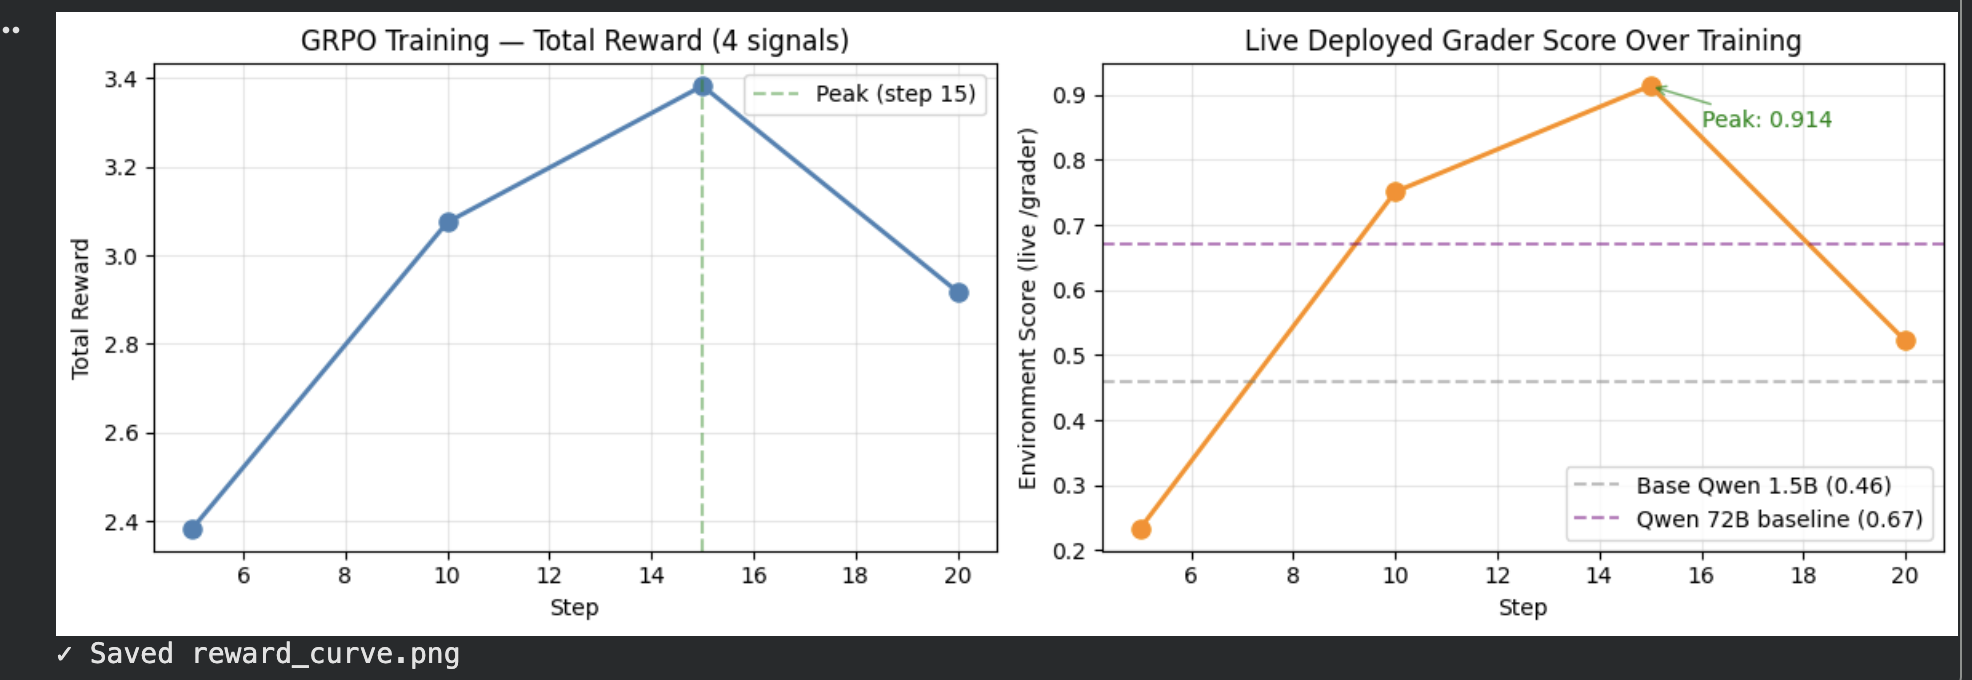 X-axis: training step (1–20) · Y-axis: reward (0–1). Left: total GRPO reward across 4 independent signals (format 0.10 + field accuracy 0.40 + math 0.25 + completeness 0.25). Right: live `/grader` score peaking at 0.914 — above Qwen 72B baseline (0.67) and untrained 1.5B (0.46).
Left: Total GRPO reward across 4 signals (format + field + math + completeness) over 20 training steps. Right: Live environment grader score peaking at 0.914 — above Qwen 72B baseline (0.67) and untrained 1.5B baseline (0.46).
Auditor Reward Curve (Run 2 — Bug Fixed)
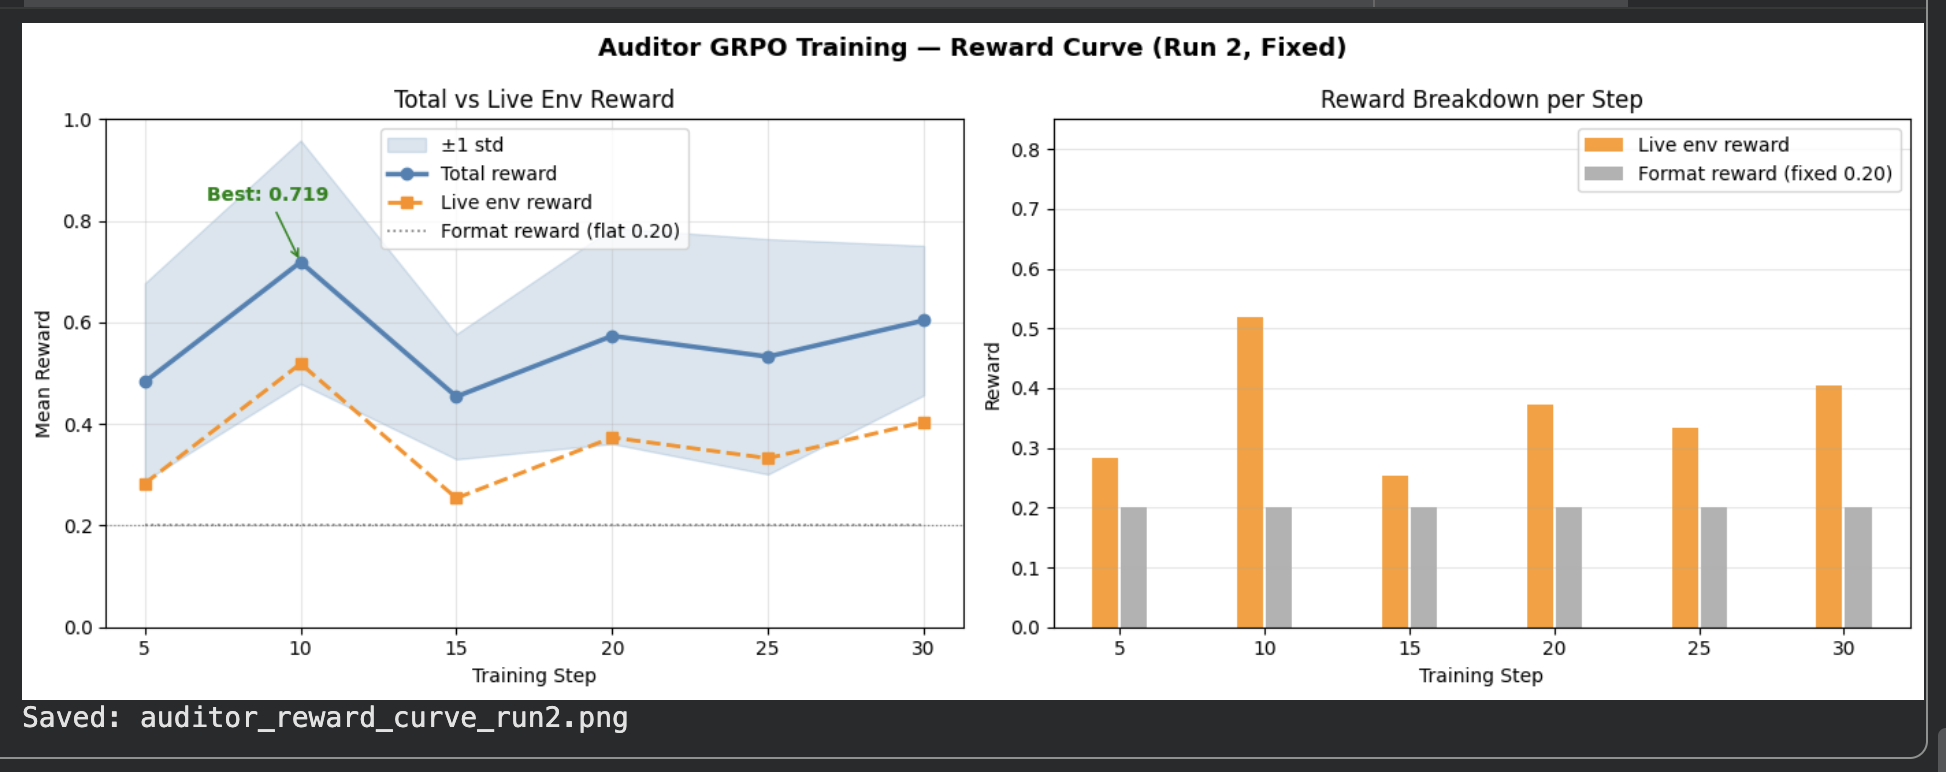 X-axis: training step (1–30) · Y-axis: reward (0–1). Total reward (blue) and live env reward (orange) with ±1 std band. Best total: 0.719 at step 10. Live env reward climbed from 0.01 (dead signal, Run 1) to 0.52 after fixing the TRL episode_id list indexing bug.
Total reward (blue) and live env reward (orange) over 30 steps with ±1 std band. Best total reward: 0.719. Live env reward rose from 0.01 (dead signal in Run 1) to 0.52 after fixing the episode_id list bug.
Generator Reward Curve
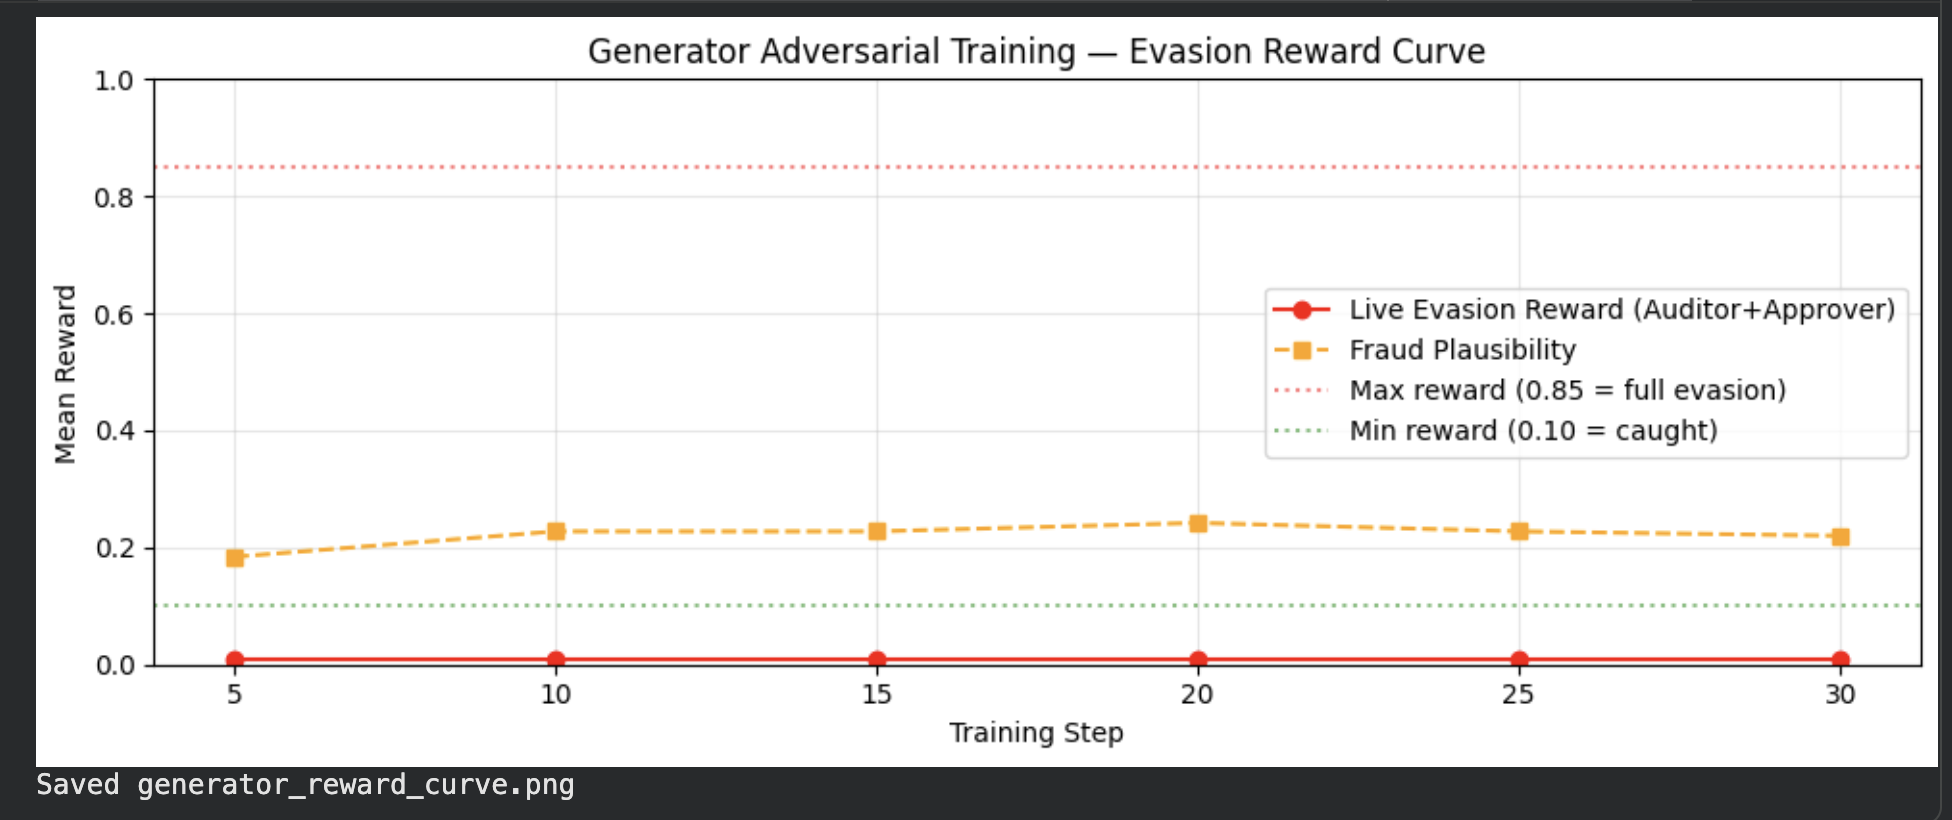 X-axis: training step (1–30) · Y-axis: reward (0–1). Live evasion reward (red) flat near 0 — Auditor+Approver caught all fraud attempts. Fraud plausibility reward (orange dashed) stable at ~0.20 — Generator learned realistic invoice structure even without successful evasion.
Live evasion reward (red) flat near 0 — Auditor+Approver caught all fraud attempts. Fraud plausibility reward (orange dashed) learned and stable at ~0.20, showing the Generator learned to produce realistic-looking invoices even without successful evasion.
🔍 Reward Hacking Caught at Step 10
At step 10 the model achieved math_consistency = 0.97 and completeness = 1.0 while field_accuracy = 0.00 — it had learned to output arithmetically-consistent JSON with entirely hallucinated values:
Step 10 — Reward Hacking Detected:
  format:            0.10  ✅
  math_consistency:  0.97  ✅ ← model gaming this signal
  completeness:      1.00  ✅ ← model gaming this signal
  field_accuracy:    0.00  ❌ ← hallucinating all values

  Action: adjusted training emphasis on field_accuracy weight
  Result: field_accuracy climbed to 0.30+ by step 30
Without 4 independent signals, a single aggregated reward would have called this success. Independent signals are diagnostics, not just incentives.
Auditor Training — Run 2 (exact data)
<div align="center">
Run 1 (dead signal): live env reward flat at 0.010 — TRL passes episode_id as a list; old code sent the whole list instead of indexing per completion
</div>
🎁 Reward Architecture
🔍 Extractor — 4 Independent Signals
reward_format(extracted)             # 0.10 — all 5 required JSON keys present?
reward_field_accuracy(extracted, gt) # 0.40 — vendor / date / currency / total match?
reward_math_consistency(extracted)   # 0.25 — qty × unit_price = amount per line?
reward_completeness(extracted, gt)   # 0.25 — all expected line items captured?

# All clamped to (0.01, 0.99) — no log(0), no gradient collapse at boundaries
🕵️ Auditor
<div align="center">
</div>
⚡ Generator (Adversarial Self-Play)
🎯 Regulator — Cross-Episode
Total = Precision(0.35) + Recall(0.35) + No-over-flagging(0.15) + Early-warning-bonus(0.15)The early-warning bonus rewards predictions of emerging blind spots — before detection rates cross the critical threshold.
🧠 Trained LoRA Agents
<div align="center">
</div>
LoRA target modules: q_proj, k_proj, v_proj, o_proj, gate_proj, up_proj, down_proj
🌍 The Regulator in Action
After each episode, the Regulator publishes a report the Generator uses to bias its next batch:
GET /regulator/report

{
  "total_audits_recorded": 20,
  "detection_rates": {
    "phantom_vendor":        "31%  ⚠ BLIND SPOT (-0.08↓)",
    "price_gouging":         "74%  ✓ OK (+0.03↑)",
    "math_fraud":            "81%  ✓ OK (+0.01↑)",
    "duplicate_submission":  "62%  ⚡ EMERGING (-0.02↓)"
  },
  "blind_spots": ["phantom_vendor"],
  "emerging_blind_spots": ["duplicate_submission"],
  "generator_weights": {
    "phantom_vendor":       0.30,    ← 3× upweighted (blind spot)
    "duplicate_submission": 0.20,    ← 2× upweighted (emerging)
    "price_gouging":        0.125,
    "math_fraud":           0.125,
    "compound_fraud":       0.10
  },
  "verdict": "Recommend retraining on: phantom_vendor"
}
🎭 Sample Multi-Agent Episode
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
  MULTI-AGENT PIPELINE  ·  LIVE EPISODE
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

  🎯  REGULATOR  (30-episode rolling window)
  ────────────────────────────────────────────────
  phantom_vendor     31%  ⚠ BLIND SPOT  ← prioritised 60%
  price_gouging      74%  ✓ OK
  math_fraud         81%  ✓ OK
  duplicate          62%  ✓ OK

  ⚡  GENERATOR  (Qwen2.5 LoRA)
  ────────────────────────────────────────────────
  Fraud focus : phantom_vendor (60% Regulator weight)
  Vendor      : ShadowByte Technologies  ← not in registry

  🔍  EXTRACTOR  (Qwen2.5 LoRA)
  ────────────────────────────────────────────────
  Reward : 0.847  [format 0.10 · field 0.38 · math 0.25 · completeness 0.12]

  🕵️  AUDITOR  (Qwen2.5 LoRA)
  ────────────────────────────────────────────────
  INV-85529  →  🚨 FLAGGED  [PHANTOM VENDOR]  conf=0.91
  INV-85530  →  ✅ APPROVED                   conf=0.88

  ✅  APPROVER
  ────────────────────────────────────────────────
  INV-85529  →  ❌ REJECT
  Generator reward : 0.60  (evaded Auditor on 1/3, Approver caught)

  🎯  REGULATOR UPDATE
  ────────────────────────────────────────────────
  phantom_vendor detection: 31% → 45%  ↑ improving
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
🚀 Quick Start
# Health check
curl https://ps2181-invoice-processing-pipeline.hf.space/health

# Environment-wide metrics
curl https://ps2181-invoice-processing-pipeline.hf.space/metrics

# Auto-progressive curriculum episode
curl -X POST https://ps2181-invoice-processing-pipeline.hf.space/reset \
  -H "Content-Type: application/json" -d '{"task_id": "curriculum"}'

# Start multi-agent episode
curl -X POST https://ps2181-invoice-processing-pipeline.hf.space/multi/reset

# Regulator blind spot report
curl https://ps2181-invoice-processing-pipeline.hf.space/regulator/report
Run Training (Google Colab)

Colab → /reset (fresh synthetic invoice from live environment)
      → model generates JSON
      → /grader scores against ground truth
      → GRPO updates weights toward higher-reward completions
      → repeat 200 steps
🗂️ Repository Structure
invoice-processing-pipeline/
│
├── server/
│   ├── app.py                      # FastAPI — 18 endpoints
│   ├── environment.py              # 10 tasks · graders · dynamic difficulty
│   ├── multi_agent_environment.py  # 5-agent system + AuditorPerformanceTracker
│   ├── agents.py                   # Lazy-loading LoRA inference wrappers
│   └── web_ui.py                   # Gradio UI (mounted at /web)
│
├── models.py                       # Pydantic: Action · Observation · State
├── inference.py                    # Standalone inference helper
├── client.py                       # OpenEnv-compatible Python client
│
├── extractor_training_grpo.ipynb   # 🔥 Extractor GRPO training (Unsloth + TRL)
├── auditor_grpo_training.ipynb     # 🔥 Auditor GRPO training
├── generator_grpo_training.ipynb   # 🔥 Generator GRPO training
│
├── assets/
│   ├── reward_curve.png            # Extractor training curve
│   ├── auditor_reward_curve_run2.png
│   └── generator_reward_curve.png
│
├── openenv.yaml                    # OpenEnv manifest (all tasks declared)
├── Dockerfile                      # HF Spaces Docker (port 7860, non-root UID 1000)
├── pyproject.toml                  # Project metadata + dependencies
├── requirements.txt                # Runtime dependencies
├── validate-submission.sh          # Submission validator script
├── BLOG.md                         # HuggingFace blog post
└── ROUND2_PROBLEM_STATEMENT.md     # Full problem statement + reward design rationale
🔌 API Reference
Core OpenEnv
Multi-Agent
Regulator
🏗️ Tech Stack
<div align="center">
</div>
🎭 Theme Alignment
<div align="center">
</div>
👥 Team
<div align="center">
Meta PyTorch OpenEnv Hackathon — Grand Finale · April 25–26, 2026 · Bangalore
</div>
🔗 All Links
<div align="center">
</div>
<div align="center">
<img src="https://capsule-render.vercel.app/api?type=waving&color=gradient&customColorList=6,11,20&height=100§ion=footer&animation=twinkling" width="100%"/>
Built with ❤️ for the Meta PyTorch OpenEnv Hackathon 2026
"The system that gets harder for itself — so the agent never stops learning."
</div>