
matttrent/sd-image-variations-diffusers
612
1---2thumbnail: >-3 https://repository-images.githubusercontent.com/523487884/fdb03a69-8353-4387-b5fc-0d85f888a63f4datasets:5- ChristophSchuhmann/improved_aesthetics_6plus6license: other7tags:8- stable-diffusion9- stable-diffusion-diffusers10- image-to-image11duplicated_from: lambdalabs/sd-image-variations-diffusers12---13 14# Stable Diffusion Image Variations Model Card15 16This version of Stable Diffusion has been fine tuned from [CompVis/stable-diffusion-v1-3-original](https://huggingface.co/CompVis/stable-diffusion-v-1-3-original) to accept CLIP image embedding rather than text embeddings. This allows the creation of "image variations" similar to DALLE-2 using Stable Diffusion. This version of the weights has been ported to huggingface Diffusers, to use this with the Diffusers library requires the [Lambda Diffusers repo](https://github.com/LambdaLabsML/lambda-diffusers).17 18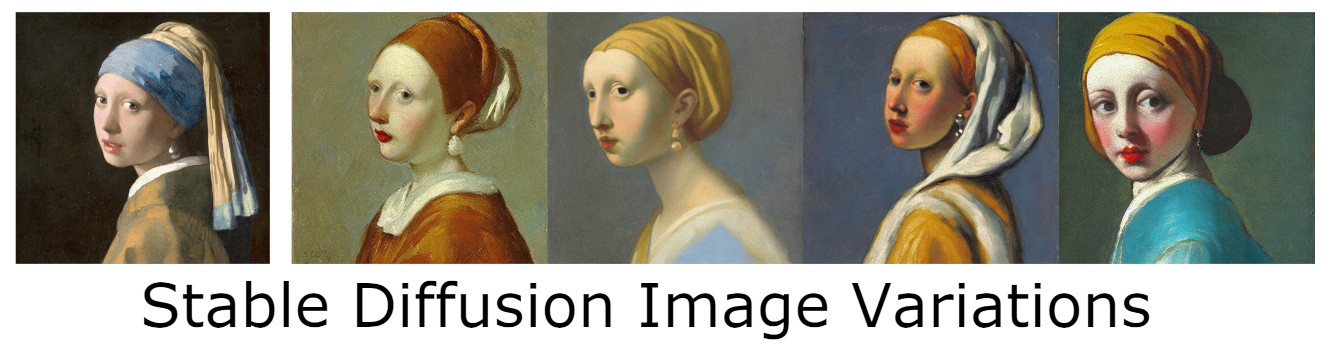19 20## Example21 22First clone [Lambda Diffusers](https://github.com/LambdaLabsML/lambda-diffusers) and install any requirements (in a virtual environment in the example below):23 24```bash25git clone https://github.com/LambdaLabsML/lambda-diffusers.git26cd lambda-diffusers27python -m venv .venv28source .venv/bin/activate29pip install -r requirements.txt30```31 32Then run the following python code:33 34```python35from pathlib import Path36from lambda_diffusers import StableDiffusionImageEmbedPipeline37from PIL import Image38import torch39 40device = "cuda" if torch.cuda.is_available() else "cpu"41pipe = StableDiffusionImageEmbedPipeline.from_pretrained("lambdalabs/sd-image-variations-diffusers")42pipe = pipe.to(device)43 44im = Image.open("your/input/image/here.jpg")45num_samples = 446image = pipe(num_samples*[im], guidance_scale=3.0)47image = image["sample"]48 49base_path = Path("outputs/im2im")50base_path.mkdir(exist_ok=True, parents=True)51for idx, im in enumerate(image):52 im.save(base_path/f"{idx:06}.jpg")53```54 55 56# Training57 58**Training Data**59The model developers used the following dataset for training the model:60 61- LAION-2B (en) and subsets thereof (see next section)62 63**Training Procedure**64This model is fine tuned from Stable Diffusion v1-3 where the text encoder has been replaced with an image encoder. The training procedure is the same as for Stable Diffusion except for the fact that images are encoded through a ViT-L/14 image-encoder including the final projection layer to the CLIP shared embedding space.65 66- **Hardware:** 4 x A6000 GPUs (provided by [Lambda GPU Cloud](https://lambdalabs.com/service/gpu-cloud))67- **Optimizer:** AdamW68- **Gradient Accumulations**: 169- **Steps**: 87,00070- **Batch:** 6 x 4 = 2471- **Learning rate:** warmup to 0.0001 for 1,000 steps and then kept constant72 73Training was done using a [modified version of the original Stable Diffusion training code]((https://github.com/justinpinkney/stable-diffusion), the original version of the weights is [here](https://huggingface.co/lambdalabs/stable-diffusion-image-conditioned).74 75 76# Uses77_The following section is adapted from the [Stable Diffusion model card](https://huggingface.co/CompVis/stable-diffusion-v1-4)_78 79## Direct Use 80The model is intended for research purposes only. Possible research areas and81tasks include82 83- Safe deployment of models which have the potential to generate harmful content.84- Probing and understanding the limitations and biases of generative models.85- Generation of artworks and use in design and other artistic processes.86- Applications in educational or creative tools.87- Research on generative models.88 89Excluded uses are described below.90 91 ### Misuse, Malicious Use, and Out-of-Scope Use92 93The model should not be used to intentionally create or disseminate images that create hostile or alienating environments for people. This includes generating images that people would foreseeably find disturbing, distressing, or offensive; or content that propagates historical or current stereotypes.94 95#### Out-of-Scope Use96The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.97 98#### Misuse and Malicious Use99Using the model to generate content that is cruel to individuals is a misuse of this model. This includes, but is not limited to:100 101- Generating demeaning, dehumanizing, or otherwise harmful representations of people or their environments, cultures, religions, etc.102- Intentionally promoting or propagating discriminatory content or harmful stereotypes.103- Impersonating individuals without their consent.104- Sexual content without consent of the people who might see it.105- Mis- and disinformation106- Representations of egregious violence and gore107- Sharing of copyrighted or licensed material in violation of its terms of use.108- Sharing content that is an alteration of copyrighted or licensed material in violation of its terms of use.109 110## Limitations and Bias111 112### Limitations113 114- The model does not achieve perfect photorealism115- The model cannot render legible text116- The model does not perform well on more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”117- Faces and people in general may not be generated properly.118- The model was trained mainly with English captions and will not work as well in other languages.119- The autoencoding part of the model is lossy120- The model was trained on a large-scale dataset121 [LAION-5B](https://laion.ai/blog/laion-5b/) which contains adult material122 and is not fit for product use without additional safety mechanisms and123 considerations.124- No additional measures were used to deduplicate the dataset. As a result, we observe some degree of memorization for images that are duplicated in the training data.125 The training data can be searched at [https://rom1504.github.io/clip-retrieval/](https://rom1504.github.io/clip-retrieval/) to possibly assist in the detection of memorized images.126 127### Bias128 129While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases. 130Stable Diffusion v1 was trained on subsets of [LAION-2B(en)](https://laion.ai/blog/laion-5b/), 131which consists of images that are primarily limited to English descriptions. 132Texts and images from communities and cultures that use other languages are likely to be insufficiently accounted for. 133This affects the overall output of the model, as white and western cultures are often set as the default. Further, the 134ability of the model to generate content with non-English prompts is significantly worse than with English-language prompts.135 136### Safety Module137 138The intended use of this model is with the [Safety Checker](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) in Diffusers. 139This checker works by checking model outputs against known hard-coded NSFW concepts.140The concepts are intentionally hidden to reduce the likelihood of reverse-engineering this filter.141Specifically, the checker compares the class probability of harmful concepts in the embedding space of the `CLIPModel` *after generation* of the images. 142The concepts are passed into the model with the generated image and compared to a hand-engineered weight for each NSFW concept.143 144 145*This model card was written by: Justin Pinkney and is based on the [Stable Diffusion model card](https://huggingface.co/CompVis/stable-diffusion-v1-4).*