
AIOmarRehan/Mel_Spectrogram_Images_for_Audio_Classification
Mel-Spectrogram Image Dataset (Generated via Custom Pipeline) > This dataset was fully generated through my notebook > “Building an Audio Classification Pipeline with DL” available on my profile. > It represents a complete end-to-end transformation from raw audio to clean, balanced Mel-spectrogram images suitable for deep learning. Dataset Summary Property Description Number of Classes 13 distinct audio categories Original Audio per Class ~40 raw… See the full description on the dataset page: https://huggingface.co/datasets/AIOmarRehan/Mel_Spectrogram_Images_for_Audio_Classification.
212
1---2license: mit3dataset_info:4 features:5 - name: image6 dtype: image7 - name: label8 dtype:9 class_label:10 names:11 '0': Baby cry12 '1': Chainsaw13 '2': Clock tick14 '3': Cow15 '4': Dog16 '5': Fire crackling17 '6': Frog18 '7': Helicopter19 '8': Person sneeze20 '9': Pig21 '10': Rain22 '11': Rooster23 '12': Sea waves24 splits:25 - name: train26 num_bytes: 6261831827 num_examples: 162528 download_size: 5857729229 dataset_size: 6261831830configs:31- config_name: default32 data_files:33 - split: train34 path: data/train-*35---36 37## Mel-Spectrogram Image Dataset (Generated via Custom Pipeline)38 39> **This dataset was fully generated through my notebook40> *“Building an Audio Classification Pipeline with DL”* available on my profile.**41> It represents a complete end-to-end transformation from raw audio to clean, balanced Mel-spectrogram images suitable for deep learning.42 43---44 45### **Dataset Summary**46 47| Property | Description |48| ---------------------------- | --------------------------------------------- |49| **Number of Classes** | 13 distinct audio categories |50| **Original Audio per Class** | ~40 raw recordings |51| **Average Duration** | ~5 seconds per audio file |52| **Final Images per Class** | 125 Mel-spectrogram images |53| **Final Dataset Size** | 13 × 125 = **1625 images** |54| **Sampling Rate** | Standardized to **16 kHz** |55| **Audio Length** | Uniform **5-second** fixed length |56| **Spectrogram Type** | 128-Mel frequency bins, `melspectrogram → dB` |57 58---59 60### **High-Level Processing Pipeline**61 62The dataset was built using a **fully custom preprocessing, cleaning, and augmentation pipeline**, implemented step-by-step in the notebook.63 64#### **1. Data Ingestion**65 66* Loaded all raw audio files from 13 folders67* Parsed metadata (sample rate, duration, amplitude, SNR, etc.)68 69#### **2. Cleaning & Standardization**70 71* Removed corrupt, silent, or unreadable audio files72* Normalized peak amplitudes73* Trimmed silence using `librosa.effects.trim`74* Performed noise reduction (`noisereduce`)75* Converted all audio to **mono**76* Resampled to **16,000 Hz**77* Ensured each sample is **exactly 5 seconds**78 79#### **3. Dataset Balancing**80 81* Used augmentation for minority classes82* Used controlled undersampling or oversampling where necessary83* Verified all classes contain equal counts84 85#### **4. Audio Augmentation (Used for Balancing & Variability)**86 87Augmentations built with **audiomentations**:88 89* Time shift90* Pitch shift91* Time stretching92* Gaussian noise injection93* Random perturbations for robustness94 95#### **5. Splitting & Chunking**96 97* Long samples were split into 5-second chunks98* Shorter samples padded to match target duration99* Ensured strict uniformity before feature extraction100 101#### **6. Mel-Spectrogram Generation**102 103Converted all cleaned audio files into Mel-spectrogram images using:104 105* `n_fft = 1024`106* `hop_length = 512`107* `n_mels = 128`108* Converted to decibel scale (`power_to_db`)109* Saved images in **RGBA format** to preserve color-mapped spectral information110 111---112 113### **Final Technical Description**114 115> **“The final dataset consists of 13 audio classes, each expanded to exactly 125 Mel-spectrogram images through a rigorous pipeline of cleaning, normalization, augmentation, noise reduction, resampling, duration standardization, and feature extraction. All processing steps were implemented in my notebook *‘Building an Audio Classification Pipeline with DL,’* where raw 5-second audio recordings were transformed into high-quality Mel-spectrogram images suitable for deep learning models.”**116 117---118 119### **Examples of the Images**120 121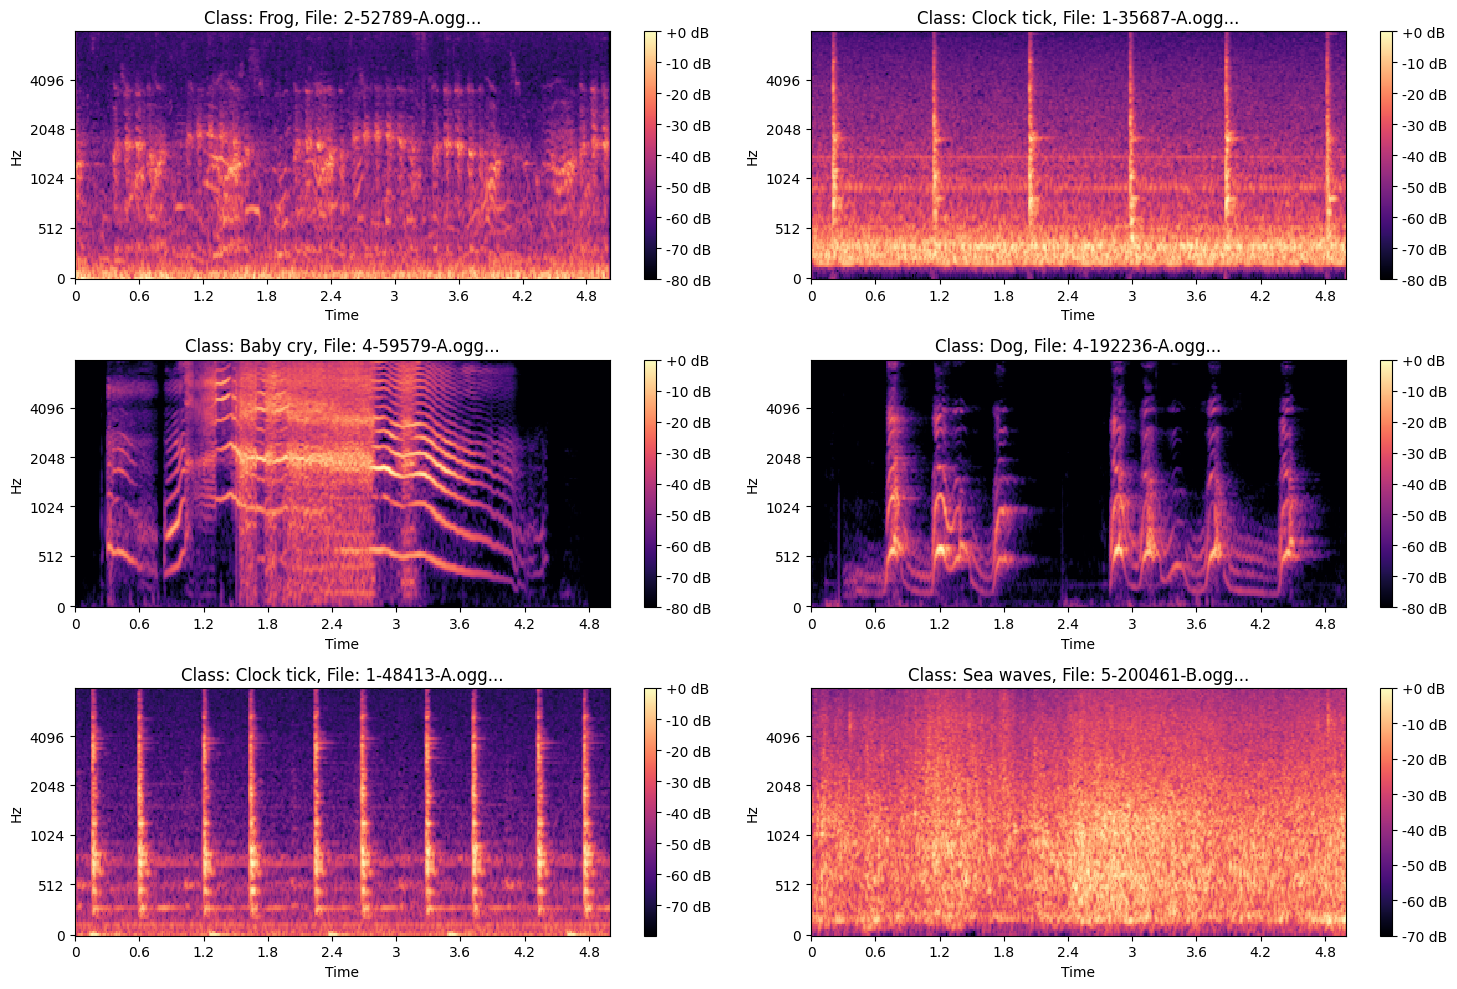122 123