
iccv23-diffusers-demo/stable-diffusion-image-variations
1
1import gradio as gr2import torch3from PIL import Image4from torchvision import transforms5 6from diffusers import StableDiffusionImageVariationPipeline7 8def main(9 input_im,10 scale=3.0,11 n_samples=4,12 steps=25,13 seed=0,14 ):15 generator = torch.Generator(device=device).manual_seed(int(seed))16 17 tform = transforms.Compose([18 transforms.ToTensor(),19 transforms.Resize(20 (224, 224),21 interpolation=transforms.InterpolationMode.BICUBIC,22 antialias=False,23 ),24 transforms.Normalize(25 [0.48145466, 0.4578275, 0.40821073],26 [0.26862954, 0.26130258, 0.27577711]),27 ])28 inp = tform(input_im).to(device)29 30 images_list = pipe(31 inp.tile(n_samples, 1, 1, 1),32 guidance_scale=scale,33 num_inference_steps=steps,34 generator=generator,35 )36 37 images = []38 for i, image in enumerate(images_list["images"]):39 if(images_list["nsfw_content_detected"][i]):40 safe_image = Image.open(r"unsafe.png")41 images.append(safe_image)42 else:43 images.append(image)44 return images45 46 47description = \48"""49__Now using Image Variations v2!__50 51Generate variations on an input image using a fine-tuned version of Stable Diffision.52Trained by [Justin Pinkney](https://www.justinpinkney.com) ([@Buntworthy](https://twitter.com/Buntworthy)) at [Lambda](https://lambdalabs.com/)53 54This version has been ported to 🤗 Diffusers library, see more details on how to use this version in the [Lambda Diffusers repo](https://github.com/LambdaLabsML/lambda-diffusers).55For the original training code see [this repo](https://github.com/justinpinkney/stable-diffusion).56 57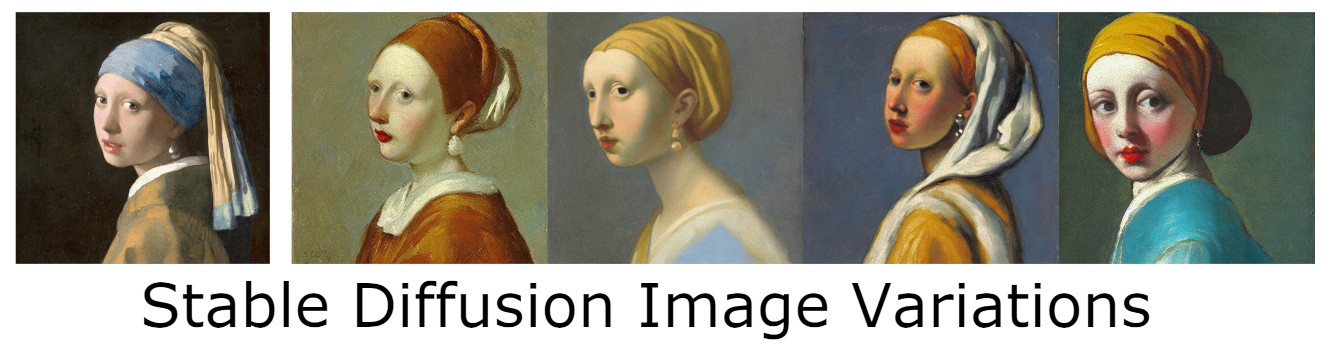58 59"""60 61article = \62"""63## How does this work?64 65The normal Stable Diffusion model is trained to be conditioned on text input. This version has had the original text encoder (from CLIP) removed, and replaced with66the CLIP _image_ encoder instead. So instead of generating images based a text input, images are generated to match CLIP's embedding of the image.67This creates images which have the same rough style and content, but different details, in particular the composition is generally quite different.68This is a totally different approach to the img2img script of the original Stable Diffusion and gives very different results.69 70The model was fine tuned on the [LAION aethetics v2 6+ dataset](https://laion.ai/blog/laion-aesthetics/) to accept the new conditioning.71Training was done on 8xA100 GPUs on [Lambda GPU Cloud](https://lambdalabs.com/service/gpu-cloud).72More details are on the [model card](https://huggingface.co/lambdalabs/sd-image-variations-diffusers).73"""74 75device = "cuda" if torch.cuda.is_available() else "cpu"76pipe = StableDiffusionImageVariationPipeline.from_pretrained(77 "lambdalabs/sd-image-variations-diffusers",78 )79pipe = pipe.to(device)80 81inputs = [82 gr.Image(),83 gr.Slider(0, 25, value=3, step=1, label="Guidance scale"),84 gr.Slider(1, 4, value=1, step=1, label="Number images"),85 gr.Slider(5, 50, value=25, step=5, label="Steps"),86 gr.Number(0, label="Seed", precision=0)87]88output = gr.Gallery(label="Generated variations")89output.style(grid=2)90 91examples = [92 ["examples/vermeer.jpg", 3, 1, 25, 0],93 ["examples/matisse.jpg", 3, 1, 25, 0],94]95 96demo = gr.Interface(97 fn=main,98 title="Stable Diffusion Image Variations",99 description=description,100 article=article,101 inputs=inputs,102 outputs=output,103 examples=examples,104 )105demo.launch()106